diff --git a/.github/social-preview.png b/.github/social-preview.png new file mode 100644 index 0000000..65933e4 Binary files /dev/null and b/.github/social-preview.png differ diff --git a/.github/workflows/ci.yml b/.github/workflows/ci.yml index 5adad75..5cf7c32 100644 --- a/.github/workflows/ci.yml +++ b/.github/workflows/ci.yml @@ -23,4 +23,7 @@ jobs: run: | cargo run -q -- --logprobs-file examples/logprobs/cuyp.json --threshold 0.6 --format json | tee report.json grep -q '"text": " Dordrecht"' report.json + cargo run -q -- --logprobs-file examples/logprobs/cuyp.json --threshold 0.6 --format html -o report.html + grep -q 'class="f" id="s2"' report.html + cargo run -q -- --logprobs-file examples/logprobs/cuyp.json --threshold 0.6 --format markdown | grep -q 'üsseldorf' cargo run -q --example detect diff --git a/CHANGELOG.md b/CHANGELOG.md index 64d9200..a061250 100644 --- a/CHANGELOG.md +++ b/CHANGELOG.md @@ -1,5 +1,14 @@ # Changelog +## Unreleased + +- New: `--format html` in detect mode writes a self-contained report page (no scripts, no external assets, light and dark): the answer as a confidence heatmap, a per-token probability strip, and each flagged span with bars for the alternatives. Hover or focus any word for its probability and alternatives. +- New: `--format markdown` in detect mode writes a compact report for pull requests, issues and `$GITHUB_STEP_SUMMARY`. +- Terminal output in detect mode is now a heatmap with aligned alternative bars per span. Confident tokens keep the terminal's own color so it reads on light and dark themes; `NO_COLOR` is honored. +- `--help` lists examples. Emoji removed from the visualizer headers. +- New `report` module (`report::terminal`, `report::html`, `report::markdown`, `report::heat`). +- Project site at https://mattbusel.github.io/LLM-Hallucination-Detection-Script/. + ## 0.2.0 (2026-09-25) - New: hallucination-risk detection from token logprobs. `--logprobs-file` reads a Chat Completions response (or its `logprobs` block, or a bare token array) and flags words below `--threshold` (default 0.5), with the alternatives the model considered. diff --git a/Cargo.toml b/Cargo.toml index 8f5a201..c177d78 100644 --- a/Cargo.toml +++ b/Cargo.toml @@ -6,6 +6,8 @@ description = "Flag low-confidence spans in LLM output from token logprobs, and license = "MIT" repository = "https://github.com/Mattbusel/LLM-Hallucination-Detection-Script" readme = "README.md" +homepage = "https://mattbusel.github.io/LLM-Hallucination-Detection-Script/" +exclude = ["docs/", ".github/"] keywords = ["llm", "hallucination", "logprobs", "confidence", "cli"] categories = ["command-line-utilities", "text-processing"] diff --git a/README.md b/README.md index 861faa5..86f0ab9 100644 --- a/README.md +++ b/README.md @@ -1,38 +1,29 @@ -# LLM Hallucination Detector + + + LLM Hallucination Detector. Find the words your model wasn't sure about. A real Llama 3.1 answer, 'Aelbert Cuyp died in 1691 in Dordrecht, Netherlands.', shown as a confidence heatmap with Aelbert and Dordrecht flagged, and the alternatives at 'ord': ord 0.57, üsseldorf 0.39, elf 0.03. + -[![CI](https://github.com/Mattbusel/LLM-Hallucination-Detection-Script/actions/workflows/ci.yml/badge.svg)](https://github.com/Mattbusel/LLM-Hallucination-Detection-Script/actions/workflows/ci.yml) -[![crates.io](https://img.shields.io/crates/v/llm-token-visualizer.svg)](https://crates.io/crates/llm-token-visualizer) -[![License: MIT](https://img.shields.io/badge/license-MIT-blue.svg)](LICENSE) +

+ Project site  ·  + crates.io  ·  + Binaries  ·  + What it cannot tell you +

+ CI + crates.io +

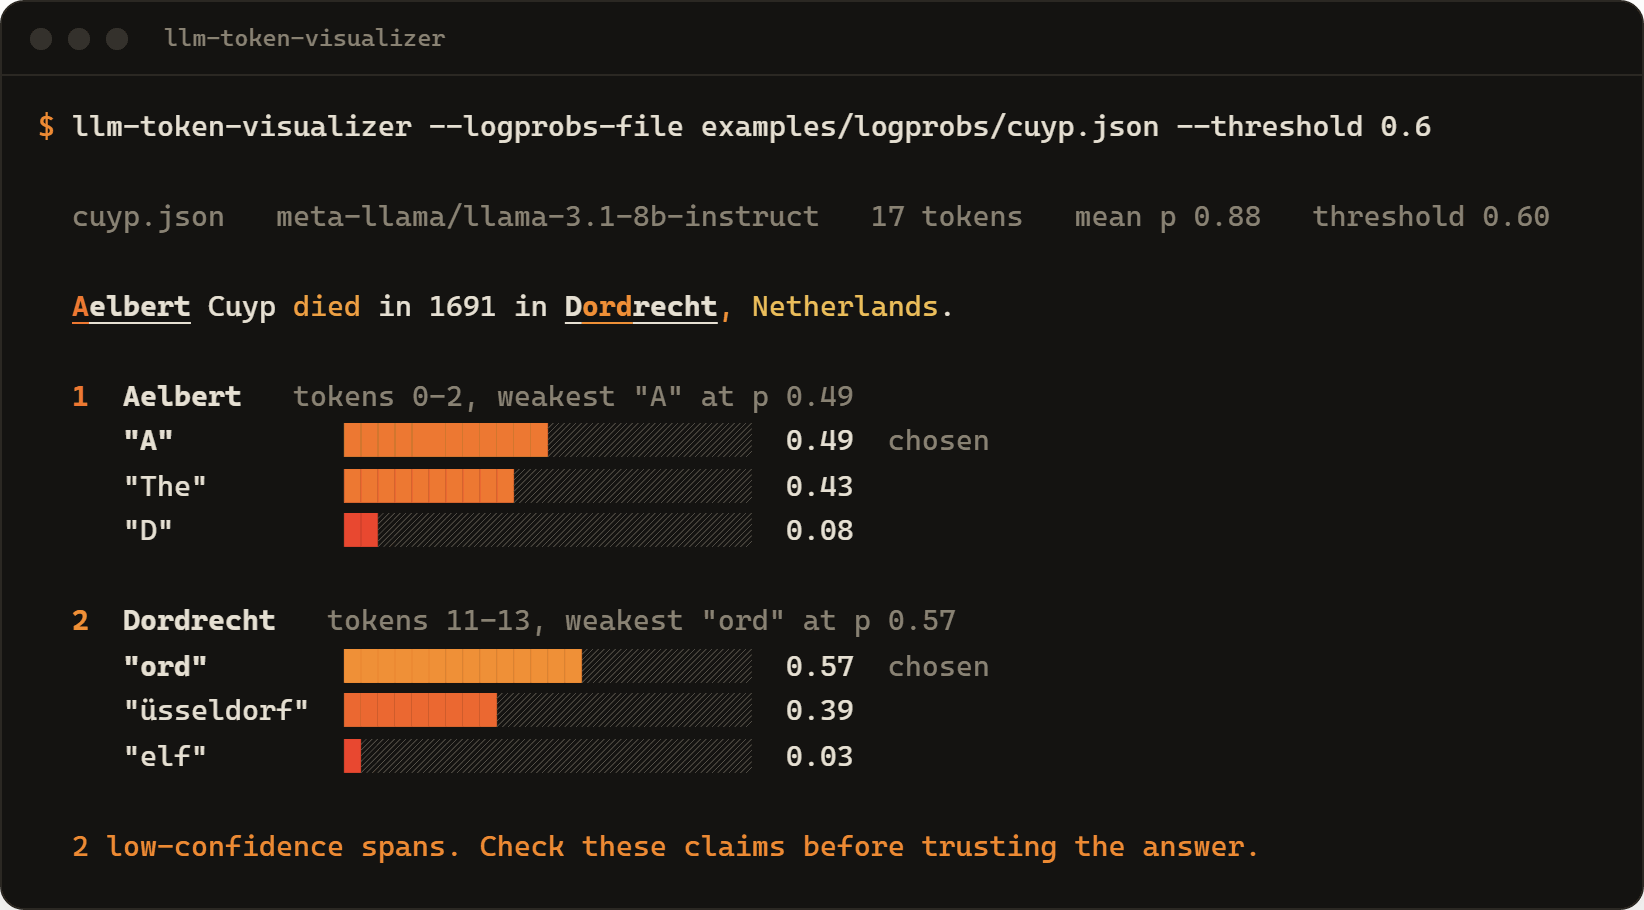
-A Rust CLI and library that reads an LLM answer's token log probabilities and flags the words the model was unsure about, with the alternatives it was weighing at that point. It can also render per-token confidence as colored terminal output, a standalone HTML report, or Markdown. +A Rust CLI and library that reads an LLM answer's token log probabilities and flags the words the model was unsure about, with the alternatives it was weighing at that point. Output as a colored terminal report, a self-contained HTML page, Markdown, or JSON. -Hallucinations often sit where the model's confidence drops: a name, a date, a city it half-remembers. If your API returns `logprobs` (OpenAI and many OpenAI-compatible servers do), this tool shows you those spots in one command. +Hallucinations often sit where the model's confidence drops: a name, a date, a city it half-remembers. If your API returns `logprobs` (OpenAI and many OpenAI-compatible servers do), this tool shows you those spots in one command. The [project site](https://mattbusel.github.io/LLM-Hallucination-Detection-Script/) lets you try it on the bundled samples with a threshold slider. -```text -$ llm-token-visualizer --logprobs-file examples/logprobs/cuyp.json --threshold 0.6 -... -Aelbert Cuyp died in 1691 in Dordrecht, Netherlands. - - [uncertain] 'Aelbert' (tokens 0-2): p=0.49 at "A"; model also considered "The" (0.43), "D" (0.08) - [uncertain] ' Dordrecht' (tokens 11-13): p=0.57 at "ord"; model also considered "üsseldorf" (0.39), "elf" (0.03) - -2 low-confidence span(s) at threshold 0.60 (17 tokens, mean p=0.88). -Check these claims before trusting the answer. -``` - -That is a real response from Llama 3.1 8B Instruct. The answer happens to be right, but the model gave Düsseldorf a 39% chance, which is exactly the kind of claim to double-check. The "Aelbert" flag is the model choosing between starting with the name or with "The": low probability can be about phrasing, not facts. - -## Install - -Prebuilt binaries for Linux, macOS (Intel and Apple Silicon) and Windows are attached to each [GitHub Release](https://github.com/Mattbusel/LLM-Hallucination-Detection-Script/releases/latest). Download the archive for your platform, unpack it, and run `llm-token-visualizer` (the archive includes the sample responses under `samples/`). - -Or install from crates.io with a Rust toolchain: +## Quick start ```bash cargo install llm-token-visualizer ``` -## Quick start +Or download a prebuilt binary for Linux, macOS (Intel and Apple Silicon) or Windows from the [latest release](https://github.com/Mattbusel/LLM-Hallucination-Detection-Script/releases/latest); each archive includes the sample responses under `samples/`. ```bash git clone https://github.com/Mattbusel/LLM-Hallucination-Detection-Script @@ -41,18 +32,41 @@ cd LLM-Hallucination-Detection-Script # Offline: analyze a bundled real response, no API key needed cargo run -- --logprobs-file examples/logprobs/cuyp.json --threshold 0.6 -# All four bundled samples, through the library API -cargo run --example detect - -# Machine-readable report -cargo run -- --logprobs-file examples/logprobs/cuyp.json --format json - # Live: ask a model and analyze its answer (any OpenAI-compatible API) export OPENAI_API_KEY=sk-... cargo run -- --live "Who was the second person to walk on the Moon?" --save answer.json ``` -### How detection works +Terminal output of llm-token-visualizer on examples/logprobs/cuyp.json: the answer with Aelbert and Dordrecht underlined, then bars for the candidates at each weak token: A 0.49, The 0.43, D 0.08, and ord 0.57, üsseldorf 0.39, elf 0.03. + +That is a real response from Llama 3.1 8B Instruct. The answer happens to be right, but the model gave Düsseldorf a 39% chance, which is exactly the kind of claim to double-check. The "Aelbert" flag is the model choosing between starting with the name or with "The": low probability can be about phrasing, not facts. + +## What it flags on the bundled samples + +Output of `cargo run --example detect` (threshold 0.6), four real Llama 3.1 8B answers: + +| Sample | Flagged | Weakest token and what the model also considered | +|---|---|---| +| `cuyp.json` | Aelbert | `"A"` 0.49; `"The"` 0.43, `"D"` 0.08 | +| | Dordrecht | `"ord"` 0.57; `"üsseldorf"` 0.39, `"elf"` 0.03 | +| `tour-de-france.json` | Stephen | `"Stephen"` 0.49; `"The"` 0.43, `"Steven"` 0.03 | +| | -Vagabond | `"-V"` 0.57; `"–"` 0.21, `" -"` 0.14 | +| `eiffel.json` | Gustave | `" Gust"` 0.57; `" French"` 0.39, `" the"` 0.03 | +| | Compagnie | `" Comp"` 0.53; `" and"` 0.29, `" E"` 0.12 | +| | on | `" on"` 0.49; `" to"` 0.49, `" in"` 0.01 | +| | during | `" during"` 0.32; `" for"` 0.32, `" at"` 0.25 | +| `moonwalk.json` | was, which, during | phrasing words only; see below | + +## What it cannot tell you + + + + The moonwalk sample: 'Pete Conrad was the second person to walk on the Moon'. Pete Conrad is outlined as wrong but not flagged: P 0.72, ete 0.76, Conrad 1.00. Flagged instead: was 0.60, which 0.14, during 0.55. + + +Low token probability is a useful signal, not a fact checker. The bundled `moonwalk.json` sample shows the failure mode: the model answers "Pete Conrad was the second person to walk on the Moon" (it was Buzz Aldrin) with at least 72% probability on every token of the name, so the wrong name is not flagged; only phrasing words like "which" are. Models can be confidently wrong. Use this to decide where to look first, not to certify an answer. + +## How detection works 1. Each token's probability is `exp(logprob)`. 2. Tokens are grouped into words (a subword like `ord` in `Dordrecht` belongs to its word). @@ -61,11 +75,39 @@ cargo run -- --live "Who was the second person to walk on the Moon?" --save answ Raise the threshold to catch more (and noisier) spans, lower it to see only the shakiest ones. -### Input +## Output formats + +| `--format` | What you get | +|---|---| +| `terminal` (default) | The answer as a heatmap, each flagged span with bars for the alternatives. Honors `NO_COLOR`. | +| `html` | One self-contained page (no scripts, no external assets, light and dark). Hover or focus any word for its probability and alternatives. | +| `markdown` | A compact report for a pull request, an issue, or `$GITHUB_STEP_SUMMARY`. | +| `json` | The spans, probabilities and alternatives, for scripts. | + +```bash +llm-token-visualizer --logprobs-file answer.json --format html -o report.html +``` + +HTML report for the eiffel sample in dark mode: the answer as a heatmap with four wavy-underlined spans, a per-token probability strip, and bars for the alternatives at each span. + +### Use it in CI or scripts + +`--fail-on-flag` exits with status 2 when any span is flagged, so you can gate a pipeline on it or route flagged answers to review: + +```bash +llm-token-visualizer --logprobs-file answer.json --fail-on-flag --format json -o report.json +llm-token-visualizer --logprobs-file answer.json --format markdown >> "$GITHUB_STEP_SUMMARY" +``` + +
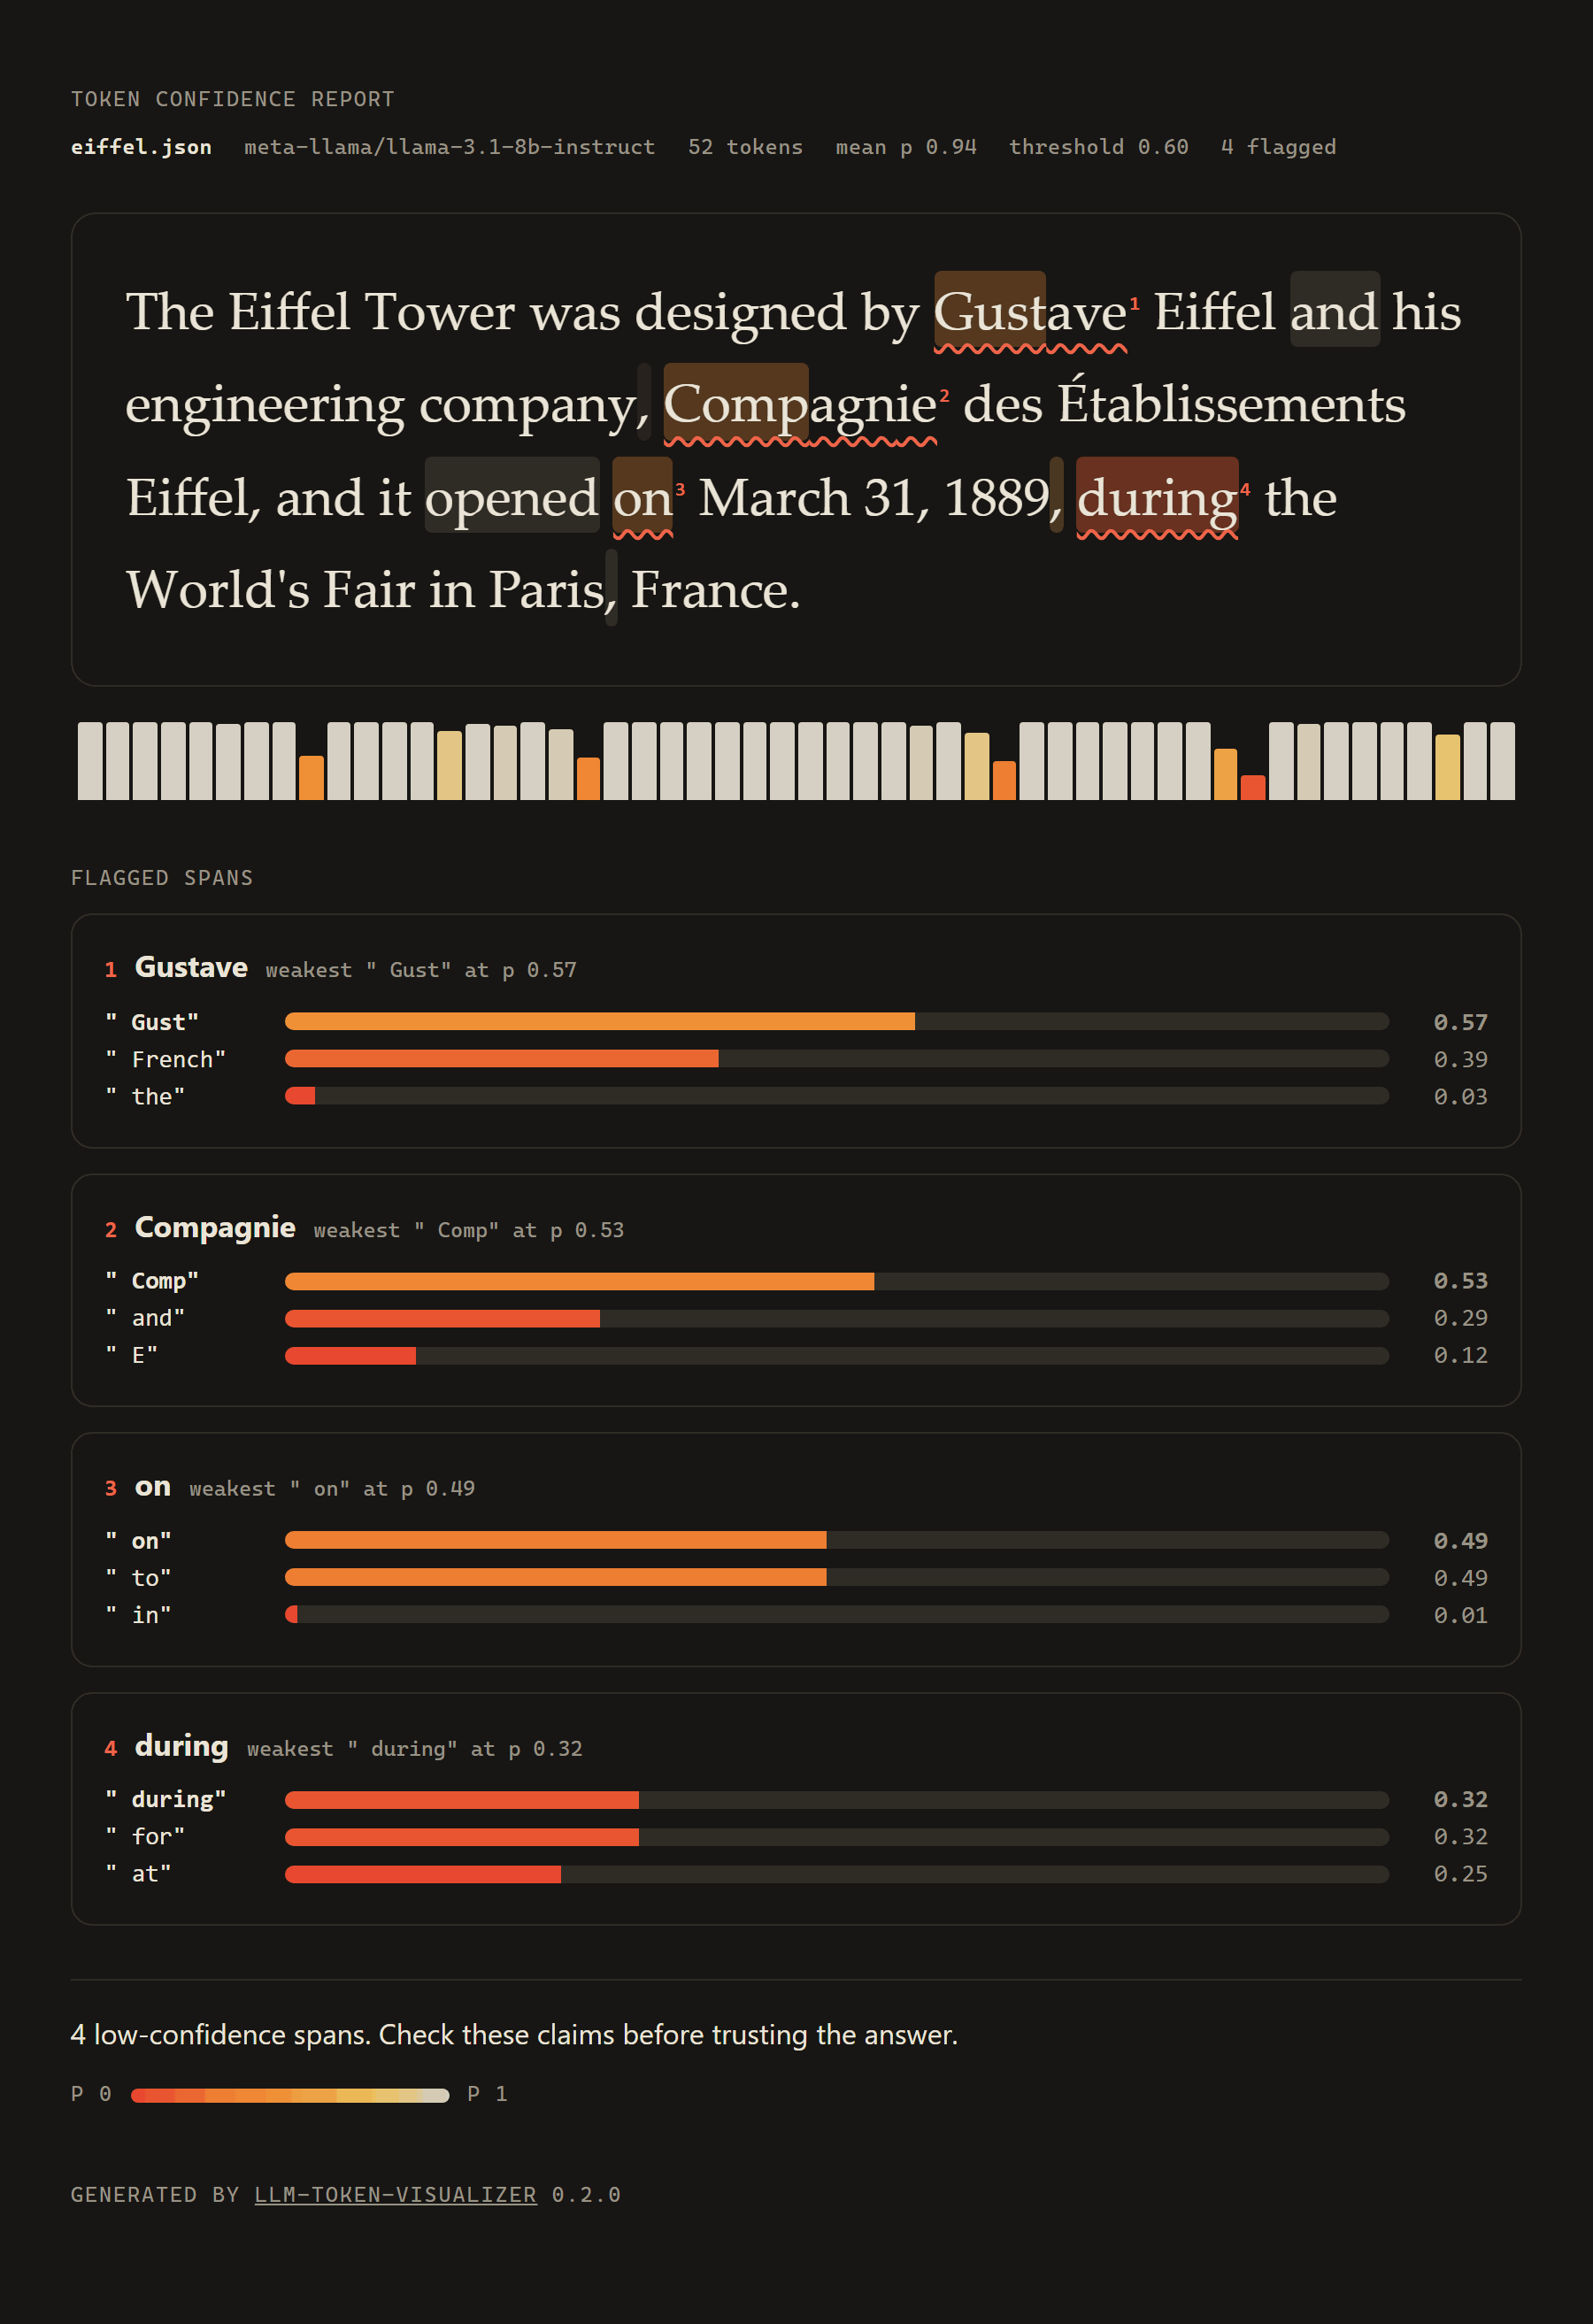
+Input formats `--logprobs-file` accepts a full Chat Completions response saved as JSON, just its `logprobs` object (`{"content": [...]}`), or a bare array of `{"token", "logprob", "top_logprobs"}` entries. Use `-` to read stdin. Request completions with `"logprobs": true` and, for alternatives, `"top_logprobs": 3` or more. Special tokens such as `<|eot_id|>` are ignored. -### Live mode +
+ +
+Live mode `--live ""` sends the prompt with temperature 0, `logprobs: true` and `top_logprobs: 3`, then analyzes the answer. @@ -78,19 +120,10 @@ Flags: `--model` (default `gpt-4o-mini`), `--max-tokens` (default 200), and `--s The bundled samples were fetched through the Hugging Face router (`meta-llama/Llama-3.1-8B-Instruct:novita`). Build with `--no-default-features` for an offline-only binary without an HTTP client. -### Use it in CI or scripts - -`--fail-on-flag` exits with status 2 when any span is flagged, so you can gate a pipeline on it or route flagged answers to review: +
-```bash -llm-token-visualizer --logprobs-file answer.json --fail-on-flag --format json -o report.json -``` - -## What it cannot tell you - -Low token probability is a useful signal, not a fact checker. The bundled `moonwalk.json` sample shows the failure mode: the model answers "Pete Conrad was the second person to walk on the Moon" (it was Buzz Aldrin) with at least 72% probability on every token of the name, so the wrong name is not flagged; only phrasing words like "which" are. Models can be confidently wrong. Use this to decide where to look first, not to certify an answer. - -## Visualizing your own confidence scores +
+Visualizing your own confidence scores If you already have per-token scores from another source, the visualizer mode renders them with a five-band color scale (very low < 0.3, low < 0.5, medium < 0.7, high < 0.9, very high) and labeled spans (`fact`, `uncertain`, `hallucination`, or any label): @@ -125,13 +158,16 @@ Confidence file format: `start` is inclusive and `end` is exclusive, both as token indices. -### Library use +
+ +
+Library use The crate is named `llm-token-visualizer`. ```rust -use llm_token_visualizer::detect::{detect, parse_logprobs, to_token_analysis}; -use llm_token_visualizer::visualize_tokens; +use llm_token_visualizer::detect::{detect, parse_logprobs}; +use llm_token_visualizer::report::{self, Meta}; let tokens = parse_logprobs(&response_json)?; let report = detect(&tokens, 0.5); @@ -139,34 +175,42 @@ for span in &report.spans { println!("{}: {}", span.text, span.describe()); } -// Render the same result as HTML -let analysis = to_token_analysis(&tokens, &report); -let html = visualize_tokens(&report.text, &analysis, "html", None)?; +// The same result as a standalone HTML page, Markdown, or colored terminal text +let meta = Meta::from_response("answer.json", &response_json); +let html = report::html(&tokens, &report, &meta); +let md = report::markdown(&tokens, &report, &meta); ``` -`analyze_with_issues` and `quick_analyze` are still available. +`detect::to_token_analysis` plus `visualize_tokens` still render detections with the visualizer's renderers, and `analyze_with_issues` and `quick_analyze` are still available. + +
-## Repository layout +
+Repository layout ``` src/ main.rs CLI (clap) lib.rs public API: visualize_tokens, quick_analyze, analyze_with_issues detect.rs logprob parsing and low-confidence span detection + report.rs detect-mode reports: terminal heatmap, HTML page, Markdown live.rs OpenAI-compatible API client for --live (feature "live") data.rs TokenAnalysis, TokenInfo, TokenFlag, ConfidenceLevel - renderer.rs Terminal, HTML and Markdown renderers + renderer.rs Terminal, HTML and Markdown renderers for the visualizer mode utils.rs tokenizer for demos, metrics, issue detection examples/logprobs/ real Llama 3.1 8B responses with logprobs examples/detect.rs library example over those samples +docs/ project site (GitHub Pages) and README images demo_data.json, sample_text.txt example input for the visualizer rust_mvps/ design sketches, see below real-time fact-checking DAG engine.cpp standalone C++ sketch, see below ``` +
+ ## Status and limitations -The Rust crate in `src/` is the working part of this repo: it builds, has unit tests, and CI runs fmt, clippy, tests and a detector smoke test on every push. +The Rust crate in `src/` is the working part of this repo: it builds, has unit tests, and CI runs fmt, clippy, tests and detector smoke tests (JSON, HTML and Markdown) on every push. The rest is exploratory and should be read as design notes, not shipped features: diff --git a/docs/assets/confidently-wrong-dark.png b/docs/assets/confidently-wrong-dark.png new file mode 100644 index 0000000..1d084d1 Binary files /dev/null and b/docs/assets/confidently-wrong-dark.png differ diff --git a/docs/assets/confidently-wrong-light.png b/docs/assets/confidently-wrong-light.png new file mode 100644 index 0000000..51d3880 Binary files /dev/null and b/docs/assets/confidently-wrong-light.png differ diff --git a/docs/assets/hero-dark.png b/docs/assets/hero-dark.png new file mode 100644 index 0000000..5590b80 Binary files /dev/null and b/docs/assets/hero-dark.png differ diff --git a/docs/assets/hero-light.png b/docs/assets/hero-light.png new file mode 100644 index 0000000..3304c6c Binary files /dev/null and b/docs/assets/hero-light.png differ diff --git a/docs/assets/report-html.png b/docs/assets/report-html.png new file mode 100644 index 0000000..79d9319 Binary files /dev/null and b/docs/assets/report-html.png differ diff --git a/docs/assets/social-preview.png b/docs/assets/social-preview.png new file mode 100644 index 0000000..65933e4 Binary files /dev/null and b/docs/assets/social-preview.png differ diff --git a/docs/assets/terminal-cuyp.png b/docs/assets/terminal-cuyp.png new file mode 100644 index 0000000..96ddba6 Binary files /dev/null and b/docs/assets/terminal-cuyp.png differ diff --git a/docs/index.html b/docs/index.html new file mode 100644 index 0000000..f90af21 --- /dev/null +++ b/docs/index.html @@ -0,0 +1,416 @@ + + + + + + +LLM Hallucination Detector: token confidence from logprobs + + + + + + + + + +
+ + +
+
Rust CLI and library  /  MIT
+

Find the words your model wasn’t sure about.

+

Hand it an LLM answer with token log probabilities. It flags the words where the model's confidence dropped and shows what it almost said instead. Offline on a saved response, or live against any OpenAI-compatible API.

+
+
cargo install llm-token-visualizer
+
+

Or grab a prebuilt binary for Linux, macOS or Windows from the latest release.

+ +
+
+
+ +
+
+
+

+

+ +
+
+
+
Flagged spans and what the model weighed
+
+

+
+
+
+

Real responses from Llama 3.1 8B Instruct, bundled in examples/logprobs/. The detection runs in your browser with the same rules as the CLI; hover or tap any word for its probability and alternatives.

+
+
+ +
+
In your terminal
+

One command, no API key.

+

Point it at a saved Chat Completions response. The answer comes back as a heatmap, every flagged span lists the candidates at its weakest token, and --fail-on-flag turns it into a CI gate.

+
+
Terminal output for the cuyp sample: the answer with Aelbert and Dordrecht underlined, then bars for the alternatives A 0.49, The 0.43, D 0.08 and ord 0.57, üsseldorf 0.39, elf 0.03.
llm-token-visualizer --logprobs-file examples/logprobs/cuyp.json --threshold 0.6
+
+
git clone https://github.com/Mattbusel/LLM-Hallucination-Detection-Script
+
# offline, on a bundled real response
+cargo run -- --logprobs-file examples/logprobs/cuyp.json --threshold 0.6
+
+# all four samples through the library API
+cargo run --example detect
+
+# live: ask a model, analyze its answer
+export OPENAI_API_KEY=sk-...
+cargo run -- --live "Who was the second person to walk on the Moon?" \
+  --save answer.json
+

Live mode works with any server that returns logprobs: set OPENAI_BASE_URL, for example to https://router.huggingface.co/v1. Anthropic's API does not return logprobs.

+
+
+
+ +
+
How it works
+

Four rules, no model of its own.

+

No second LLM, no embeddings, no network call in offline mode. Just the numbers the model already gave you, read carefully.

+
+
+ +
+
What it cannot tell you
+

Models can be confidently wrong.

+

Low token probability is a place to look, not a fact check. This bundled answer is wrong, and the detector does not catch it.

+

+
+

The wrong name is not flagged

+

The second person on the Moon was Buzz Aldrin. The model put at least 0.72 on every token of Pete Conrad, and Aldrin is not among the top 3 alternatives it returned at any of them.

+

What got flagged instead

+

Phrasing words. Use the flags to decide where to look first, never to certify an answer.

+
+
+
+ +
+
Output formats
+

Terminal, HTML, Markdown, JSON.

+

The same report in the shape your workflow needs. All four are produced by the CLI from the same detection.

+
+

--format html

A single self-contained page: no scripts, no external assets, light and dark. Hover any word for its alternatives.

+
HTML report for the eiffel sample in dark mode with four flagged spans and probability bars.
+
llm-token-visualizer --logprobs-file answer.json --format html -o report.html
+

--format markdown

Paste into a pull request, an issue, or $GITHUB_STEP_SUMMARY.

+

+      

--format json and --fail-on-flag

Machine-readable spans, and exit status 2 when anything is flagged, so a pipeline can route answers to review.

+
llm-token-visualizer --logprobs-file answer.json \
+  --fail-on-flag --format json -o report.json
+
+
+ + + + + + + + diff --git a/src/lib.rs b/src/lib.rs index a776794..402fcc3 100644 --- a/src/lib.rs +++ b/src/lib.rs @@ -3,6 +3,7 @@ pub mod detect; #[cfg(feature = "live")] pub mod live; pub mod renderer; +pub mod report; pub mod utils; pub use data::{ diff --git a/src/main.rs b/src/main.rs index a391707..1b41ef2 100644 --- a/src/main.rs +++ b/src/main.rs @@ -3,13 +3,22 @@ use clap::Parser; use std::io::Read; use std::path::PathBuf; -use llm_token_visualizer::detect::{self, Report}; +use llm_token_visualizer::detect; +use llm_token_visualizer::report; use llm_token_visualizer::{ HtmlRenderer, MarkdownRenderer, Renderer, TerminalRenderer, TokenAnalysis, VisualizationConfig, }; #[derive(Parser)] #[command(name = "llm-token-visualizer", version)] +#[command(after_help = "Examples: + llm-token-visualizer --logprobs-file answer.json + llm-token-visualizer --logprobs-file answer.json --format html -o report.html + llm-token-visualizer --logprobs-file answer.json --format markdown >> $GITHUB_STEP_SUMMARY + llm-token-visualizer --live \"Who painted The Night Watch?\" --save answer.json + llm-token-visualizer --logprobs-file answer.json --fail-on-flag --format json + +Sample responses with logprobs are in examples/logprobs/ (samples/ in release archives).")] #[command( about = "Flag low-confidence spans in LLM output from token logprobs, and visualize per-token confidence" )] @@ -58,7 +67,7 @@ struct Args { #[arg(long)] confidence_file: Option, - /// Output format: terminal, html, markdown, or json (json: detect mode only) + /// Output format: terminal, html (a self-contained report page), markdown, or json (json: detect mode only) #[arg(short, long, default_value = "terminal")] format: String, @@ -158,16 +167,51 @@ fn run_detect(args: &Args) -> Result { let tokens = detect::parse_logprobs(&json)?; let report = detect::detect(&tokens, args.threshold); + let source = match (&args.live, &args.logprobs_file) { + (Some(_), _) => "live".to_string(), + (None, Some(p)) if p.as_os_str() == "-" => "stdin".to_string(), + (None, Some(p)) => p + .file_name() + .map(|n| n.to_string_lossy().into_owned()) + .unwrap_or_else(|| p.display().to_string()), + (None, None) => unreachable!("checked by caller"), + }; + let meta = report::Meta::from_response(source, &json); - if args.format == "json" { - write_output(args, &serde_json::to_string_pretty(&report)?)?; - } else { - let analysis = detect::to_token_analysis(&tokens, &report); - render(args, &report.text, &analysis)?; - if args.format == "terminal" { - println!("{}", verdict(&report)); + let output = match args.format.as_str() { + "json" => serde_json::to_string_pretty(&report)?, + "html" => report::html(&tokens, &report, &meta), + "markdown" => report::markdown(&tokens, &report, &meta), + "terminal" => { + let mut out = report::terminal(&tokens, &report, &meta); + if args.verbose { + out.push_str( + " + token p alternatives +", + ); + for (i, t) in tokens.iter().enumerate() { + let alts: Vec = t + .top_logprobs + .iter() + .filter(|a| a.token != t.token) + .map(|a| format!("{:?} {:.2}", a.token, a.logprob.exp())) + .collect(); + out.push_str(&format!( + " {:>3} {:<18} {:.3} {} +", + i, + format!("{:?}", t.token), + t.prob(), + alts.join(", ") + )); + } + } + out } - } + f => anyhow::bail!("unsupported format {f:?}; use terminal, html, markdown or json"), + }; + write_output(args, &output)?; Ok(if args.fail_on_flag && report.flagged() { 2 @@ -176,25 +220,6 @@ fn run_detect(args: &Args) -> Result { }) } -fn verdict(r: &Report) -> String { - if r.spans.is_empty() { - format!( - "No low-confidence spans (threshold {:.2}, {} tokens, mean p={:.2}).\n\ - This does not prove the answer is correct: models can be confidently wrong.", - r.threshold, r.token_count, r.mean_prob - ) - } else { - format!( - "{} low-confidence span(s) at threshold {:.2} ({} tokens, mean p={:.2}).\n\ - Check these claims before trusting the answer.", - r.spans.len(), - r.threshold, - r.token_count, - r.mean_prob - ) - } -} - #[cfg(feature = "live")] fn fetch_live(prompt: &str, args: &Args) -> Result { llm_token_visualizer::live::fetch(prompt, &args.model, args.max_tokens) diff --git a/src/renderer.rs b/src/renderer.rs index 5b21b8c..d6021b4 100644 --- a/src/renderer.rs +++ b/src/renderer.rs @@ -70,21 +70,21 @@ impl Renderer for TerminalRenderer { let mut output = String::new(); // Header - output.push_str("🔍 LLM Token Analysis\n"); + output.push_str("LLM Token Analysis\n"); output.push_str("━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━\n"); if config.verbose { let (min_conf, max_conf, avg_conf) = analysis.get_confidence_stats(); output.push_str(&format!( - "📊 Confidence Stats: Min: {:.2}, Max: {:.2}, Avg: {:.2}\n", + "Confidence Stats: Min: {:.2}, Max: {:.2}, Avg: {:.2}\n", min_conf, max_conf, avg_conf )); - output.push_str(&format!("🏷️ Flags: {}\n", analysis.flags.len())); + output.push_str(&format!("Flags: {}\n", analysis.flags.len())); output.push_str("━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━\n"); } // Legend - output.push_str("🎨 Color Legend:\n"); + output.push_str("Color Legend:\n"); output.push_str(&format!( " {} Very Low Confidence (0.0-0.3)\n", "██".red().bold() @@ -102,7 +102,7 @@ impl Renderer for TerminalRenderer { output.push_str("━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━\n"); // Render tokens - output.push_str("📝 Token Visualization:\n\n"); + output.push_str("Token Visualization:\n\n"); for (i, token) in analysis.tokens.iter().enumerate() { let formatted_token = self.format_token(token, i, analysis); output.push_str(&format!("{}", formatted_token)); @@ -111,7 +111,7 @@ impl Renderer for TerminalRenderer { // Show token details if verbose if config.verbose && config.show_confidence_scores { - output.push_str("📋 Token Details:\n"); + output.push_str("Token Details:\n"); output.push_str("━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━\n"); for (i, token) in analysis.tokens.iter().enumerate() { let flags = analysis.get_flags_for_token(i); @@ -134,7 +134,7 @@ impl Renderer for TerminalRenderer { // Show flags if enabled if config.show_flags && !analysis.flags.is_empty() { - output.push_str("🏷️ Flags:\n"); + output.push_str("Flags:\n"); output.push_str("━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━\n"); for flag in &analysis.flags { let token_text: String = analysis.tokens[flag.start..flag.end] @@ -221,7 +221,7 @@ impl Renderer for HtmlRenderer {
-

🔍 LLM Token Analysis

+

LLM Token Analysis

"#); @@ -230,7 +230,7 @@ impl Renderer for HtmlRenderer { html.push_str(&format!( r#"
-

📊 Statistics

+

Statistics

Confidence Range: {:.3} - {:.3} (Average: {:.3})

Total Tokens: {}

Total Flags: {}

@@ -246,7 +246,7 @@ impl Renderer for HtmlRenderer { html.push_str(r#"
-

🎨 Confidence Legend

+

Confidence Legend

Very Low (0.0-0.3)
Low (0.3-0.5)
Medium (0.5-0.7)
@@ -255,7 +255,7 @@ impl Renderer for HtmlRenderer {
-

📝 Token Visualization

+

Token Visualization

"#); for (i, token) in analysis.tokens.iter().enumerate() { @@ -280,7 +280,7 @@ impl Renderer for HtmlRenderer { html.push_str( r#"
-

🏷️ Flags

+

Flags

"#, ); @@ -343,11 +343,11 @@ impl Renderer for MarkdownRenderer { let mut md = String::new(); - md.push_str("# 🔍 LLM Token Analysis\n\n"); + md.push_str("# LLM Token Analysis\n\n"); if config.verbose { let (min_conf, max_conf, avg_conf) = analysis.get_confidence_stats(); - md.push_str("## 📊 Statistics\n\n"); + md.push_str("## Statistics\n\n"); md.push_str(&format!( "- **Confidence Range**: {:.3} - {:.3} (Average: {:.3})\n", min_conf, max_conf, avg_conf @@ -356,14 +356,14 @@ impl Renderer for MarkdownRenderer { md.push_str(&format!("- **Total Flags**: {}\n\n", analysis.flags.len())); } - md.push_str("## 🎨 Confidence Legend\n\n"); + md.push_str("## Confidence Legend\n\n"); md.push_str("- 🔴 Very Low (0.0-0.3)\n"); md.push_str("- 🟡 Low (0.3-0.5)\n"); md.push_str("- ⚪ Medium (0.5-0.7)\n"); md.push_str("- 🔵 High (0.7-0.9)\n"); md.push_str("- 🟢 Very High (0.9-1.0)\n\n"); - md.push_str("## 📝 Token Visualization\n\n"); + md.push_str("## Token Visualization\n\n"); for (i, token) in analysis.tokens.iter().enumerate() { let confidence_level = ConfidenceLevel::from(token.confidence); @@ -388,7 +388,7 @@ impl Renderer for MarkdownRenderer { md.push_str("\n\n"); if config.show_flags && !analysis.flags.is_empty() { - md.push_str("## 🏷️ Flags\n\n"); + md.push_str("## Flags\n\n"); for flag in &analysis.flags { let token_text: String = analysis.tokens[flag.start..flag.end] @@ -409,7 +409,7 @@ impl Renderer for MarkdownRenderer { } if config.verbose && config.show_confidence_scores { - md.push_str("\n## 📋 Detailed Token Information\n\n"); + md.push_str("\n## Detailed Token Information\n\n"); md.push_str("| Index | Token | Confidence | Flags |\n"); md.push_str("|-------|-------|------------|-------|\n"); diff --git a/src/report.rs b/src/report.rs new file mode 100644 index 0000000..c9fd09d --- /dev/null +++ b/src/report.rs @@ -0,0 +1,548 @@ +//! Reports for detect mode: a confidence heatmap of the answer, the flagged +//! spans, and the alternatives the model weighed at each weak token. +//! +//! Three formats share one color scale ([`heat`]): a colored terminal report, +//! a self-contained HTML page (no scripts, no external assets), and Markdown +//! that reads well in a pull request or issue comment. + +use colored::Colorize; +use std::fmt::Write as _; + +use crate::detect::{LogprobToken, Report, Span}; + +/// Where the answer came from, shown in report headers. +#[derive(Debug, Clone, Default)] +pub struct Meta { + /// e.g. the input file name, or "live". + pub source: String, + /// Model name from the response, if it had one. + pub model: Option, +} + +impl Meta { + /// Read the `model` field from a raw Chat Completions response. + pub fn from_response(source: impl Into, json: &str) -> Self { + let model = serde_json::from_str::(json) + .ok() + .and_then(|v| v.get("model")?.as_str().map(str::to_string)); + Meta { + source: source.into(), + model, + } + } +} + +/// Map a probability to an RGB color: warm ink for confident tokens, through +/// amber, to vermilion for the least likely ones. +pub fn heat(p: f64) -> (u8, u8, u8) { + const STOPS: [(f64, (f64, f64, f64)); 4] = [ + (0.25, (232.0, 72.0, 48.0)), + (0.55, (240.0, 140.0, 52.0)), + (0.80, (236.0, 192.0, 92.0)), + (0.97, (214.0, 208.0, 196.0)), + ]; + let p = p.clamp(0.0, 1.0); + if p <= STOPS[0].0 { + let c = STOPS[0].1; + return (c.0 as u8, c.1 as u8, c.2 as u8); + } + for w in STOPS.windows(2) { + let ((p0, a), (p1, b)) = (w[0], w[1]); + if p <= p1 { + let t = (p - p0) / (p1 - p0); + let mix = |x: f64, y: f64| (x + (y - x) * t).round() as u8; + return (mix(a.0, b.0), mix(a.1, b.1), mix(a.2, b.2)); + } + } + let c = STOPS[3].1; + (c.0 as u8, c.1 as u8, c.2 as u8) +} + +/// For each token, the 1-based number of the span it belongs to (0 = none). +fn span_index(tokens: &[LogprobToken], report: &Report) -> Vec { + let mut idx = vec![0; tokens.len()]; + for (n, s) in report.spans.iter().enumerate() { + for slot in idx.iter_mut().take(s.end).skip(s.start) { + *slot = n + 1; + } + } + idx +} + +fn summary(report: &Report) -> String { + match report.spans.len() { + 0 => "No low-confidence spans. That does not prove the answer is correct: \ + models can be confidently wrong." + .to_string(), + 1 => "1 low-confidence span. Check it before trusting the answer.".to_string(), + n => format!("{n} low-confidence spans. Check these claims before trusting the answer."), + } +} + +/// The candidates at a span's weakest token, with the chosen token included +/// and marked, most likely first. +fn candidates(span: &Span) -> Vec<(String, f64, bool)> { + let mut out: Vec<(String, f64, bool)> = span + .alternatives + .iter() + .map(|c| (c.token.clone(), c.prob, c.token == span.weakest_token)) + .collect(); + if !out.iter().any(|c| c.2) { + out.push((span.weakest_token.clone(), span.min_prob, true)); + } + out.sort_by(|a, b| b.1.total_cmp(&a.1)); + out +} + +fn token_range(s: &Span) -> String { + if s.end - s.start == 1 { + format!("token {}", s.start) + } else { + format!("tokens {}-{}", s.start, s.end - 1) + } +} + +/// Show a token so leading spaces and empty strings stay visible. +fn show(token: &str) -> String { + format!("{token:?}") +} + +// ---------------------------------------------------------------- terminal + +/// Confident tokens keep the terminal's own color so the answer stays +/// readable on light and dark themes; only doubt gets a heat color. +fn piece_for(text: &str, p: f64) -> colored::ColoredString { + if p >= 0.9 { + text.normal() + } else { + let (r, g, b) = heat(p); + text.truecolor(r, g, b) + } +} + +/// Colored terminal report. Honors `NO_COLOR` through the `colored` crate. +pub fn terminal(tokens: &[LogprobToken], report: &Report, meta: &Meta) -> String { + let mut out = String::new(); + let spans = span_index(tokens, report); + + let mut head = vec![meta.source.clone()]; + if let Some(m) = &meta.model { + head.push(m.clone()); + } + head.push(format!("{} tokens", report.token_count)); + head.push(format!("mean p {:.2}", report.mean_prob)); + head.push(format!("threshold {:.2}", report.threshold)); + let _ = writeln!(out, "\n {}\n", head.join(" ").dimmed()); + + // The answer as a heatmap, wrapped at about 72 columns. + let mut line = String::from(" "); + let mut col = 0usize; + for (i, t) in tokens.iter().enumerate() { + let len = t.token.chars().count(); + let text = if col + len > 72 && t.token.starts_with(' ') { + out.push_str(&line); + out.push('\n'); + line = String::from(" "); + col = 0; + t.token.trim_start().to_string() + } else { + t.token.clone() + }; + col += text.chars().count(); + // Keep a flagged word's leading space out of its underline. + let body = text.trim_start(); + line.push_str(&text[..text.len() - body.len()]); + let mut piece = piece_for(body, t.prob()); + if spans[i] > 0 { + piece = piece.bold().underline(); + } + line.push_str(&piece.to_string()); + } + out.push_str(&line); + out.push_str("\n\n"); + + // One label width for every span so the bars line up. + let width = report + .spans + .iter() + .flat_map(candidates) + .map(|c| show(&c.0).chars().count()) + .max() + .unwrap_or(0); + for (n, s) in report.spans.iter().enumerate() { + let (r, g, b) = heat(s.min_prob); + let _ = writeln!( + out, + " {} {} {}", + format!("{}", n + 1).truecolor(r, g, b).bold(), + s.text.trim().bold(), + format!( + "{}, weakest {} at p {:.2}", + token_range(s), + show(&s.weakest_token), + s.min_prob + ) + .dimmed() + ); + for (tok, p, chosen) in candidates(s) { + let filled = (p * 24.0).round() as usize; + let (r, g, b) = heat(p); + let bar = format!( + "{}{}", + "\u{2588}".repeat(filled).truecolor(r, g, b), + "\u{2591}".repeat(24 - filled.min(24)).dimmed() + ); + let label = format!("{: String { + let mut o = String::with_capacity(s.len()); + for c in s.chars() { + if "\\`*_[]<>|#~".contains(c) { + o.push('\\'); + } + o.push(c); + } + o +} + +/// Markdown report: flagged spans in bold with numbered markers, then a table. +pub fn markdown(tokens: &[LogprobToken], report: &Report, meta: &Meta) -> String { + let mut md = String::new(); + let spans = span_index(tokens, report); + let _ = writeln!(md, "### Token confidence report\n"); + let mut facts = vec![format!("`{}`", meta.source)]; + if let Some(m) = &meta.model { + facts.push(format!("`{m}`")); + } + facts.push(format!("{} tokens", report.token_count)); + facts.push(format!("mean p {:.2}", report.mean_prob)); + facts.push(format!("threshold {:.2}", report.threshold)); + let _ = writeln!(md, "{}\n", facts.join(" · ")); + + let mut body = String::new(); + let mut i = 0; + while i < tokens.len() { + if spans[i] == 0 { + body.push_str(&md_escape(&tokens[i].token)); + i += 1; + continue; + } + let n = spans[i]; + let s = &report.spans[n - 1]; + let text: String = tokens[s.start..s.end] + .iter() + .map(|t| t.token.as_str()) + .collect(); + let lead = &text[..text.len() - text.trim_start().len()]; + let _ = write!( + body, + "{lead}**{}**{n}", + md_escape(text.trim_start()) + ); + i = s.end; + } + let _ = writeln!(md, "> {}\n", body.trim()); + + if report.flagged() { + md.push_str("| # | Span | Weakest token | p | Model also considered |\n"); + md.push_str("|---|---|---|---|---|\n"); + for (n, s) in report.spans.iter().enumerate() { + let others: Vec = candidates(s) + .into_iter() + .filter(|c| !c.2) + .map(|c| format!("`{}` {:.2}", c.0.replace('`', "'"), c.1)) + .collect(); + let _ = writeln!( + md, + "| {} | {} | `{}` | {:.2} | {} |", + n + 1, + md_escape(s.text.trim()), + s.weakest_token.replace('`', "'"), + s.min_prob, + if others.is_empty() { + "n/a".to_string() + } else { + others.join(", ") + } + ); + } + md.push('\n'); + } + let _ = writeln!(md, "{}", summary(report)); + md +} + +// -------------------------------------------------------------------- html + +fn esc(s: &str) -> String { + let mut o = String::with_capacity(s.len()); + for c in s.chars() { + match c { + '&' => o.push_str("&"), + '<' => o.push_str("<"), + '>' => o.push_str(">"), + '"' => o.push_str("""), + '\'' => o.push_str("'"), + _ => o.push(c), + } + } + o +} + +const CSS: &str = r#" +:root{--bg:#f4efe4;--card:#fbf8f1;--ink:#1d1b17;--mute:#6f6a5f;--rule:#ddd5c4;--flag:#d9432b;--alpha:.62} +@media (prefers-color-scheme:dark){:root{--bg:#141311;--card:#1b1a17;--ink:#ebe5d8;--mute:#9a9385;--rule:#302d27;--flag:#f0654a;--alpha:.5}} +*{box-sizing:border-box} +body{margin:0;background:var(--bg);color:var(--ink);font:16px/1.5 ui-sans-serif,system-ui,-apple-system,"Segoe UI",sans-serif} +main{max-width:860px;margin:0 auto;padding:48px 20px 64px} +.k{font:12px/1.4 ui-monospace,"SF Mono","Cascadia Mono",Consolas,monospace;letter-spacing:.08em;text-transform:uppercase;color:var(--mute)} +.meta{text-transform:none;letter-spacing:.02em;display:flex;flex-wrap:wrap;gap:6px 18px;margin:10px 0 28px} +.meta b{color:var(--ink);font-weight:600} +.answer{font:clamp(22px,3.4vw,30px)/1.75 "Iowan Old Style","Palatino Linotype",Palatino,Georgia,serif;margin:0 0 20px;padding:28px 30px;background:var(--card);border:1px solid var(--rule);border-radius:14px} +.t{position:relative;border-radius:4px;background:rgba(var(--h),calc(var(--a)*var(--alpha)));padding:.06em 0} +.t:hover,.t:focus{outline:1.5px solid rgb(var(--h));outline-offset:1px} +.t:hover::after,.t:focus::after{content:attr(data-tip);position:absolute;left:0;top:calc(100% + 6px);z-index:2;white-space:pre;background:var(--ink);color:var(--bg);font:12px/1.5 ui-monospace,Consolas,monospace;padding:6px 9px;border-radius:6px;pointer-events:none} +.f{text-decoration:underline wavy var(--flag);text-decoration-thickness:1.5px;text-underline-offset:.28em;text-decoration-skip-ink:none} +sup{font:600 11px ui-monospace,Consolas,monospace;color:var(--flag);margin-left:1px} +.trace{justify-content:center;display:flex;align-items:flex-end;gap:2px;height:44px;margin:0 0 36px;padding:0 4px} +.trace i{flex:1;max-width:26px;min-width:2px;border-radius:2px 2px 0 0;background:rgb(var(--h))} +.spans{display:grid;gap:14px} +.span{background:var(--card);border:1px solid var(--rule);border-radius:12px;padding:16px 18px} +.span h3{margin:0 0 10px;font-size:17px;display:flex;gap:10px;align-items:baseline;flex-wrap:wrap} +.span h3 .k{text-transform:none;letter-spacing:0} +.span h3 .n{font:600 13px ui-monospace,Consolas,monospace;color:var(--flag)} +.row{display:grid;grid-template-columns:minmax(90px,max-content) 1fr 44px;gap:12px;align-items:center;font:14px ui-monospace,Consolas,monospace;margin:4px 0} +.bar{height:10px;border-radius:5px;background:var(--rule);overflow:hidden} +.bar i{display:block;height:100%;background:rgb(var(--h))} +.row.c{font-weight:700} +.p{text-align:right;color:var(--mute)} +.verdict{margin:30px 0 0;padding-top:18px;border-top:1px solid var(--rule)} +.scale{display:flex;align-items:center;gap:10px;margin-top:14px} +.scale span.g{height:8px;width:180px;border-radius:4px;background:linear-gradient(90deg,rgb(232,72,48),rgb(240,140,52) 40%,rgb(236,192,92) 76%,rgb(214,208,196))} +footer{margin-top:40px} +footer a{color:inherit} +"#; + +/// Self-contained HTML report. Hover or focus any token for its probability +/// and the alternatives the model weighed. +pub fn html(tokens: &[LogprobToken], report: &Report, meta: &Meta) -> String { + let spans = span_index(tokens, report); + let mut h = String::new(); + let _ = write!( + h, + "\n\ + \ + \ + Token confidence: {}
", + esc(&meta.source), + CSS + ); + let _ = write!(h, "
Token confidence report
"); + let _ = write!( + h, + "
{}", + esc(&meta.source) + ); + if let Some(m) = &meta.model { + let _ = write!(h, "{}", esc(m)); + } + let _ = write!( + h, + "{} tokensmean p {:.2}threshold {:.2}\ + {} flagged
", + report.token_count, + report.mean_prob, + report.threshold, + report.spans.len() + ); + + // The answer, one element per token. + h.push_str("

"); + for (i, t) in tokens.iter().enumerate() { + let n = spans[i]; + let starts = n > 0 && (i == 0 || spans[i - 1] != n); + let ends = n > 0 && (i + 1 == tokens.len() || spans[i + 1] != n); + let body = t.token.trim_start(); + let lead = &t.token[..t.token.len() - body.len()]; + h.push_str(&esc(lead)); + if starts { + let _ = write!(h, ""); + } + let p = t.prob(); + let (r, g, b) = heat(p); + let mut tip = format!("p {p:.2} {}", show(&t.token)); + for a in t.top_logprobs.iter().filter(|a| a.token != t.token) { + let _ = write!(tip, "\n {:.2} {}", a.logprob.exp(), show(&a.token)); + } + let _ = write!( + h, + "{}", + ((0.95 - p) / 0.95).max(0.0).powf(0.7), + esc(&tip), + esc(body) + ); + if ends { + let _ = write!(h, "{n}"); + } + } + h.push_str("

"); + + // A strip with one bar per token, height = probability. + h.push_str("
"); + for t in tokens { + let p = t.prob(); + let (r, g, b) = heat(p); + let _ = write!( + h, + "", + (p * 100.0).max(4.0), + esc(&show(&t.token)), + p + ); + } + h.push_str("
"); + + if report.flagged() { + h.push_str("
Flagged spans
"); + for (n, s) in report.spans.iter().enumerate() { + let _ = write!( + h, + "

{}{}weakest {} at p {:.2}

", + n + 1, + esc(s.text.trim()), + esc(&show(&s.weakest_token)), + s.min_prob + ); + for (tok, p, chosen) in candidates(s) { + let (r, g, b) = heat(p); + let _ = write!( + h, + "
{}{:.2}
", + if chosen { " c" } else { "" }, + esc(&show(&tok)), + p * 100.0, + p + ); + } + h.push_str("
"); + } + h.push_str("
"); + } + + let _ = writeln!( + h, + "
{}
p 0p 1
\ + \ +
\n", + esc(&summary(report)), + env!("CARGO_PKG_VERSION") + ); + h +} + +#[cfg(test)] +mod tests { + use super::*; + use crate::detect::{detect, parse_logprobs}; + + fn sample() -> (Vec, Report, Meta) { + let json = include_str!("../examples/logprobs/cuyp.json"); + let tokens = parse_logprobs(json).unwrap(); + let report = detect(&tokens, 0.6); + (tokens, report, Meta::from_response("cuyp.json", json)) + } + + #[test] + fn meta_reads_model_name() { + let (_, _, m) = sample(); + assert_eq!(m.model.as_deref(), Some("meta-llama/llama-3.1-8b-instruct")); + } + + #[test] + fn heat_is_monotone_from_red_to_ink() { + assert_eq!(heat(0.0), (232, 72, 48)); + assert_eq!(heat(1.0), (214, 208, 196)); + // green channel rises as confidence rises + let gs: Vec = [0.2, 0.4, 0.6, 0.8, 0.95] + .iter() + .map(|&p| heat(p).1) + .collect(); + assert!(gs.windows(2).all(|w| w[0] <= w[1]), "{gs:?}"); + } + + #[test] + fn html_marks_spans_and_alternatives() { + let (t, r, m) = sample(); + let h = html(&t, &r, &m); + assert!(h.starts_with("")); + assert!(h.contains("id=\"s2\"")); + assert!(h.contains(""üsseldorf"")); + assert!(h.contains("2 low-confidence spans")); + assert_eq!(h.matches("class=\"t\"").count(), t.len()); + assert!(!h.contains("&","logprob":-2.0}]"#).unwrap(); + let r = detect(&tokens, 0.5); + let h = html(&tokens, &r, &Meta::default()); + assert!(h.contains("<b>&")); + assert!(!h.contains("&")); + } + + #[test] + fn markdown_numbers_spans_and_lists_alternatives() { + let (t, r, m) = sample(); + let md = markdown(&t, &r, &m); + assert!(md.contains("**Dordrecht**2"), "{md}"); + assert!(md.contains("`üsseldorf` 0.39"), "{md}"); + assert!(md.contains("| 2 | Dordrecht | `ord` | 0.57 |"), "{md}"); + } + + #[test] + fn terminal_without_color_is_plain_and_complete() { + colored::control::set_override(false); + let (t, r, m) = sample(); + let out = terminal(&t, &r, &m); + assert!(out.contains("Aelbert Cuyp died in 1691 in Dordrecht, Netherlands.")); + assert!(out.contains("\"üsseldorf\"")); + assert!(out.contains("chosen")); + assert!(out.contains("2 low-confidence spans")); + colored::control::unset_override(); + } + + #[test] + fn confident_answer_still_warns() { + let tokens = parse_logprobs(r#"[{"token":"Yes","logprob":-0.01}]"#).unwrap(); + let r = detect(&tokens, 0.5); + assert!(markdown(&tokens, &r, &Meta::default()).contains("confidently wrong")); + } +}