-
+
- Activity
- ${escapeHtml(client.activity.join(' · '))}
- Runtime
- ${escapeHtml(client.reliability.join(' · '))}
- Control
- ${escapeHtml(client.policy.join(' · '))}
- Coverage
- ${escapeHtml(client.coverage.join(' · '))}
diff --git a/README.md b/README.md index 6d4de648c..4c9ea7ce5 100644 --- a/README.md +++ b/README.md @@ -3,7 +3,7 @@
- Your coding agent wastes most of its context window. This stops it — by default, on install, across 15 clients. + Spend less context, keep the conclusions, and audit every claim across 16 coding clients.
@@ -15,17 +15,17 @@
-
-
+
+
-
+
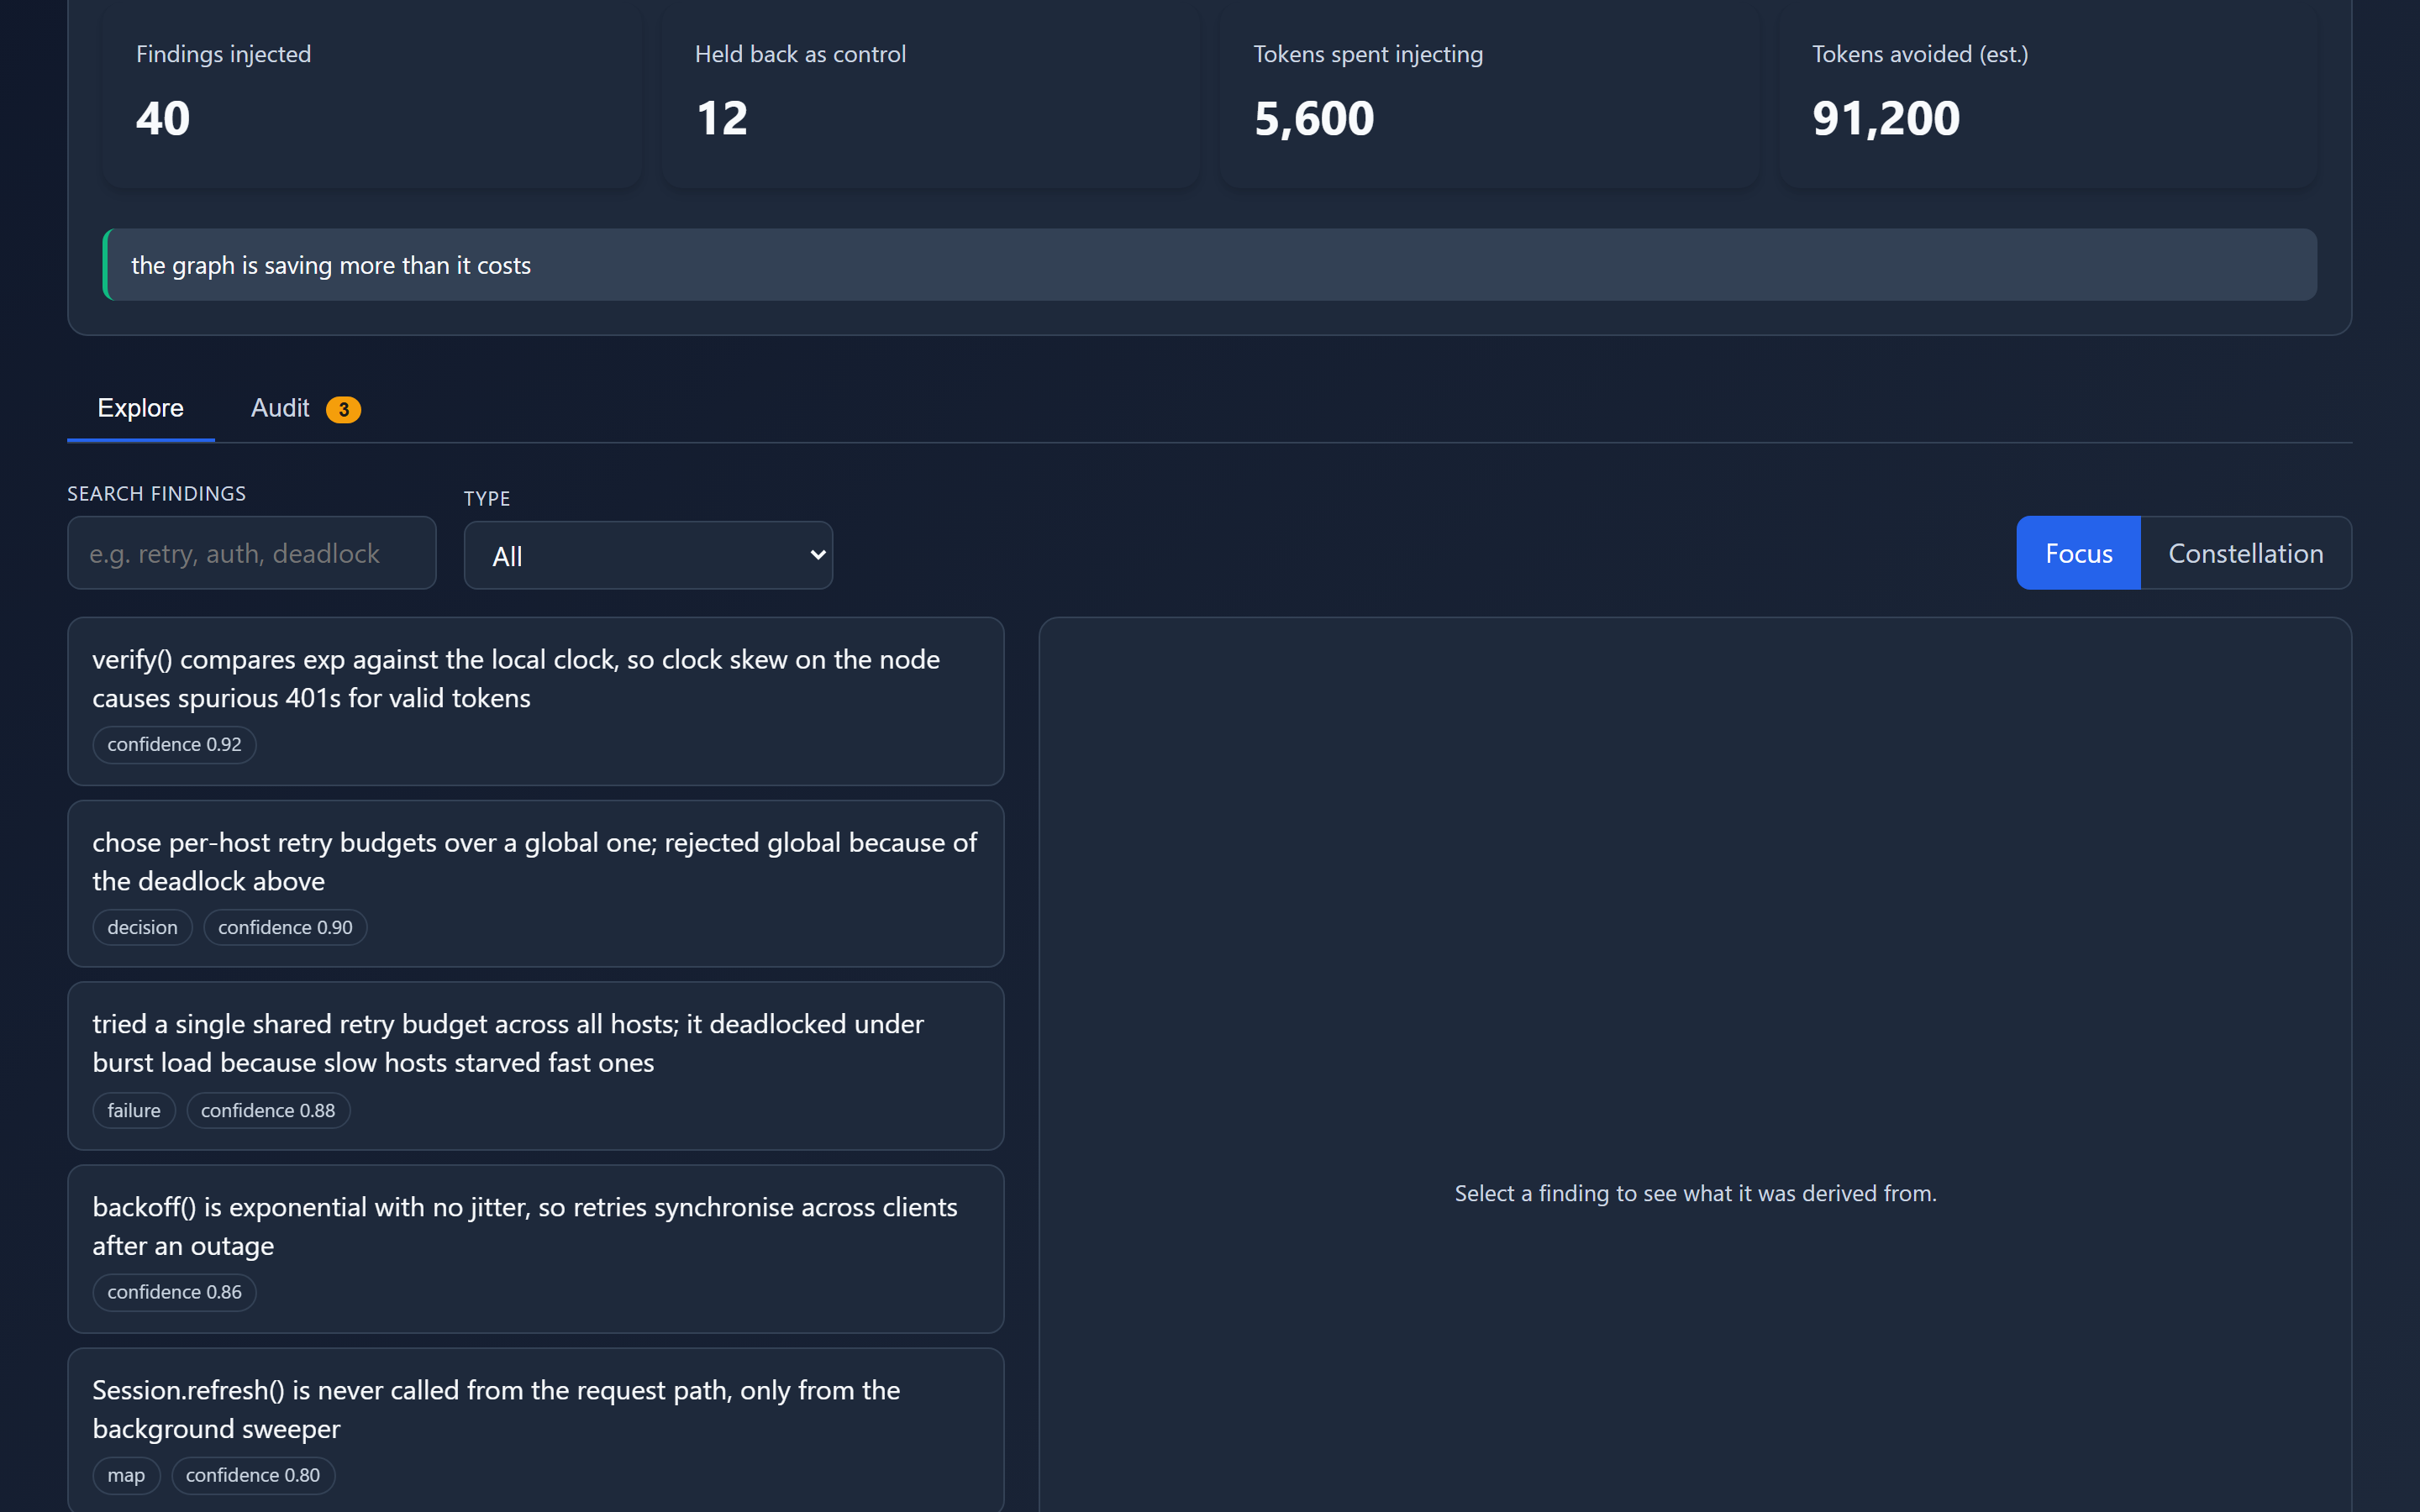
Everything your agent worked out, kept — and a savings figure measured against a withheld control arm, not estimated.
+One local ledger for optimizer tools, live-graph substitutions, every agent, and the graph's own cost.
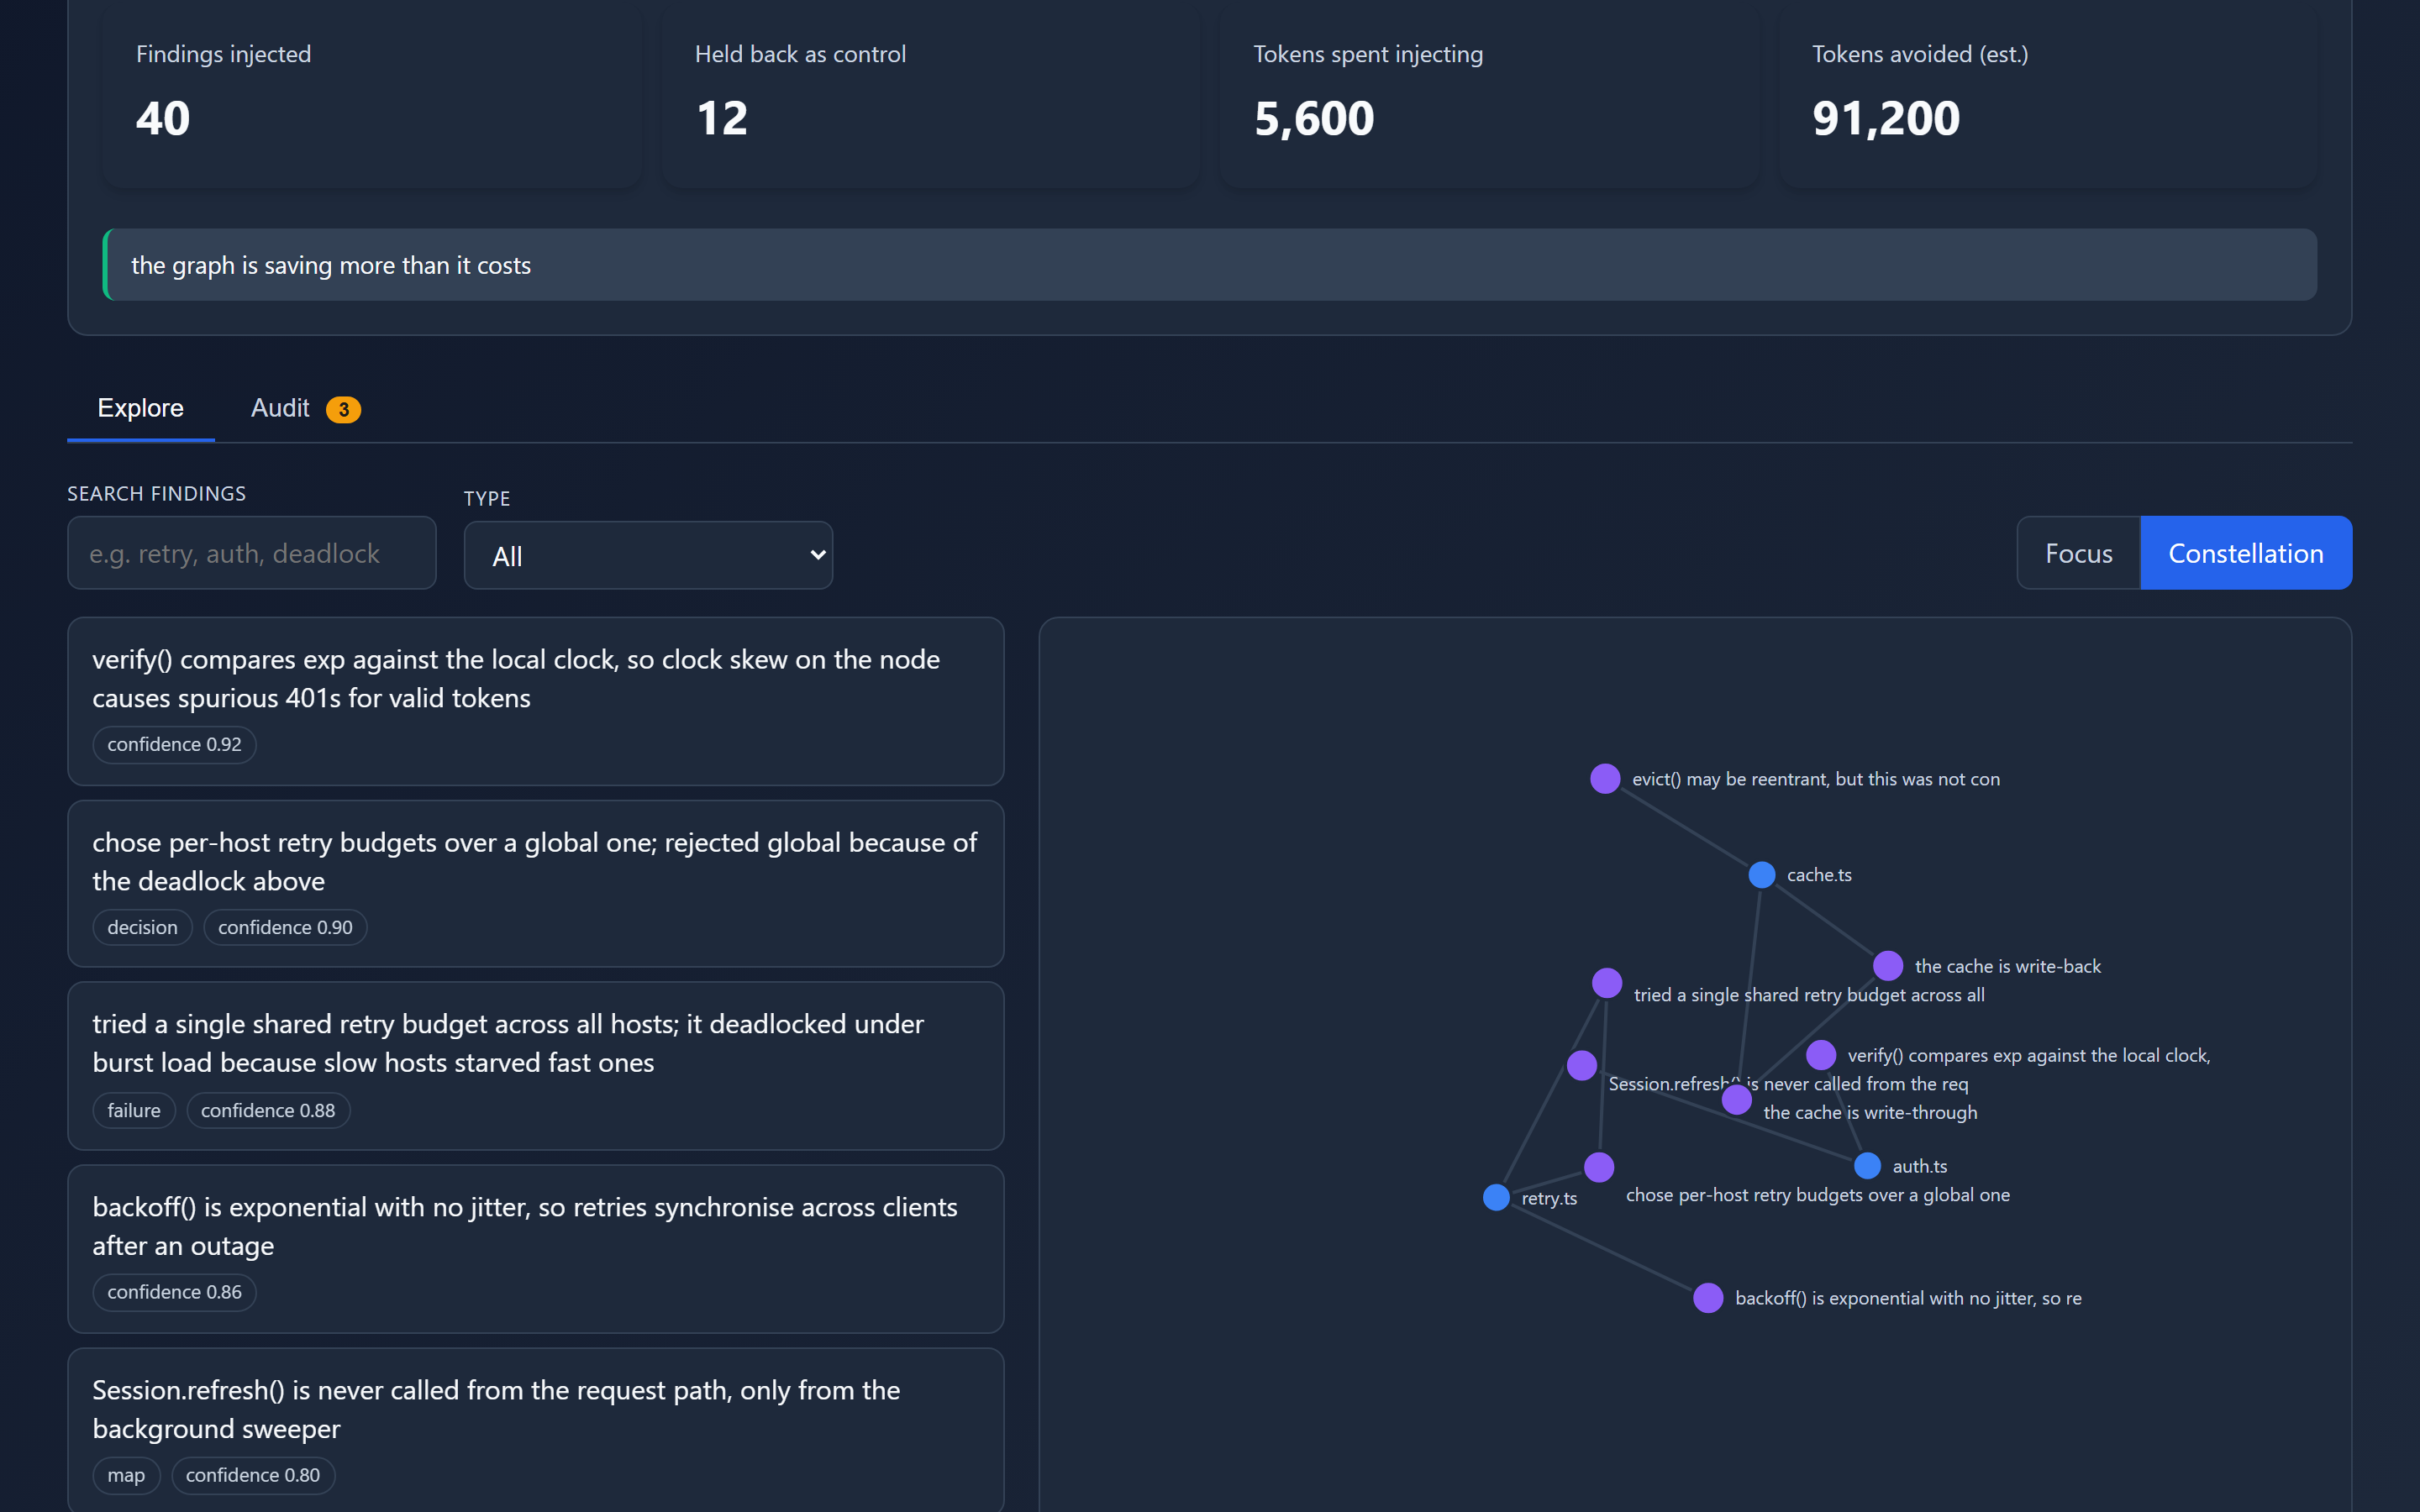
--- @@ -36,7 +36,7 @@ that have not changed, dumping a whole file to see three lines, running unbounded searches, and re-deriving conclusions it reached last session and then forgot. -Token Optimizer attacks that on three fronts. +Token Optimizer attacks that on four fronts. **1. It makes the expensive call impossible.** Install the plugin and a built-in `Read` of a 200 KB file is **denied**, with the refusal naming the cached, @@ -51,13 +51,43 @@ feeds them back the moment the agent touches the relevant file. A finding costs ~150 tokens to carry. Re-deriving it costs 5k–50k. **3. It measures itself, in public, and tells you when it is losing.** A -randomized control arm for savings. A forecast that keeps its own accuracy -record. Cache economics read from your client's own transcript rather than -modelled. Every number here is measured or absent — never estimated and -presented as fact. +materialized before/actual-return measurement for MCP progressive disclosure, +with later expansions debited from the same net. Modeled graph substitutions +and the randomized control arm for downstream graph effects remain separate. +Every number is measured, visibly collecting, excluded, or absent. + +**4. It attributes the traffic.** Returned context, optional cost equivalents, +and net transport avoided are grouped by operation and MCP handshake identity. Codex, Claude Code, +Gemini, and any other connected client get separate rows. Old records without +identity remain explicitly unattributed instead of being assigned to whichever +agent happens to be open now. No account, no telemetry, no hosted service. MIT, so it is usable at work. +### What the dashboard proves on a real machine + +The screenshots in this README come from the shipped server reading persisted +local data, not a design mockup. In the capture above it reports: + +- **43,491 net verified MCP transport tokens avoided** in the current live + proof: 54,037 gross reduction minus a deliberate 10,546-token expansion; +- **486,074,740 historical/tool-reported tokens quarantined**, dominated by + repository scan volume that never entered model context; +- a live Codex / Claude Code / Gemini stdio smoke against AiDotNet, with each + client attributed independently; +- **2,648 graph nodes, 6,527 edges, and 58 findings** across 11 local projects; +- **more than 1,000 hook runs with zero failures and zero timeouts** across six + active CLI clients in the selected rolling 24-hour window; +- **6,332 tokens of modeled graph-substitution potential**, excluded from the + verified headline while the causal graph-reuse study remains `Collecting`. + +The dashboard now reads native CLI usage receipts and prices uncached input, +cache reads, cache writes, and output with the exact captured provider, model, +route, request-time tier, and versioned official source. Ambiguous model ids stay +**Not priced** instead of receiving a blended guess. API/list-price equivalents +are kept separate from provider-reported charges and are never labeled as a +subscription invoice. See the [token accounting contract](./docs/TOKEN_ACCOUNTING.md). + ## Quick start **Claude Code** — install the plugin, not the bare MCP server. The plugin is @@ -69,7 +99,7 @@ what enforces; adding the server alone just gives the model tools it can ignore. /reload-plugins ``` -That is the entire installation. [All fifteen clients →](#installation) +That is the entire installation. [All sixteen clients →](#installation) Then, whenever you want to know what to do next: @@ -77,8 +107,9 @@ Then, whenever you want to know what to do next: token_audit ``` -One ranked queue: what is costing the most, priced per session and per month, -each line naming how to fix it. Not a dashboard, not six reports — a queue. +One ranked queue: what is costing the most per session, with an optional monthly +cost equivalent only after you configure your own effective rate. Each line +names how to fix it. Not a dashboard, not six reports — a queue. --- @@ -135,48 +166,93 @@ output never enters context at all. Not compressed. Absent. ## The dashboard ```bash +npm install +npm run build npm run dashboard # http://localhost:3100 ```
-
+
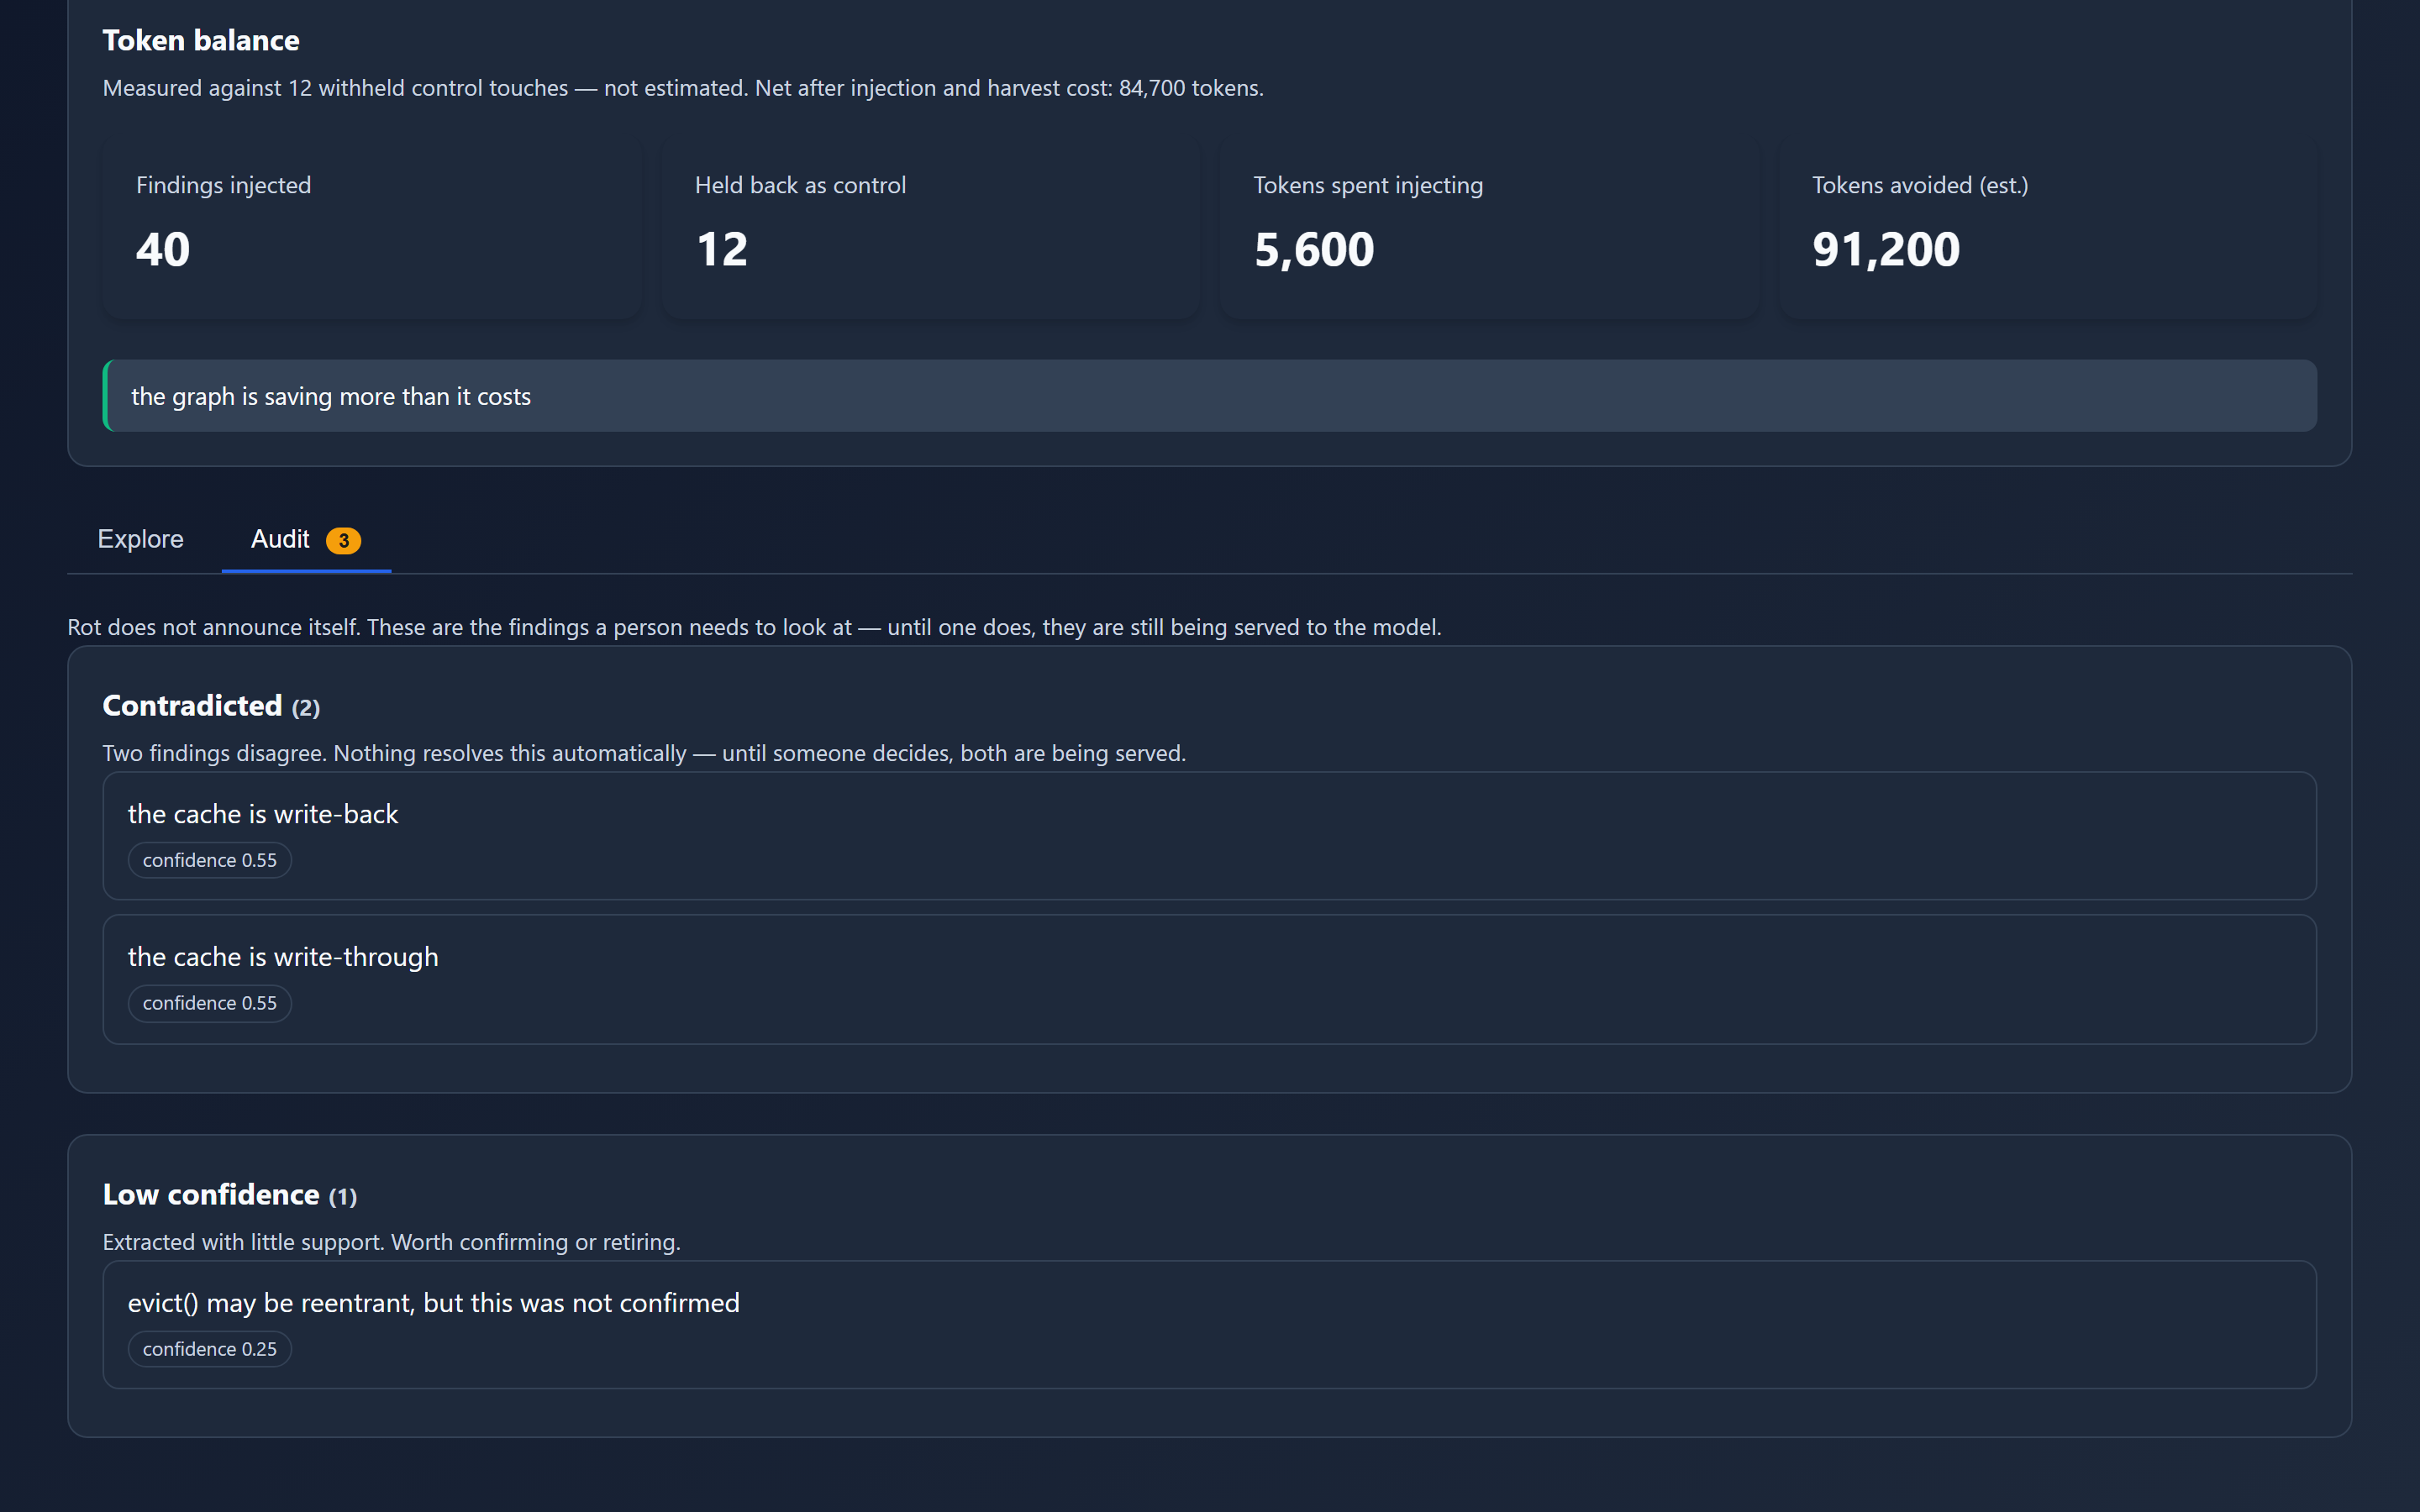
| - -**Token balance** -Earned, spent and net — with the control-arm method stated up front rather than -buried. When the experiment cannot yet support a headline figure, it says so. - -**Knowledge graph browser** -Focus view for one node and its neighbourhood; constellation view for the whole -project. Click a finding to see what it was derived from, what superseded it, -and what contradicts it. +The overview answers the questions a token optimizer should answer first: + +1. **How much MCP context did it avoid?** The headline is gross materialized + payload reduction minus every later linked expansion. Graph estimates are + intentionally separate. +2. **How much context still reached the agents?** Every successful current MCP + result records its actual returned text, even when no valid before-state + exists. That row is context-accounted but savings-unmeasured. +3. **Which agent and action spent it?** The client ledger and action table show + operations, returned context, optional cost equivalent, and net tokens + avoided. Lifecycle-only clients say `Not measured`; no zero is invented. +4. **Did remembering cost more than it saved?** Delivery and semantic-harvest + tokens are charged to the graph. A causal benefit is added only after the + treated/holdout evidence gate passes. + +### Walkthrough: get useful data, not an empty dashboard + +1. Install the MCP server and the native adapter for your CLI. The MCP handshake + provides per-client accounting; native lifecycle hooks provide automatic + routing, capture, health, and delivery where the client protocol permits it. +2. Use `smart_read`, `smart_grep`, `smart_glob`, `smart_edit`, or any other MCP + operation normally. Every successful result records returned context; tools + with a comparable materialized before-state also record a gross reduction; + later `expand` calls debit that reduction. +3. Let the active model record durable conclusions with `wiki_write`. Before a + new agent re-derives work, call `wiki_read` for the project or the files it is + about to touch. Native clients can also deliver matching knowledge + automatically. +4. Open `http://localhost:3100`. Use **Overview** for combined accounting and + **What it knows** for capture health, graph exploration, audits, and causal + evidence. +5. To register existing local repositories without reading their source, run + `npm run projects:discover -- /absolute/path/to/repos`. This makes coverage + gaps explicit; it does not fabricate findings. + +For maintainers, this live smoke exercises the shipped stdio transport and +creates separately attributed rows without seeding the analytics database: - |
+```bash
+npm run dashboard:attribution-smoke -- /absolute/path/to/project /absolute/path/to/large-file
+npm run dashboard:verify-live -- http://localhost:3100
+```
-**Audit tab**
-Contradictions, stale findings, and anything the graph believes that the code no
-longer supports — each with the diff that invalidated it.
+
+
+ |
-
+
The audit tab: two findings that contradict each other, surfaced automatically.
+Drag to orbit, scroll to zoom, click a node for provenance, or switch to the +bounded one-hop focus view. The default **All known projects** scope pools local +graphs through opaque project IDs; filesystem paths never reach the browser. + +**Audit tab.** Contradictions, stale findings, and low-confidence claims remain +reviewable instead of silently becoming model truth. + +**Evidence console.** Client/model/task cohorts, matched effects with 95% +intervals, live outcome joins, harm feedback, and capability tiers for all 16 +clients. Release and superiority claims fail closed while evidence is missing. + +**One-click Markdown export.** The accumulated graph becomes documentation you +can inspect, edit, and commit. Server-side by design: the browser asks for a neighbourhood, a search result or a page. A mature graph holds thousands of nodes, and shipping it wholesale would @@ -198,9 +274,9 @@ whose capture has not started. The balance cards are backed by persisted events: **Memory deliveries** counts graph context actually supplied to an agent, **Kept back for comparison** counts randomized control touches, and **Cost of remembering** combines delivered-context tokens with measured semantic-write -payload cost. **Reading avoided** stays “Not enough comparisons” until at least -20 deliveries and 5 holdouts exist; the dashboard does not manufacture a -savings estimate from missing data. +payload cost. **Reading avoided** stays `Collecting` or `Not measured` until at +least 20 treated file touches and 5 holdouts exist with a downstream join; the +dashboard does not manufacture a savings estimate from missing data. See [the causal evidence protocol](docs/EVIDENCE_PROTOCOL.md), the [cross-client capability contract](docs/CLIENT_SUPPORT.md), and the @@ -276,10 +352,13 @@ never happens. ### Prompt-cache economics, measured from your own transcript -A cache write costs 1.25× a plain token and a read costs 0.1×, so a prefix that -keeps invalidating can cost more than every saving elsewhere. This reads the -real numbers your client already recorded — then does the part a hit rate -cannot: +Provider caches are billable and provider-specific; a cache hit is not a free +input token. For example, Anthropic publishes separate cache-read and +cache-write multipliers, while OpenAI and Gemini expose their own cached-input +usage and pricing rules. Token Optimizer reads native cache fields when the +client supplies them and keeps reads, writes, uncached input, and output +separate. It never applies one provider's cache multiplier to another client. +The attribution view then does the part a hit rate cannot: ``` ! CLAUDE.md:2 has an embedded timestamp, invalidating everything after it @@ -308,7 +387,7 @@ has actually saved: ``` generated/schema.d.ts: read in 9/9 sessions, never the source of a finding - 3,400 tokens/session (~$3.06/month); apply: waste_audit action="apply" + 3,400 tokens/session; cost equivalent not priced; apply: waste_audit action="apply" ``` Anything that touches **your** files is proposed as a diff and never applied. @@ -374,15 +453,21 @@ npm run uninstall-hooks -- --apply # carry it out --- -## It proves its own savings against a control arm +## It separates direct savings from causal graph evidence Every tool in this space reports "tokens saved" computed from its own assumptions. That number cannot be wrong, because nothing checks it. -This runs a **randomized holdout**: injection is silently withheld on a slice of -file touches, stratified by file so the comparison is within-file, and the -saving is the measured difference between the arms. It refuses to print a -headline figure until the experiment can support one, and it will tell you +For optimizer results, this records the materialized before-state and the text +actually returned to the client, then subtracts any linked expansion responses. +Native graph-substitution counterfactuals stay labeled as modeled and outside +the main headline. + +The graph's broader claim—whether delivered knowledge prevented later +re-reading—is causal, so it runs a **randomized holdout**. Delivery is silently +withheld on a slice of file touches, stratified by file, and the effect is the +difference in downstream reads between arms. That effect is not added to the +combined net until the experiment can support it, and the page will tell you plainly: > the graph is NOT yet paying for itself @@ -394,14 +479,21 @@ silent false negative, and dollars get quoted to other people. ## It runs everywhere, and says which tier -**Enforcing** — a pre-execution veto exists: Claude Code, Codex, OpenCode. +The tier is a protocol guarantee, not a preference: -**Directive** — MCP plus an always-applied rules file: Cursor, Windsurf, Cline, -Roo, Kilo, Zed, Amp, Continue, Crush, Droid, Copilot, Gemini, Qwen. +- **Lifecycle continuation:** Claude Code, Codex, GitHub Copilot CLI, Gemini CLI, + Qwen Code, and Cursor. Native routing/capture/delivery plus one active-model + completion reflection. +- **Native observation:** Cline, OpenCode, Kilo, and Windsurf. Native + routing/capture/delivery; the active model performs semantic writes. +- **MCP + rules:** Roo Code, Zed, Amp, Continue, Crush, and Droid. MCP-visible + activity and explicit graph tools, with no claim over hidden built-in calls. -Gemini and Qwen sit in the second tier **despite having hooks**, because their -only tool hook fires _after_ the read is paid for. Claiming enforcement there -would be a lie you would discover on your first large file. +The exact surfaces still differ. For example, a protocol that can replace a +large read before it reaches the model provides a stronger token guarantee than +one that can only observe it. The generated registry, adapters, dashboard, and +certification report all read the same capability source so those claims cannot +drift independently. Every config shape is confirmed against that client's published documentation, with the source URL recorded in its README. @@ -414,7 +506,7 @@ npm run verify:all | Suite | Checks | What it proves | | ---------------- | ------ | ----------------------------------------------------------------------------------------------------------------------- | -| `test` | 416 | Enforcement, staleness, injection, consolidation, disclosure, cache, routing, trust — driving the real hooks over stdin | +| `test` | 2,340 | Enforcement, staleness, injection, consolidation, disclosure, cache, routing, trust — driving the real hooks over stdin | | `verify:clients` | 129 | Every client config matches its documented schema | | `verify:harvest` | 26 | Request shape, response parsing, and that **no secret from a tool result crosses the wire** | | `verify:ui` | 22 | Real headless Chromium: layout, label collisions, legibility | @@ -427,19 +519,19 @@ a plan and deleted nothing. ## Honest comparison -| | Token Optimizer | Typical alternatives | -| ---------------------------- | -------------------------------------------------- | ---------------------------------------------------- | -| **License** | MIT — commercial use fine | Often noncommercial-only; check before using at work | -| Default behaviour | Refuses the wasteful call | Suggests a better tool | -| Re-read of an unchanged file | Returns a diff | Returns the file again | -| Savings figure | Measured against a withheld control | Computed from the tool's own assumptions | -| Cross-session memory | Findings, decisions, dead ends | Usually none | -| Compaction | Consolidation, ranked by cost-to-rederive | Checkpoint and replay | -| Cache economics | Measured from the transcript, attributed to a line | Rarely addressed | -| Model routing | Measured from episode outcomes | Guessed from task size | -| Cross-project | Fixes transfer by content hash | Per-project only | -| Clients | 15 | 3–6 typical | -| Telemetry | None | Varies | +| | Token Optimizer | Typical alternatives | +| ---------------------------- | -------------------------------------------------------------------- | ---------------------------------------------------- | +| **License** | MIT — commercial use fine | Often noncommercial-only; check before using at work | +| Default behaviour | Refuses the wasteful call | Suggests a better tool | +| Re-read of an unchanged file | Returns a diff | Returns the file again | +| Savings figure | Direct before/return ledger; causal graph effect separately held out | Computed from the tool's own assumptions | +| Cross-session memory | Findings, decisions, dead ends | Usually none | +| Compaction | Consolidation, ranked by cost-to-rederive | Checkpoint and replay | +| Cache economics | Measured from the transcript, attributed to a line | Rarely addressed | +| Model routing | Measured from episode outcomes | Guessed from task size | +| Cross-project | Fixes transfer by content hash | Per-project only | +| Clients | 16 | 3–6 typical | +| Telemetry | None | Varies | --- @@ -450,7 +542,7 @@ but they differ in what they let a hook _do_, and that difference is the whole product. A client with a pre-execution veto can have the wasteful call refused; one without can only be told. Both are listed honestly below. -Ready-made configuration for all fifteen lives in +Ready-made configuration for all sixteen lives in [`integrations/`](./integrations), generated from one source and validated by `npm run verify:clients`. Full matrix: [`docs/CLIENT_SUPPORT.md`](./docs/CLIENT_SUPPORT.md). @@ -803,12 +895,6 @@ Any stdio-capable MCP client can launch Token Optimizer with: Additional ready-made integration files are available for [Claude Desktop](./examples/claude_desktop_config.json), [Codex](./integrations/codex/config.toml), [Gemini CLI](./integrations/gemini/), [OpenCode](./integrations/opencode/), and [GitHub Copilot](./integrations/copilot/mcp-config.json). -## See it in action - - - -_Real `get_optimization_report` output from an MCP smoke run over this repository's tool reference, server source, and dependency lockfile. Savings vary with content and workflow._ - ## Use it You normally use Token Optimizer by asking your agent in plain language: @@ -875,11 +961,12 @@ For clients that expose direct MCP tool calls, the core inputs are small JSON ob } ``` -`get_optimization_report` aggregates recorded operations into: +`get_optimization_report` applies the same versioned measurement contract as +the dashboard and aggregates qualifying operations into: -- original, optimized, and saved token totals; -- overall reduction percentage; -- operations tracked; +- gross preview reduction, linked expansion debits, and net transport avoided; +- observed returned context and the net reduction percentage; +- verified operations tracked, with legacy and tool-reported claims excluded; - breakdowns by action/tool, hook phase, and MCP server; - optional date-range and session filters. @@ -1330,18 +1417,14 @@ When global hooks are installed, token-optimizer-mcp runs automatically on **eve └─────────────────────────────────────────────────────────────┘ ``` -### Production Performance - -Based on 38,000+ operations in real-world usage: - -| Tool Category | Avg Token Reduction | Cache Hit Rate | -| ----------------- | ------------------- | -------------- | -| File Operations | 60-90% | >80% | -| API Responses | 83-95% | >75% | -| Database Queries | 83-90% | >70% | -| Build/Test Output | 70-85% | >65% | +### Performance evidence -**Per-Session Savings**: 300K-700K tokens (worth $0.90-$2.10 at $3/M tokens) +Reduction targets in tool descriptions are design goals, not production +measurements. They never enter the verified ledger. Use the dashboard or +`get_optimization_report` for request-level measurements, and +`npm run dashboard:audit-savings` to inspect both qualifying and excluded rows. +No universal dollar value is claimed: configure an effective rate only when it +reflects your own provider, model, cache, route, plan, tier, and credits. ### Usage Examples diff --git a/docs/COMPETITIVE_GAPS.md b/docs/COMPETITIVE_GAPS.md index 200a297b8..835f9f0fe 100644 --- a/docs/COMPETITIVE_GAPS.md +++ b/docs/COMPETITIVE_GAPS.md @@ -5,8 +5,8 @@ from its README and documentation site rather than from memory. ## A correction I owe first -On issue #201 I wrote that they "audit waste in your *setup*" while we "change -what the *operations* cost", and that those compose. **That was wrong.** +On issue #201 I wrote that they "audit waste in your _setup_" while we "change +what the _operations_ cost", and that those compose. **That was wrong.** They ship active compression that changes operation cost directly: @@ -24,14 +24,14 @@ model choosing to cooperate. Ours requires the model to reissue the call against ## Where we are genuinely ahead -| | Us | Them | -|---|---|---| -| **License** | MIT | PolyForm **Noncommercial** — unusable at work | -| Clients | 15 | 6 | -| Savings measurement | **withheld control arm** | counterfactual baseline + metered receipts, no control | -| Operational tooling | ~100 MCP tools (git, build, db, API, search) | none — it is not an MCP server | -| Cross-session knowledge | anchored graph with computed staleness | decision extraction, capped at 10/session | -| Enforcement | refusal with the replacement named | nudges and transparent rewriting | +| | Us | Them | +| ----------------------- | -------------------------------------------- | ------------------------------------------------------ | +| **License** | MIT | PolyForm **Noncommercial** — unusable at work | +| Clients | 15 | 6 | +| Savings measurement | **withheld control arm** | counterfactual baseline + metered receipts, no control | +| Operational tooling | ~100 MCP tools (git, build, db, API, search) | none — it is not an MCP server | +| Cross-session knowledge | anchored graph with computed staleness | decision extraction, capped at 10/session | +| Enforcement | refusal with the replacement named | nudges and transparent rewriting | The licence is still the single most decisive line for anyone using this at work, and the control-arm measurement is a claim they cannot make. The MCP tool @@ -61,7 +61,7 @@ decision density, agent efficiency), letter grades S–F, a status-line integrat with colour transitions, and degradation tracking framed against MRCR falling 93% → 76% as context grows. -We have nothing here. It is also the most *visible* feature they have — it is on +We have nothing here. It is also the most _visible_ feature they have — it is on screen constantly, which is worth more than its accuracy. ### 3. Progressive disclosure of tool results @@ -108,10 +108,14 @@ per-message cost breakdown. We have `get_optimization_report`. The gap is less about capability than about there being an obvious thing to run that tells you what to do next. -### 8. Dollars, not tokens +### 8. Billing evidence, not a universal token price -They price against four tiers and report `$/month` with receipts. We report -tokens. Same data, and the unit people actually feel. +Provider/model tables alone cannot reconstruct a CLI user's bill because cache +reads and writes, routing, long-context tiers, subscriptions, included credits, +and enterprise agreements change marginal cost. Token Optimizer now reports +verified transport tokens and fails closed on dollars unless the user supplies +an effective blended rate. Provider-native billing exports remain the source of +truth for actual spend. ### 9. Skills and configuration health diff --git a/docs/HOOKS-INSTALLATION.md b/docs/HOOKS-INSTALLATION.md index 04c6e86c1..f25525ae8 100644 --- a/docs/HOOKS-INSTALLATION.md +++ b/docs/HOOKS-INSTALLATION.md @@ -32,11 +32,13 @@ The global hooks system provides **7-phase token optimization** that runs automa ## Prerequisites ### All Platforms + - **Claude Code** CLI installed globally - **Node.js** 18+ and npm - **token-optimizer-mcp** package (will be installed by installer) ### Platform-Specific + - **Windows**: PowerShell 5.1+ - **macOS**: Bash 4.0+, Homebrew recommended - **Linux**: Bash 4.0+ @@ -434,18 +436,21 @@ chmod +x ~/.claude-global/hooks/helpers/*.sh ### 1. Check Hooks Are Firing **Windows:** + ```powershell # View dispatcher log Get-Content "$env:USERPROFILE\.claude-global\hooks\logs\dispatcher.log" -Tail 20 ``` **macOS / Linux:** + ```bash # View dispatcher log tail -20 ~/.claude-global/hooks/logs/dispatcher.log ``` You should see entries like: + ``` [2025-10-26 10:00:00] [PreToolUse] DISPATCHER INVOKED [2025-10-26 10:00:01] [PreToolUse] Tool: Read @@ -455,18 +460,21 @@ You should see entries like: ### 2. Check MCP Tools Are Being Called **Windows:** + ```powershell # View MCP invocation log Get-Content "$env:USERPROFILE\.claude-global\hooks\logs\mcp-invocation.log" -Tail 20 ``` **macOS / Linux:** + ```bash # View MCP invocation log tail -20 ~/.claude-global/hooks/logs/mcp-invocation.log ``` You should see: + ``` [2025-10-26 10:00:00] [DEBUG] Invoking MCP: token-optimizer -> smart_read [2025-10-26 10:00:01] [DEBUG] Request: {"jsonrpc":"2.0",...} @@ -475,18 +483,21 @@ You should see: ### 3. Check Token Optimization **Windows:** + ```powershell # View token optimizer log Get-Content "$env:USERPROFILE\.claude-global\hooks\logs\token-optimizer.log" -Tail 10 ``` **macOS / Linux:** + ```bash # View token optimizer log tail -10 ~/.claude-global/hooks/logs/token-optimizer.log ``` You should see savings like: + ``` [2025-10-26 10:00:00] [SUGGEST] Read File (~5000 tokens) → Token Optimizer (~1850 tokens) | Savings: 3150 tokens (63%) ``` @@ -494,6 +505,7 @@ You should see savings like: ### 4. Check Operations Tracking **Windows:** + ```powershell # View most recent operations CSV Get-ChildItem "$env:USERPROFILE\.claude-global\hooks\data\operations-*.csv" | @@ -503,6 +515,7 @@ Get-ChildItem "$env:USERPROFILE\.claude-global\hooks\data\operations-*.csv" | ``` **macOS / Linux:** + ```bash # View most recent operations CSV ls -t ~/.claude-global/hooks/data/operations-*.csv | head -1 | xargs tail -10 @@ -515,6 +528,7 @@ ls -t ~/.claude-global/hooks/data/operations-*.csv | head -1 | xargs tail -10 **Symptom**: No log entries in dispatcher.log **Solutions**: + 1. Check workspace trust is accepted (see Manual Installation Step 5 for your platform) 2. Verify settings.json hook commands have correct paths 3. Restart Claude Code @@ -527,14 +541,17 @@ ls -t ~/.claude-global/hooks/data/operations-*.csv | head -1 | xargs tail -10 **Symptom**: dispatcher.log shows hooks firing but no MCP calls **Solutions**: + 1. Verify token-optimizer MCP server is running: **Windows:** + ```powershell Get-Process | Where-Object { $_.Name -like "*node*" -and $_.CommandLine -like "*token-optimizer*" } ``` **macOS / Linux:** + ```bash ps aux | grep token-optimizer | grep -v grep ``` @@ -552,6 +569,7 @@ ls -t ~/.claude-global/hooks/data/operations-*.csv | head -1 | xargs tail -10 **Symptom**: "File cannot be loaded because running scripts is disabled" **Solution**: + ```powershell Set-ExecutionPolicy RemoteSigned -Scope CurrentUser ``` @@ -561,6 +579,7 @@ Set-ExecutionPolicy RemoteSigned -Scope CurrentUser **Symptom**: "Permission denied" errors when running hooks **Solution**: + ```bash # Make all hook scripts executable chmod +x ~/.claude-global/hooks/dispatcher.sh @@ -576,6 +595,7 @@ ls -la ~/.claude-global/hooks/dispatcher.sh **Symptom**: "Bad substitution" or syntax errors **Solution**: macOS ships with Bash 3.x, but hooks require Bash 4+ + ```bash # Install Bash 4+ via Homebrew brew install bash @@ -731,23 +751,17 @@ C:\Users\YOUR_USERNAME\ └── token-optimizer-mcp # MCP server ``` -## Token Reduction Metrics - -Based on production usage across 38,000+ operations: - -| Tool | Average Tokens Before | Average Tokens After | Reduction % | -|------|----------------------|---------------------|-------------| -| Read | 5,000 | 1,850 | 63% | -| Grep | 2,000 | 740 | 63% | -| Glob | 1,500 | 555 | 63% | -| Edit | 3,500 | 1,295 | 63% | -| **Overall** | **3,000** | **1,110** | **63%** | +## Token reduction measurement -### Session-Level Impact +Static reduction percentages and repository scan sizes are not production +savings evidence. Current releases require a materialized MCP payload before +progressive disclosure and the actual returned payload, then debit every linked +`expand` response. Run `get_optimization_report` for the verified net or +`npm run dashboard:audit-savings` to inspect both qualifying and excluded rows. -- **Operations per session**: ~200-500 -- **Token savings per session**: 300,000-700,000 tokens -- **Cost savings (at $3/M tokens)**: $0.90-$2.10 per session +Dollar values are **Not priced** unless the user configures an effective blended +input-token rate that reflects their provider, model, cache read/write mix, +route, tier, plan, and credits. See [Token accounting](./TOKEN_ACCOUNTING.md). ## Advanced Configuration diff --git a/docs/TOKEN_ACCOUNTING.md b/docs/TOKEN_ACCOUNTING.md new file mode 100644 index 000000000..a2c414233 --- /dev/null +++ b/docs/TOKEN_ACCOUNTING.md @@ -0,0 +1,101 @@ +# Token accounting contract + +Token Optimizer reports four different quantities because combining them would +turn assumptions into evidence: + +1. **Observed returned context** is the local tokenizer count of text that + crossed the MCP response boundary. It is not a provider invoice. +2. **Gross verified transport reduction** is the difference between two + materialized payloads: the tool result before progressive disclosure and + the smaller payload actually returned. +3. **Expansion debit** is every later `expand` response linked to that preview. +4. **Net verified MCP transport avoided** is gross reduction minus expansion + debits. It may be negative. + +Graph substitutions, causal graph-reuse estimates, repository bytes scanned, +tool-reported compression fields, and legacy rows without provenance never +enter the verified MCP headline. + +## Qualification rules + +A reduction qualifies only when its durable row contains all of the following: + +- measurement schema version 2; +- a unique MCP request identity; +- exact UTF-8 byte counts for both materialized payloads and a consistent byte + delta; +- SHA-256 fingerprints for both payloads without storing their contents in the + analytics row; +- locally counted tokens with `saved = before - returned`; +- the content-addressed expansion reference printed in the preview. + +Request retries with the same process/session/RPC identity are stored once. +Historical rows remain available through `npm run dashboard:audit-savings` but +cannot be promoted by a boolean migration or a similarly named tool field. + +## What a token means here + +The MCP boundary does not expose the provider's final billing tokenizer. The +ledger therefore uses a GPT-4-compatible local tokenizer estimate so the same +transport bytes can be compared consistently across Codex, Claude Code, +Gemini, Copilot, and other clients. The dashboard says this explicitly. + +Provider-native study receipts keep uncached input, cache creation, cache read, +and output fields separate when a client supplies them. Those receipt fields +are not substituted into MCP transport measurements because they answer a +different question. + +## Provider usage and cost + +The dashboard reads native local usage receipts from supported CLI transcripts +and keeps their billable dimensions separate: uncached input, cached reads, +5-minute/1-hour/generic cache writes, and output (including thinking tokens when +the provider bills them as output). + +Adapters preserve each provider's semantics. Codex/OpenAI and Gemini prompt +totals include cached input, while Anthropic `input_tokens` excludes cache reads +and cache creation. Claude response fragments are deduplicated by request id, +and repeated Codex usage snapshots are deduplicated by cumulative state. + +A versioned price catalog selects an exact provider, model, route, request +timestamp, and long-context tier. Every priced result carries an official source +link and a catalog verification date. An ambiguous id such as `claude-sonnet`, +an unknown route, or a captured dimension without a published rate remains +**Not priced**; the nearest model is never guessed. + +The dashboard distinguishes two money quantities: + +1. **API/list-price equivalent** applies published rates to native observed + usage. A subscription, enterprise agreement, included credits, processing + tier, or cloud marketplace may make the user's invoice different. +2. **Provider-reported actual charge** appears only when the native receipt + contains a charge. Token Optimizer does not reconstruct an invoice from list + prices. + +For a verified MCP payload reduction, the conservative direct saving is one +immediate uncached-input equivalent for that operation's exact model. The ledger +does not multiply that saving by hypothetical future cache reads or writes. +Paired experiments can separately measure downstream effects from native usage. + +Current provider references are the authoritative source behind catalog rows: + +- [OpenAI model pricing and cached-input rates](https://developers.openai.com/api/docs/models/compare) +- [Anthropic API pricing](https://platform.claude.com/docs/en/about-claude/pricing) +- [Anthropic prompt-cache usage and read/write multipliers](https://platform.claude.com/docs/en/build-with-claude/prompt-caching) +- [Gemini API model pricing](https://ai.google.dev/gemini-api/docs/pricing) +- [GitHub Copilot models and token pricing](https://docs.github.com/en/copilot/reference/copilot-billing/models-and-pricing) + +The separate `analyze_project_tokens` report still accepts an explicit +`costPerMillionTokens` because repository analysis has no model request receipt. +That caller-supplied value remains labeled as a configured equivalent. + +## Auditing an existing ledger + +```bash +npm run dashboard:audit-savings +npm run dashboard:audit-savings -- /absolute/path/to/analytics.db +``` + +The audit is read-only. It reports verified net savings, gross reductions, +expansion debits, observed returned context, excluded historical/tool claims, +per-tool concentration, and the largest excluded rows. diff --git a/docs/TOOLS.md b/docs/TOOLS.md index 2f9d04f81..4e70b5ef9 100644 --- a/docs/TOOLS.md +++ b/docs/TOOLS.md @@ -21,11 +21,13 @@ This document provides comprehensive documentation for all 61 tools available in Compress and cache text to reduce token usage. This is the primary tool for removing content from your context window. **Parameters:** + - `text` (string, required) - Text to optimize - `key` (string, required) - Cache key for storing - `quality` (number, optional) - Compression quality 0-11 (default: 11) **Returns:** + - `success` (boolean) - Operation status - `key` (string) - Cache key - `originalTokens` (number) - Tokens before optimization @@ -37,12 +39,13 @@ Compress and cache text to reduce token usage. This is the primary tool for remo **Token Reduction:** 60-90% average **Example:** + ```typescript optimize_text({ - text: "Large API response or file content...", - key: "api-response-key", - quality: 11 -}) + text: 'Large API response or file content...', + key: 'api-response-key', + quality: 11, +}); ``` --- @@ -52,17 +55,20 @@ optimize_text({ Retrieve previously cached and optimized text. **Parameters:** + - `key` (string, required) - Cache key to retrieve **Returns:** + - `success` (boolean) - Operation status - `key` (string) - Cache key - `text` (string) - Original cached text - `fromCache` (boolean) - Whether data was found in cache **Example:** + ```typescript -get_cached({ key: "api-response-key" }) +get_cached({ key: 'api-response-key' }); ``` --- @@ -72,10 +78,12 @@ get_cached({ key: "api-response-key" }) Compress text using Brotli compression. Returns base64-encoded compressed data. **Parameters:** + - `text` (string, required) - Text to compress - `quality` (number, optional) - Compression quality 0-11 (default: 11) **Returns:** + - `compressed` (string) - Base64-encoded compressed data **Note:** Base64 encoding adds ~33% overhead. Use `optimize_text` for better token reduction. @@ -87,9 +95,11 @@ Compress text using Brotli compression. Returns base64-encoded compressed data. Decompress base64-encoded Brotli-compressed text. **Parameters:** + - `compressed` (string, required) - Base64-encoded compressed text **Returns:** + - `text` (string) - Original decompressed text --- @@ -99,15 +109,18 @@ Decompress base64-encoded Brotli-compressed text. Count tokens in text using tiktoken (GPT-4 tokenizer). **Parameters:** + - `text` (string, required) - Text to count tokens for **Returns:** + - `tokens` (number) - Token count - `characters` (number) - Character count **Example:** + ```typescript -count_tokens({ text: "Your text here" }) +count_tokens({ text: 'Your text here' }); // Result: { tokens: 150, characters: 500 } ``` @@ -118,9 +131,11 @@ count_tokens({ text: "Your text here" }) Analyze text and provide recommendations for optimization including compression benefits and token savings. **Parameters:** + - `text` (string, required) - Text to analyze **Returns:** + - `tokens` - Token analysis - `current` (number) - Current token count - `afterCompression` (number) - Estimated tokens after compression @@ -144,6 +159,7 @@ Get comprehensive cache statistics including hit rate, compression ratio, and to **Parameters:** None **Returns:** + - `totalEntries` (number) - Number of cached entries - `totalSize` (number) - Total cache size in bytes - `hits` (number) - Cache hits @@ -159,9 +175,11 @@ Get comprehensive cache statistics including hit rate, compression ratio, and to Clear all cached data. Use with caution. **Parameters:** + - `confirm` (boolean, required) - Must be true to confirm **Returns:** + - `success` (boolean) - Operation status --- @@ -173,6 +191,7 @@ Clear all cached data. Use with caution. Read files with 80% token reduction through intelligent caching and diff-based updates. **Parameters:** + - `path` (string, required) - Path to file - `diffMode` (boolean, optional) - Return only diff if previously read (default: true) - `maxSize` (number, optional) - Max content size in bytes (default: 100000) @@ -182,12 +201,13 @@ Read files with 80% token reduction through intelligent caching and diff-based u **Token Reduction:** 80% on subsequent reads (diff-only) **Example:** + ```typescript // First read: full content -smart_read({ path: "/src/app.ts" }) +smart_read({ path: '/src/app.ts' }); // Subsequent reads: only changes -smart_read({ path: "/src/app.ts" }) +smart_read({ path: '/src/app.ts' }); ``` --- @@ -197,6 +217,7 @@ smart_read({ path: "/src/app.ts" }) Write files with verification, atomic operations, and change tracking. **Parameters:** + - `path` (string, required) - Path to file - `content` (string, required) - Content to write - `atomic` (boolean, optional) - Use atomic write with temp file (default: true) @@ -213,6 +234,7 @@ Write files with verification, atomic operations, and change tracking. Line-based file editing with diff-only output. **Parameters:** + - `path` (string, required) - Path to file - `operations` (array, required) - Edit operations - `type` - "replace", "insert", or "delete" @@ -234,6 +256,7 @@ Line-based file editing with diff-only output. Search file contents with match-only output and smart filtering. **Parameters:** + - `pattern` (string, required) - Search pattern (regex) - `cwd` (string, optional) - Working directory for search - `files` (array, optional) - File patterns to search (glob patterns) @@ -256,7 +279,8 @@ Search file contents with match-only output and smart filtering. File pattern matching with path-only results and smart filtering. **Parameters:** -- `pattern` (string, required) - Glob pattern (e.g., "src/**/*.ts") + +- `pattern` (string, required) - Glob pattern (e.g., "src/\*_/_.ts") - `cwd` (string, optional) - Working directory - `extensions` (array, optional) - Filter by file extensions - `includeMetadata` (boolean, optional) - Include file metadata (default: false) @@ -273,6 +297,7 @@ File pattern matching with path-only results and smart filtering. Git diffs with diff-only output and smart filtering. **Parameters:** + - `source` (string, optional) - Source commit/branch (default: HEAD) - `target` (string, optional) - Target commit/branch (default: working directory) - `files` (array, optional) - Specific files to diff @@ -292,10 +317,11 @@ Git diffs with diff-only output and smart filtering. Git branch listing with structured JSON output and smart filtering. **Parameters:** + - `cwd` (string, optional) - Working directory - `all` (boolean, optional) - Include local and remote branches (default: false) - `remote` (boolean, optional) - Include remote branches (default: false) -- `pattern` (string, optional) - Filter branches by pattern (e.g., "feature/*") +- `pattern` (string, optional) - Filter branches by pattern (e.g., "feature/\*") - `merged` (boolean, optional) - Only show merged branches (default: false) - `unmerged` (boolean, optional) - Only show unmerged branches (default: false) - `includeCommit` (boolean, optional) - Include last commit info (default: false) @@ -313,6 +339,7 @@ Git branch listing with structured JSON output and smart filtering. Git commit history with smart filtering and structured output. **Parameters:** + - `cwd` (string, optional) - Working directory - `limit` (number, optional) - Maximum commits to return (default: 50) - `offset` (number, optional) - Skip first N commits (default: 0) @@ -335,6 +362,7 @@ Git commit history with smart filtering and structured output. Git merge management with structured status and conflict analysis. **Parameters:** + - `mode` (string, optional) - "status", "merge", "abort", or "continue" (default: "status") - `branch` (string, optional) - Branch to merge from (for merge mode) - `commit` (string, optional) - Specific commit to merge (for merge mode) @@ -358,6 +386,7 @@ Git merge management with structured status and conflict analysis. Git status with status-only output and smart filtering. **Parameters:** + - `cwd` (string, optional) - Repository directory - `summaryOnly` (boolean, optional) - Return counts only (default: false) - `staged` (boolean, optional) - Only staged files @@ -379,6 +408,7 @@ Git status with status-only output and smart filtering. HTTP requests with intelligent caching and retry logic. **Parameters:** + - `method` (string, required) - HTTP method: "GET", "POST", "PUT", "DELETE", "PATCH" - `url` (string, required) - Request URL - `headers` (object, optional) - Request headers @@ -393,19 +423,20 @@ HTTP requests with intelligent caching and retry logic. **Token Reduction:** 83% on cache hits, 95% on cached responses **Example:** + ```typescript // First request: fetch and cache smart_api_fetch({ - method: "GET", - url: "https://api.example.com/data", - ttl: 300 -}) + method: 'GET', + url: 'https://api.example.com/data', + ttl: 300, +}); // Subsequent requests: cached (95% reduction) smart_api_fetch({ - method: "GET", - url: "https://api.example.com/data" -}) + method: 'GET', + url: 'https://api.example.com/data', +}); ``` --- @@ -415,6 +446,7 @@ smart_api_fetch({ API response caching with TTL, ETag, and event-based invalidation strategies. **Parameters:** + - `action` (string, required) - "get", "set", "invalidate", "analyze", or "warm" - `request` (object, optional) - API request data (for get/set) - `url` (string) - Request URL @@ -427,7 +459,7 @@ API response caching with TTL, ETag, and event-based invalidation strategies. - `ttl` (number, optional) - Time-to-live in seconds (default: 3600) - `tags` (array, optional) - Tags for grouping cached entries - `invalidationPattern` (string, optional) - "time", "pattern", "tag", "manual", "event" -- `pattern` (string, optional) - URL pattern for invalidation (e.g., "/api/users/*") +- `pattern` (string, optional) - URL pattern for invalidation (e.g., "/api/users/\*") - `endpoints` (array, optional) - Endpoints to warm (for warm action) - `normalizeQuery` (boolean, optional) - Normalize query parameters (default: true) - `ignoreHeaders` (array, optional) - Headers to exclude from cache key @@ -445,6 +477,7 @@ API response caching with TTL, ETag, and event-based invalidation strategies. Database queries with connection pooling, circuit breaking, and intelligent caching. **Parameters:** + - `query` (string, optional) - SQL query to execute (required for query/explain/analyze/optimize) - `action` (string, optional) - "query", "explain", "analyze", "optimize", "health", "pool", "slow", "batch" (default: "query") - `engine` (string, optional) - "postgresql", "mysql", "sqlite", "mongodb", "redis", "generic" (default: "generic") @@ -473,6 +506,7 @@ Database queries with connection pooling, circuit breaking, and intelligent cach SQL query analysis with optimization suggestions and execution plan analysis. **Parameters:** + - `query` (string, required) - SQL query to analyze - `action` (string, optional) - "analyze", "explain", "validate", "optimize", "history" (default: "analyze") - `database` (string, optional) - "postgresql", "mysql", "sqlite", "sqlserver" @@ -490,6 +524,7 @@ SQL query analysis with optimization suggestions and execution plan analysis. Database schema analysis with intelligent caching and 83% token reduction. **Parameters:** + - `connectionString` (string, required) - Database connection string - PostgreSQL: `postgresql://user:pass@host:port/db` - MySQL: `mysql://user:pass@host/db` @@ -510,6 +545,7 @@ Database schema analysis with intelligent caching and 83% token reduction. GraphQL query optimization with complexity analysis and N+1 detection. **Parameters:** + - `query` (string, required) - GraphQL query to analyze - `operationName` (string, optional) - Operation name - `variables` (object, optional) - Query variables @@ -529,6 +565,7 @@ GraphQL query optimization with complexity analysis and N+1 detection. REST API analysis with endpoint discovery and health scoring. **Parameters:** + - `specContent` (string, optional) - OpenAPI/Swagger spec content (JSON string) - `specUrl` (string, optional) - OpenAPI/Swagger spec URL (not yet supported) - `baseUrl` (string, optional) - Base API URL @@ -550,6 +587,7 @@ REST API analysis with endpoint discovery and health scoring. ORM query optimization with N+1 detection and eager loading suggestions. **Parameters:** + - `ormCode` (string, required) - ORM query code to analyze - `ormType` (string, required) - "prisma", "sequelize", "typeorm", "mongoose", "generic" - `modelDefinitions` (string, optional) - Schema/model definitions for enhanced analysis @@ -569,6 +607,7 @@ ORM query optimization with N+1 detection and eager loading suggestions. Database migration tracking with status monitoring and 83% token reduction. **Parameters:** + - `action` (string, optional) - "list", "status", "pending", "history", "rollback", "generate" (default: "list") - `migrationId` (string, optional) - Migration ID (required for rollback and generate) - `direction` (string, optional) - "up" or "down" for rollback (default: "down") @@ -585,6 +624,7 @@ Database migration tracking with status monitoring and 83% token reduction. WebSocket connection management with message tracking and 83% token reduction. **Parameters:** + - `url` (string, required) - WebSocket URL (ws:// or wss://) - `action` (string, required) - "connect", "disconnect", "send", "history", "analyze" - `message` (any, optional) - Message to send (for send action) @@ -608,6 +648,7 @@ WebSocket connection management with message tracking and 83% token reduction. TypeScript builds with intelligent caching and diff-based change detection. **Parameters:** + - `projectRoot` (string, optional) - Project root directory - `tsconfig` (string, optional) - TypeScript config file path - `force` (boolean, optional) - Force full rebuild, ignore cache (default: false) @@ -624,6 +665,7 @@ TypeScript builds with intelligent caching and diff-based change detection. Test execution with intelligent caching and incremental test selection. **Parameters:** + - `projectRoot` (string, optional) - Project root directory - `pattern` (string, optional) - Pattern to match test files - `onlyChanged` (boolean, optional) - Run only tests that changed (default: false) @@ -641,6 +683,7 @@ Test execution with intelligent caching and incremental test selection. ESLint with intelligent caching, incremental analysis, and auto-fix suggestions. **Parameters:** + - `files` (string/array, required) - Files or pattern to lint - `projectRoot` (string, optional) - Project root directory - `fix` (boolean, optional) - Auto-fix issues (default: false) @@ -658,6 +701,7 @@ ESLint with intelligent caching, incremental analysis, and auto-fix suggestions. TypeScript type checking with intelligent caching and categorized error reporting. **Parameters:** + - `projectRoot` (string, optional) - Project root directory - `tsconfig` (string, optional) - TypeScript config file path - `watch` (boolean, optional) - Watch mode for continuous type checking (default: false) @@ -673,6 +717,7 @@ TypeScript type checking with intelligent caching and categorized error reportin Package installation with dependency analysis, conflict detection, and smart caching. **Parameters:** + - `packages` (array, optional) - Packages to install (if empty, installs all from package.json) - `projectRoot` (string, optional) - Project root directory - `dev` (boolean, optional) - Install as dev dependency (default: false) @@ -689,6 +734,7 @@ Package installation with dependency analysis, conflict detection, and smart cac Docker operations with build/run/stop/logs support, image layer analysis, and optimization suggestions. **Parameters:** + - `operation` (string, required) - "build", "run", "stop", "logs", "ps" - `projectRoot` (string, optional) - Project root directory - `imageName` (string, optional) - Image name for build/run @@ -711,6 +757,7 @@ Docker operations with build/run/stop/logs support, image layer analysis, and op System log aggregation and analysis with multi-source support, pattern filtering, error detection, and insights. **Parameters:** + - `sources` (array, optional) - Log sources to aggregate (file paths or system logs) - `projectRoot` (string, optional) - Project root directory - `level` (string, optional) - Filter by log level: "error", "warn", "info", "debug", "all" (default: "all") @@ -729,6 +776,7 @@ System log aggregation and analysis with multi-source support, pattern filtering Network diagnostics and monitoring with connectivity testing, port scanning, DNS resolution, and anomaly detection. **Parameters:** + - `operation` (string, required) - "ping", "port-scan", "dns", "traceroute", "all" - `hosts` (array, optional) - Hosts to test (for ping/port-scan operations) - `ports` (array, optional) - Ports to scan (for port-scan operation) @@ -747,6 +795,7 @@ Network diagnostics and monitoring with connectivity testing, port scanning, DNS Monitor and analyze system processes with anomaly detection and resource tracking. **Parameters:** + - `projectRoot` (string, optional) - Project root directory - `filter` (string, optional) - Filter processes by name pattern - `cpuThreshold` (number, optional) - Show only high CPU usage processes (> threshold %) @@ -764,6 +813,7 @@ Monitor and analyze system processes with anomaly detection and resource trackin System resource monitoring with CPU, memory, disk usage tracking, anomaly detection, and performance recommendations. **Parameters:** + - `projectRoot` (string, optional) - Project root directory - `includeDisk` (boolean, optional) - Include disk metrics (default: true) - `diskPaths` (array, optional) - Disk paths to monitor (default: root partition) @@ -782,6 +832,7 @@ System resource monitoring with CPU, memory, disk usage tracking, anomaly detect Advanced multi-tier cache (L1/L2/L3) with 6 eviction strategies, stampede prevention, and automatic tier management. **Parameters:** + - `operation` (string, required) - "get", "set", "delete", "clear", "stats", "configure", "promote", "demote", "batch-get", "batch-set", "export", "import" - `key` (string, optional) - Cache key (for get/set/delete/promote/demote operations) - `value` (string, optional) - Value to store (for set operation) @@ -809,8 +860,9 @@ Advanced multi-tier cache (L1/L2/L3) with 6 eviction strategies, stampede preven Intelligent cache pre-warming with 87%+ token reduction, schedule-based warming, pattern analysis, dependency resolution, and progressive warming strategies. **Parameters:** + - `operation` (string, required) - "schedule", "immediate", "pattern-based", "dependency-based", "selective", "status", "cancel", "pause", "resume", "configure" -- `schedule` (string, optional) - Cron expression for scheduled warmup (e.g., '0 * * * *') +- `schedule` (string, optional) - Cron expression for scheduled warmup (e.g., '0 \* \* \* \*') - `keys` (array, optional) - Keys to warm (for immediate/selective operations) - `pattern` (string, optional) - Regex pattern for key matching - `accessHistory` (array, optional) - Access history for pattern-based warmup @@ -845,6 +897,7 @@ Intelligent cache pre-warming with 87%+ token reduction, schedule-based warming, Comprehensive cache analytics with 88%+ token reduction. Real-time dashboards, trend analysis, alerting, heatmaps, bottleneck detection, and cost optimization. **Parameters:** + - `operation` (string, required) - "dashboard", "metrics", "trends", "alerts", "heatmap", "bottlenecks", "cost-analysis", "export-data" - `metricTypes` (array, optional) - Types of metrics: "performance", "usage", "efficiency", "cost", "health" - `timeRange` (object, optional) - Time range for analysis @@ -872,6 +925,7 @@ Comprehensive cache analytics with 88%+ token reduction. Real-time dashboards, t Cache performance benchmarking with 89% token reduction through comprehensive testing and analysis. **Parameters:** + - `operation` (string, required) - "run-benchmark", "compare", "load-test", "latency-test", "throughput-test", "report" - `config` (object, optional) - Cache configuration for single benchmark - `name` (string) - Configuration name @@ -908,6 +962,7 @@ Cache performance benchmarking with 89% token reduction through comprehensive te Advanced compression strategies with 89%+ token reduction. Supports 6 algorithms (gzip, brotli, lz4, zstd, snappy, custom), adaptive selection, dictionary-based compression, and delta compression. **Parameters:** + - `operation` (string, required) - "compress", "decompress", "analyze", "optimize", "benchmark", "configure" - `data` (any, required for compress/decompress/analyze) - Data to process - `algorithm` (string, optional) - "gzip", "brotli", "lz4", "zstd", "snappy", "custom" @@ -933,10 +988,11 @@ Advanced compression strategies with 89%+ token reduction. Supports 6 algorithms Comprehensive cache invalidation with 88%+ token reduction, dependency tracking, pattern matching, scheduled invalidation, and distributed coordination. **Parameters:** + - `operation` (string, required) - "invalidate", "invalidate-pattern", "invalidate-tag", "invalidate-dependency", "schedule-invalidation", "cancel-scheduled", "audit-log", "set-dependency", "remove-dependency", "validate", "configure", "stats", "clear-audit" - `key` (string, optional) - Cache key to invalidate - `keys` (array, optional) - Array of cache keys to invalidate -- `pattern` (string, optional) - Pattern for matching keys (wildcards: * for any chars, ? for single char) +- `pattern` (string, optional) - Pattern for matching keys (wildcards: \* for any chars, ? for single char) - `tag` (string, optional) - Tag to invalidate all associated keys - `tags` (array, optional) - Array of tags to invalidate - `parentKey` (string, optional) - Parent key for dependency relationship @@ -967,6 +1023,7 @@ Comprehensive cache invalidation with 88%+ token reduction, dependency tracking, Advanced cache optimization with 89%+ token reduction. Analyzes performance, benchmarks strategies, provides ML-based recommendations, detects bottlenecks, and performs cost-benefit analysis. **Parameters:** + - `operation` (string, required) - "analyze", "benchmark", "optimize", "recommend", "simulate", "tune", "detect-bottlenecks", "cost-benefit", "configure", "report" - `workloadPattern` (string, optional) - "uniform", "skewed", "temporal", "burst", "predictable", "unknown" - `objective` (string, optional) - "hit-rate", "latency", "memory", "throughput", "balanced" (default: "balanced") @@ -986,6 +1043,7 @@ Advanced cache optimization with 89%+ token reduction. Analyzes performance, ben Advanced cache partitioning and sharding with 87%+ token reduction through consistent hashing, automatic rebalancing, and partition isolation. **Parameters:** + - `operation` (string, required) - "create-partition", "delete-partition", "list-partitions", "migrate", "rebalance", "configure-sharding", "stats" - `partitionId` (string, optional) - Partition identifier (required for create/delete) - `strategy` (string, optional) - "hash", "range", "category", "geographic", "custom" (default: "hash") @@ -1011,6 +1069,7 @@ Advanced cache partitioning and sharding with 87%+ token reduction through consi Distributed cache replication with 88%+ token reduction. Supports primary-replica and multi-primary modes, strong/eventual consistency, automatic conflict resolution, failover, incremental sync, and health monitoring. **Parameters:** + - `operation` (string, required) - "configure", "add-replica", "remove-replica", "promote-replica", "sync", "status", "health-check", "resolve-conflicts", "snapshot", "restore", "rebalance" - `mode` (string, optional) - "primary-replica", "multi-primary", "master-slave", "peer-to-peer" (for configure) - `consistency` (string, optional) - "eventual", "strong", "causal" (for configure) @@ -1040,6 +1099,7 @@ Distributed cache replication with 88%+ token reduction. Supports primary-replic ML-based predictive caching with 91%+ token reduction using ARIMA, exponential smoothing, LSTM, and collaborative filtering. **Parameters:** + - `operation` (string, required) - "train", "predict", "auto-warm", "evaluate", "retrain", "export-model", "import-model", "record-access", "get-patterns" - `modelType` (string, optional) - "arima", "exponential", "lstm", "hybrid" (default: "hybrid") - `trainData` (array, optional) - Training data (for train operation) @@ -1070,6 +1130,7 @@ ML-based predictive caching with 91%+ token reduction using ARIMA, exponential s Comprehensive alerting system with multi-channel notifications (email, Slack, webhook), intelligent routing, and 89% token reduction. **Parameters:** + - `operation` (string, required) - "create-alert", "update-alert", "delete-alert", "list-alerts", "trigger", "get-history", "configure-channels", "silence" - `alertName` (string, optional) - Alert name (required for create, optional for others) - `alertId` (string, optional) - Alert identifier (required for update, delete, trigger, silence) @@ -1117,6 +1178,7 @@ Comprehensive alerting system with multi-channel notifications (email, Slack, we Comprehensive metrics collection and aggregation with multi-source support, time-series compression, and 88% token reduction. **Parameters:** + - `operation` (string, required) - "collect", "query", "aggregate", "export", "list-sources", "configure-source", "get-stats", "purge" - `sourceId` (string, optional) - Source identifier - `sourceName` (string, optional) - Source name @@ -1151,6 +1213,7 @@ Comprehensive metrics collection and aggregation with multi-source support, time External monitoring platform integration with 87% token reduction through data compression and intelligent caching. **Parameters:** + - `operation` (string, required) - "connect", "disconnect", "list-connections", "sync-metrics", "sync-alerts", "push-data", "get-status", "configure-mapping" - `connectionId` (string, optional) - Connection identifier - `connectionName` (string, optional) - Connection name @@ -1169,6 +1232,7 @@ External monitoring platform integration with 87% token reduction through data c Create and manage custom dashboard widgets with 88% token reduction through template caching and configuration compression. **Parameters:** + - `operation` (string, required) - "create", "update", "delete", "list", "render", "create-template", "validate", "get-schema" - `widgetId` (string, optional) - Widget ID (required for update, delete, render) - `widgetName` (string, optional) - Widget name (required for create) @@ -1192,6 +1256,7 @@ Create and manage custom dashboard widgets with 88% token reduction through temp Create and manage interactive data visualizations with 92% token reduction through SVG/Canvas optimization and configuration caching. **Parameters:** + - `operation` (string, required) - "create-chart", "update-chart", "delete-chart", "list-charts", "render", "export", "create-heatmap", "create-timeline", "create-network", "create-sankey", "create-animation" - `chartId` (string, optional) - Chart ID (required for update, delete, render) - `chartType` (string, optional) - "line", "bar", "pie", "scatter", "area", "radar", "bubble" @@ -1218,6 +1283,7 @@ Create and manage interactive data visualizations with 92% token reduction throu Monitor system and application health with 91% token reduction through health state compression and metric aggregation. **Parameters:** + - `operation` (string, required) - "register-endpoint", "unregister-endpoint", "check-health", "list-endpoints", "get-history", "set-threshold", "get-summary", "run-diagnostic" - `endpointId` (string, optional) - Endpoint ID - `endpointName` (string, optional) - Endpoint name @@ -1239,6 +1305,7 @@ Monitor system and application health with 91% token reduction through health st Interactive log analysis dashboard with filtering, searching, pattern detection, and 90% token reduction. **Parameters:** + - `operation` (string, required) - "create", "update", "query", "aggregate", "detect-anomalies", "create-filter", "export", "tail" - `dashboardId` (string, optional) - Dashboard identifier - `dashboardName` (string, optional) - Dashboard name (required for create) @@ -1277,9 +1344,10 @@ Interactive log analysis dashboard with filtering, searching, pattern detection, Intelligent scheduled task management with smart caching (85%+ token reduction). Manage cron jobs (Linux/macOS) and Windows Task Scheduler with validation, history tracking, and next run predictions. **Parameters:** + - `operation` (string, required) - "list", "add", "remove", "enable", "disable", "history", "predict-next", "validate" - `taskName` (string, optional) - Name of the scheduled task -- `schedule` (string, optional) - Cron expression (e.g., "0 2 * * *") or Windows schedule +- `schedule` (string, optional) - Cron expression (e.g., "0 2 \* \* \*") or Windows schedule - `command` (string, optional) - Command to execute - `description` (string, optional) - Task description - `enabled` (boolean, optional) - Whether the task is enabled @@ -1294,25 +1362,26 @@ Intelligent scheduled task management with smart caching (85%+ token reduction). **Token Reduction:** 85% through smart caching **Example:** + ```typescript // List all scheduled tasks -smart_cron({ operation: "list" }) +smart_cron({ operation: 'list' }); // Add a new cron job smart_cron({ - operation: "add", - taskName: "daily-backup", - schedule: "0 2 * * *", // Daily at 2am - command: "/path/to/backup.sh", - description: "Daily backup job" -}) + operation: 'add', + taskName: 'daily-backup', + schedule: '0 2 * * *', // Daily at 2am + command: '/path/to/backup.sh', + description: 'Daily backup job', +}); // Predict next 5 runs smart_cron({ - operation: "predict-next", - taskName: "daily-backup", - predictCount: 5 -}) + operation: 'predict-next', + taskName: 'daily-backup', + predictCount: 5, +}); ``` --- @@ -1322,6 +1391,7 @@ smart_cron({ Intelligent user and permission management with smart caching (86%+ token reduction). Manage users, groups, permissions, ACLs, and perform security audits across Windows, Linux, and macOS. **Parameters:** + - `operation` (string, required) - "list-users", "list-groups", "check-permissions", "audit-security", "get-acl", "get-user-info", "get-group-info", "check-sudo" - `username` (string, optional) - Username for user-specific operations - `groupname` (string, optional) - Group name for group-specific operations @@ -1334,24 +1404,25 @@ Intelligent user and permission management with smart caching (86%+ token reduct **Token Reduction:** 86% through smart caching **Example:** + ```typescript // List all users (excluding system users) -smart_user({ operation: "list-users" }) +smart_user({ operation: 'list-users' }); // Get detailed user information smart_user({ - operation: "get-user-info", - username: "alice" -}) + operation: 'get-user-info', + username: 'alice', +}); // Check file permissions smart_user({ - operation: "check-permissions", - path: "/etc/config.json" -}) + operation: 'check-permissions', + path: '/etc/config.json', +}); // Perform security audit -smart_user({ operation: "audit-security" }) +smart_user({ operation: 'audit-security' }); ``` --- @@ -1361,10 +1432,11 @@ smart_user({ operation: "audit-security" }) Structural code search with 83% token reduction through AST indexing and caching. **Parameters:** + - `pattern` (string, required) - AST pattern to search for (e.g., "function $NAME($ARGS) { $BODY }") - `projectPath` (string, required) - Root directory of the project - `language` (string, optional) - Programming language: "ts", "tsx", "js", "jsx", "py", "go", "rs", "java", "c", "cpp" (auto-detected if not provided) -- `filePattern` (string, optional) - Specific directory or file pattern (e.g., "src/**/*.ts") +- `filePattern` (string, optional) - Specific directory or file pattern (e.g., "src/\*_/_.ts") - `excludePatterns` (array, optional) - Patterns to exclude from search - `contextLines` (number, optional) - Number of context lines around matches (default: 3) - `maxMatches` (number, optional) - Maximum number of matches to return (default: 100) @@ -1373,21 +1445,22 @@ Structural code search with 83% token reduction through AST indexing and caching **Token Reduction:** 83% through AST indexing **Example:** + ```typescript // Find all function definitions smart_ast_grep({ - pattern: "function $NAME($ARGS) { $BODY }", - projectPath: "/path/to/project", - language: "ts", - filePattern: "src/**/*.ts" -}) + pattern: 'function $NAME($ARGS) { $BODY }', + projectPath: '/path/to/project', + language: 'ts', + filePattern: 'src/**/*.ts', +}); // Find all class definitions with specific methods smart_ast_grep({ - pattern: "class $CLASS { $METHODS }", - projectPath: "/path/to/project", - contextLines: 5 -}) + pattern: 'class $CLASS { $METHODS }', + projectPath: '/path/to/project', + contextLines: 5, +}); ``` --- @@ -1397,9 +1470,11 @@ smart_ast_grep({ Get comprehensive session-level token usage statistics. **Parameters:** + - `sessionId` (string, optional) - Optional session ID to query (uses current session if not provided) **Returns:** + - Session-level breakdown of token usage by tool - Operation counts and types - Token savings and reduction percentages @@ -1407,47 +1482,51 @@ Get comprehensive session-level token usage statistics. - Cost estimation **Example:** + ```typescript // Get stats for current session -get_session_stats({}) +get_session_stats({}); // Get stats for specific session -get_session_stats({ sessionId: "session-123" }) +get_session_stats({ sessionId: 'session-123' }); ``` --- ### analyze_project_tokens -Analyze token usage and estimate costs across multiple sessions within a project. Aggregates data from all operations files, provides project-level statistics, identifies top contributing sessions and tools. +Analyze observed token usage across multiple sessions within a project. Aggregates data from all operations files, provides project-level statistics, and identifies top contributing sessions and tools. Cost is not priced unless the caller supplies an effective rate. **Parameters:** + - `projectPath` (string, optional) - Path to project directory (uses hooks data directory if not provided) - `startDate` (string, optional) - Optional start date filter (YYYY-MM-DD format) - `endDate` (string, optional) - Optional end date filter (YYYY-MM-DD format) -- `costPerMillionTokens` (number, optional) - Cost per million tokens in USD (default: 30) +- `costPerMillionTokens` (number, optional) - Explicit effective USD cost per million input tokens. No provider rate is assumed when omitted. **Returns:** + - Project-wide token usage statistics -- Cost estimation +- Cost equivalent when an explicit rate is supplied; otherwise `Not priced` - Top contributing sessions - Top contributing tools - Optimization opportunities **Example:** + ```typescript // Analyze entire project analyze_project_tokens({ - projectPath: "/path/to/project" -}) + projectPath: '/path/to/project', +}); // Analyze specific date range analyze_project_tokens({ - projectPath: "/path/to/project", - startDate: "2024-01-01", - endDate: "2024-01-31", - costPerMillionTokens: 25 -}) + projectPath: '/path/to/project', + startDate: '2024-01-01', + endDate: '2024-01-31', + costPerMillionTokens: 25, +}); ``` --- @@ -1457,30 +1536,33 @@ analyze_project_tokens({ Compress large file operations from the current session to reduce future token usage. Analyzes operations in the current session, identifies large text blocks from file-based tools, compresses them, and stores them in cache. **Parameters:** + - `sessionId` (string, optional) - Optional session ID to optimize (uses current session if not provided) - `min_token_threshold` (number, optional) - Minimum token count for a file operation to be considered for compression (default: 30) **Returns:** + - Number of operations optimized - Total token savings - Compression statistics - List of compressed operations **Example:** + ```typescript // Optimize current session -optimize_session({}) +optimize_session({}); // Optimize with custom threshold optimize_session({ - min_token_threshold: 50 -}) + min_token_threshold: 50, +}); // Optimize specific session optimize_session({ - sessionId: "session-123", - min_token_threshold: 100 -}) + sessionId: 'session-123', + min_token_threshold: 100, +}); ``` --- @@ -1490,36 +1572,43 @@ optimize_session({ ### When to Use Each Tool Category **Core Caching & Optimization** + - Use `optimize_text` for large content that will be referenced multiple times - Use `analyze_optimization` before caching to determine if compression is worthwhile - Use `get_cache_stats` to monitor cache performance **Smart File Operations** + - Use `smart_read` instead of Read for all file operations (automatic 80% reduction) - Use `smart_edit` for line-based changes (90% reduction through diff-only output) - Use `smart_grep` when searching codebase (80% reduction through match-only output) **API & Database** + - Use `smart_api_fetch` for all HTTP requests (95% reduction on cache hits) - Use `smart_database` for database queries (83% reduction on cached results) - Use `smart_cache_api` for API response caching with advanced strategies **Build & Test** + - Use `smart_test` to run only changed tests (incremental test selection) - Use `smart_lint` for incremental linting with auto-fix suggestions - Use `smart_build` for TypeScript builds with diff-based change detection **Advanced Caching** + - Use `smart_cache` for multi-tier caching with custom eviction strategies - Use `predictive_cache` for ML-based cache warming - Use `cache_analytics` to monitor cache performance and identify optimization opportunities **Monitoring & Dashboards** + - Use `alert_manager` to set up alerting for critical metrics - Use `metric_collector` to aggregate metrics from multiple sources - Use `data_visualizer` to create interactive charts and visualizations **System Operations** + - Use `smart_cron` to manage scheduled tasks - Use `smart_user` for user and permission management - Use `get_session_stats` and `analyze_project_tokens` to monitor token usage @@ -1527,7 +1616,7 @@ optimize_session({ ### Performance Tips 1. **Enable Caching**: Most tools default to caching enabled - keep it enabled for best performance -2. **Use Smart Tools**: Always use smart_* variants instead of standard tools (60-90% reduction) +2. **Use Smart Tools**: Always use smart\_\* variants instead of standard tools (60-90% reduction) 3. **Monitor Performance**: Use `get_session_stats` regularly to identify optimization opportunities 4. **Cache Large Content**: Use `optimize_text` for content >500 characters 5. **Use Batch Operations**: Many tools support batch operations for better performance @@ -1535,31 +1624,34 @@ optimize_session({ ### Common Patterns **File Reading Pattern**: + ```typescript // First read: full content -smart_read({ path: "/src/app.ts" }) +smart_read({ path: '/src/app.ts' }); // Subsequent reads: only changes (80% reduction) -smart_read({ path: "/src/app.ts" }) +smart_read({ path: '/src/app.ts' }); ``` **API Caching Pattern**: + ```typescript // First request: fetch and cache smart_api_fetch({ - method: "GET", - url: "https://api.example.com/data", - ttl: 300 -}) + method: 'GET', + url: 'https://api.example.com/data', + ttl: 300, +}); // Subsequent requests: cached (95% reduction) smart_api_fetch({ - method: "GET", - url: "https://api.example.com/data" -}) + method: 'GET', + url: 'https://api.example.com/data', +}); ``` **Session Monitoring Pattern**: + ```typescript // At the end of each session const stats = await get_session_stats({}); @@ -1577,20 +1669,25 @@ console.log(`Total project cost: $${projectStats.estimatedCost}`); ### Common Issues **Issue: Low cache hit rate** + - Solution: Use `cache_analytics` to identify cache misses and adjust TTL values **Issue: Compression not providing expected savings** + - Solution: Use `analyze_optimization` to check if content is suitable for compression **Issue: Tools returning stale data** + - Solution: Use `force: true` parameter to bypass cache and fetch fresh data **Issue: Session stats not tracking operations** + - Solution: Ensure global hooks are installed and enabled ### Getting Help For detailed troubleshooting and support: + - Check the main [README](../README.md) for installation and configuration - Review [Installation Guide](./HOOKS-INSTALLATION.md) for platform-specific issues - File an issue on GitHub with detailed error messages and reproduction steps diff --git a/docs/media/live/agent-accounting-live.png b/docs/media/live/agent-accounting-live.png new file mode 100644 index 000000000..e4341ec42 Binary files /dev/null and b/docs/media/live/agent-accounting-live.png differ diff --git a/docs/media/live/capture-health-live.png b/docs/media/live/capture-health-live.png new file mode 100644 index 000000000..1e31d84f4 Binary files /dev/null and b/docs/media/live/capture-health-live.png differ diff --git a/docs/media/live/evidence-console-live.png b/docs/media/live/evidence-console-live.png new file mode 100644 index 000000000..3da7cfc73 Binary files /dev/null and b/docs/media/live/evidence-console-live.png differ diff --git a/docs/media/live/graph-balance-live.png b/docs/media/live/graph-balance-live.png new file mode 100644 index 000000000..8742c06ed Binary files /dev/null and b/docs/media/live/graph-balance-live.png differ diff --git a/docs/media/live/graph-explorer-live.png b/docs/media/live/graph-explorer-live.png new file mode 100644 index 000000000..55802306d Binary files /dev/null and b/docs/media/live/graph-explorer-live.png differ diff --git a/docs/media/live/overview-live.png b/docs/media/live/overview-live.png new file mode 100644 index 000000000..5ff9684ea Binary files /dev/null and b/docs/media/live/overview-live.png differ diff --git a/evals/ucr/results/mcp-context-audit-v1.json b/evals/ucr/results/mcp-context-audit-v1.json index 876709f4b..7a3cb241c 100644 --- a/evals/ucr/results/mcp-context-audit-v1.json +++ b/evals/ucr/results/mcp-context-audit-v1.json @@ -1,8 +1,8 @@ { "schemaVersion": "ucr.mcp-context-audit/1", "evidenceClass": "native-tokenized-real-tools-list-conformance-not-model-effectiveness", - "executedAt": "2026-08-10T04:42:33.220Z", - "serverSourceHash": "1753baaa743ad320f491ac0d2d7a19354e23f664eb9e84a4a96b7a6895d89550", + "executedAt": "2026-08-12T13:32:02.466Z", + "serverSourceHash": "4795aae9db9dcbc7813618193220d01a641961a84940554b3c908c52a494650f", "surfaces": [ { "name": "baseline", @@ -13,7 +13,7 @@ "schemaBytes": 2, "schemaTokens": 1, "tokenAccounting": "tiktoken:cl100k_base", - "reductionVsFull": 0.9999668049792532, + "reductionVsFull": 0.9999669825337604, "shareOf128kContext": 0.0000078125, "shareOf1mContext": 0.000001 }, @@ -28,7 +28,7 @@ "schemaBytes": 382, "schemaTokens": 71, "tokenAccounting": "tiktoken:cl100k_base", - "reductionVsFull": 0.997643153526971, + "reductionVsFull": 0.9976557598969855, "shareOf128kContext": 0.0005546875, "shareOf1mContext": 0.000071 }, @@ -44,7 +44,7 @@ "schemaBytes": 2393, "schemaTokens": 480, "tokenAccounting": "tiktoken:cl100k_base", - "reductionVsFull": 0.9840663900414938, + "reductionVsFull": 0.9841516162049724, "shareOf128kContext": 0.00375, "shareOf1mContext": 0.00048 }, @@ -63,7 +63,7 @@ "schemaBytes": 3519, "schemaTokens": 694, "tokenAccounting": "tiktoken:cl100k_base", - "reductionVsFull": 0.9769626556016597, + "reductionVsFull": 0.9770858784296893, "shareOf128kContext": 0.005421875, "shareOf1mContext": 0.000694 }, @@ -92,12 +92,12 @@ "smart_grep", "get_optimization_report" ], - "schemaBytes": 23367, - "schemaTokens": 4815, + "schemaBytes": 24067, + "schemaTokens": 4977, "tokenAccounting": "tiktoken:cl100k_base", - "reductionVsFull": 0.8401659751037345, - "shareOf128kContext": 0.0376171875, - "shareOf1mContext": 0.004815 + "reductionVsFull": 0.8356720705253079, + "shareOf128kContext": 0.0388828125, + "shareOf1mContext": 0.004977 }, { "name": "full", @@ -209,12 +209,12 @@ "optimization_storage", "context_delta" ], - "schemaBytes": 146134, - "schemaTokens": 30125, + "schemaBytes": 146834, + "schemaTokens": 30287, "tokenAccounting": "tiktoken:cl100k_base", "reductionVsFull": 0, - "shareOf128kContext": 0.2353515625, - "shareOf1mContext": 0.030125 + "shareOf128kContext": 0.2366171875, + "shareOf1mContext": 0.030287 } ], "findings": { @@ -227,10 +227,10 @@ "fullCatalogTools": 103, "graphCaptureSchemaTokens": 480, "extendedCognitiveSchemaTokens": 694, - "defaultCoreSchemaTokens": 4815, - "fullCatalogSchemaTokens": 30125, - "graphCaptureReductionVsFull": 0.9840663900414938, - "graphCaptureReductionVsCore": 0.9003115264797508, + "defaultCoreSchemaTokens": 4977, + "fullCatalogSchemaTokens": 30287, + "graphCaptureReductionVsFull": 0.9841516162049724, + "graphCaptureReductionVsCore": 0.9035563592525617, "appliesToRegisteredClients": 16, "userMcpServersAreAdditive": "Every enabled MCP server adds its own tool schemas and instructions; client isolation must disable unrelated servers during evals." }, @@ -240,5 +240,5 @@ "client hosts may add wrappers, instructions, resources, or other MCP servers beyond this server response", "model effectiveness and empty-session p95 overhead require paired live provider runs" ], - "reportHash": "3841fd34a174c1b9e1822dbc21b570d1050ff2c2ff5b976252b95287d0b967ca" + "reportHash": "520517a3d28c3a0fef9eeb971e269a800e47f775134018cd1752be27a5d39e6a" } diff --git a/hooks-core/adapter.mjs b/hooks-core/adapter.mjs index 2d98bed73..fbad78edf 100644 --- a/hooks-core/adapter.mjs +++ b/hooks-core/adapter.mjs @@ -186,8 +186,143 @@ function contextOutput(client, eventName, additionalContext) { }; } +/** Convert one static JavaScript string literal without evaluating code. */ +function codexStringLiteral(literal) { + if (typeof literal !== 'string' || literal.length < 2) return null; + const quote = literal[0]; + if (!['"', "'", '`'].includes(quote) || literal.at(-1) !== quote) return null; + + let decoded = ''; + for (let index = 1; index < literal.length - 1; index += 1) { + const character = literal[index]; + if (quote === '`' && character === '$' && literal[index + 1] === '{') + return null; + if (character !== '\\') { + decoded += character; + continue; + } + + index += 1; + if (index >= literal.length - 1) return null; + const escaped = literal[index]; + const simple = { + b: '\b', f: '\f', n: '\n', r: '\r', t: '\t', v: '\v', 0: '\0', + '\\': '\\', "'": "'", '"': '"', '`': '`', '$': '$', + }; + if (Object.hasOwn(simple, escaped)) { + decoded += simple[escaped]; + continue; + } + if (escaped === '\n') continue; + if (escaped === '\r') { + if (literal[index + 1] === '\n') index += 1; + continue; + } + if (escaped === 'x') { + const digits = literal.slice(index + 1, index + 3); + if (!/^[0-9a-f]{2}$/i.test(digits)) return null; + decoded += String.fromCodePoint(Number.parseInt(digits, 16)); + index += 2; + continue; + } + if (escaped === 'u') { + const braced = literal[index + 1] === '{'; + const close = braced ? literal.indexOf('}', index + 2) : index + 5; + const digits = braced + ? literal.slice(index + 2, close) + : literal.slice(index + 1, close); + if ( + close < 0 || + !(braced ? /^[0-9a-f]{1,6}$/i : /^[0-9a-f]{4}$/i).test(digits) + ) return null; + const codePoint = Number.parseInt(digits, 16); + if (codePoint > 0x10ffff) return null; + decoded += String.fromCodePoint(codePoint); + index = close; + continue; + } + // JavaScript identity escapes drop the slash (for example, '\q' is 'q'). + decoded += escaped; + } + return decoded; +} + /** Convert client-specific lifecycle envelopes into the common tool shape. */ +function codexStringBindings(source) { + const values = new Map(); + const declaration = /\b(?:const|let|var)\s+([A-Za-z_$][\w$]*)\s*=\s*((?:"(?:\\.|[^"\\])*")|(?:'(?:\\.|[^'\\])*')|(?:`(?:\\.|[^`\\])*`))/gs; + for (const match of String(source || '').matchAll(declaration)) { + try { + const value = codexStringLiteral(match[2]); + if (value !== null) values.set(match[1], value); + } catch { + // A computed or malformed JavaScript expression is not safe to execute + // merely to understand a hook envelope. Leave it opaque. + } + } + return values; +} + +function codexCallArguments(source, method) { + const calls = []; + const pattern = new RegExp(`(?:tools\\.)?${method}\\s*\\(\\s*([^),]+)`, 'gi'); + for (const match of String(source || '').matchAll(pattern)) + calls.push(match[1].trim()); + return calls; +} + +function codexLiteral(value, bindings) { + if (bindings.has(value)) return String(bindings.get(value)); + return codexStringLiteral(value); +} + +function codexExecCommands(source, bindings) { + const commands = []; + for (const call of String(source || '').matchAll( + /(?:tools\.)?exec_command\s*\(\s*\{([\s\S]*?)\}\s*\)/gi + )) { + const property = /\bcmd\s*:\s*((?:"(?:\\.|[^"\\])*")|(?:'(?:\\.|[^'\\])*')|(?:`(?:\\.|[^`\\])*`)|(?:[A-Za-z_$][\w$]*))/s.exec(call[1]); + if (!property) continue; + const command = codexLiteral(property[1], bindings); + if (command) commands.push(command); + } + return commands; +} + export function normalizeClientPayload(clientName, event, raw) { + if (clientName === 'codex') { + const outerName = String(raw.tool_name ?? raw.toolName ?? raw.tool ?? ''); + if (/^(?:functions\.)?exec$/i.test(outerName)) { + const envelope = raw.tool_input ?? raw.toolInput ?? raw.arguments ?? raw.args; + const source = + typeof envelope === 'string' + ? envelope + : envelope?.code ?? envelope?.input ?? envelope?.source ?? ''; + const bindings = codexStringBindings(source); + const patchCalls = codexCallArguments(source, 'apply_patch'); + const patch = patchCalls + .map((argument) => codexLiteral(argument, bindings)) + .find(Boolean); + const mutation = patchCalls.length > 0; + const commands = codexExecCommands(source, bindings); + + // `functions.exec` is also the orchestration envelope for web, image and + // other non-filesystem tools. Do not reinterpret those as shell commands: + // doing so produced irrelevant cross-project advice and fabricated graph + // activity for operations the filesystem hooks never observed. + if (!mutation && !commands.length) return raw; + return { + ...raw, + tool_name: mutation ? 'apply_patch' : 'run_command', + tool_input: { + ...(envelope && typeof envelope === 'object' ? envelope : {}), + command: String(patch || commands.join('\n') || source || ''), + code_mode_envelope: true, + }, + }; + } + } + if (clientName === 'cline') { const body = event === 'post-tool' ? raw.postToolUse : raw.preToolUse; if (!body) return raw; @@ -383,6 +518,22 @@ function projectBriefing() { function observeAndInject(payload, state, episode, features) { const touched = touchedFiles(payload); const dirFor = (path) => wikiDir(projectRootFor(path, payload.cwd)); + const registerRoot = (root) => { + const dir = wikiDir(root); + registerProject({ + root, + graphDir: dir, + client: episode.client || 'unknown', + }); + return dir; + }; + + // SessionStart is not delivered consistently by every host/version. The + // graph was still written in that case, but the dashboard registry never + // learned it existed. Register every repository observed by a real tool call + // as a second, idempotent production path. + for (const { path } of touched) + registerRoot(projectRootFor(path, payload.cwd)); const bytes = readCostBytes(payload); if (bytes && payload.tool_input.file_path) { @@ -423,7 +574,7 @@ function observeAndInject(payload, state, episode, features) { const command = payload.tool_input?.command; if (command) { const root = commandProjectRoot(payload, payload.cwd); - const dir = wikiDir(root); + const dir = registerRoot(root); const local = forCommand(dir, load(dir), command, { sessionId: payload.session_id, alreadyInjected, @@ -748,7 +899,14 @@ async function runHook(clientName, event, invocation) { client.canDeny && event === 'pre-tool' && !repeat && - mode() !== MODE_ADVISE + mode() !== MODE_ADVISE && + // Codex code mode presents an orchestration program as one outer + // `functions.exec` call. Refusing that envelope is rendered by the host + // as a failed script and can discard several otherwise-safe nested + // operations. Observe it, capture it and advise, but reserve a hard veto + // for legacy one-operation Codex tool calls where the denied operation is + // unambiguous. + !(clientName === 'codex' && payload.tool_input?.code_mode_envelope) ); if (canRefuse) { @@ -757,19 +915,23 @@ async function runHook(clientName, event, invocation) { // Every client's refusal carries the off switch, for the same reason Claude // Code's does: enforcement that hides its own disable is coercive. if (client.denyStyle === 'top-level') { + invocation.block('policy_denied'); emit({ decision: 'deny', reason: withEscape(verdict.reason) }); } else if (client.denyStyle === 'top-level-permission') { + invocation.block('policy_denied'); emit({ permissionDecision: 'deny', permissionDecisionReason: withEscape(verdict.reason), }); } else if (client.denyStyle === 'cline') { + invocation.block('policy_denied'); emit({ cancel: true, contextModification: '', errorMessage: withEscape(verdict.reason), }); } else if (client.denyStyle === 'cursor') { + invocation.block('policy_denied'); emit({ continue: true, permission: 'deny', @@ -778,9 +940,11 @@ async function runHook(clientName, event, invocation) { 'Token Optimizer redirected an expensive built-in operation.', }); } else if (client.denyStyle === 'exit-2') { + invocation.block('policy_denied'); process.stderr.write(withEscape(verdict.reason)); process.exit(2); } else { + invocation.block('policy_denied'); emit({ hookSpecificOutput: { hookEventName: eventName, diff --git a/hooks-core/audit.mjs b/hooks-core/audit.mjs index 62f95126a..87c54a6cc 100644 --- a/hooks-core/audit.mjs +++ b/hooks-core/audit.mjs @@ -48,15 +48,17 @@ export function decline(dir, id) { export function declines(dir, { events = readMetrics(dir) } = {}) { const counts = new Map(); for (const event of events) { - if (event.kind !== 'advice' || event.action !== 'declined' || !event.id) continue; + if (event.kind !== 'advice' || event.action !== 'declined' || !event.id) + continue; counts.set(event.id, (counts.get(event.id) || 0) + 1); } return counts; } -const idOf = (finding) => finding.remedy - ? `${finding.remedy.type}:${finding.remedy.anchor || finding.remedy.file || (finding.remedy.anchors || []).join(',')}` - : `${finding.id}:${finding.anchor || finding.file || ''}`; +const idOf = (finding) => + finding.remedy + ? `${finding.remedy.type}:${finding.remedy.anchor || finding.remedy.file || (finding.remedy.anchors || []).join(',')}` + : `${finding.id}:${finding.anchor || finding.file || ''}`; /** * Whether a habit improved after we said something about it. @@ -66,12 +68,18 @@ const idOf = (finding) => finding.remedy * -- a trend computed from one session on each side is a coin flip with a * percentage sign. */ -export function habitTrend(dir, detector, { events = readMetrics(dir), minSessions = 2, anchors = null } = {}) { +export function habitTrend( + dir, + detector, + { events = readMetrics(dir), minSessions = 2, anchors = null } = {} +) { // SPLIT BY POSITION, NOT BY TIMESTAMP. The log is append-only, so its order is // authoritative -- while `at` has millisecond granularity, and a burst of // events inside one millisecond would land on the wrong side of the split or // collapse one side to nothing. Position is exact where the clock is not. - const raisedAt = events.findIndex((e) => e.kind === 'advice' && e.detector === detector); + const raisedAt = events.findIndex( + (e) => e.kind === 'advice' && e.detector === detector + ); if (raisedAt === -1) return null; // SCOPED TO THE FILES THIS DETECTOR NAMED. Counting every read in the window @@ -112,7 +120,12 @@ export function habitTrend(dir, detector, { events = readMetrics(dir), minSessio /** Marks a recommendation as having been raised, so its effect can be scored. */ export function raise(dir, finding) { - record(dir, { kind: 'advice', action: 'raised', id: idOf(finding), detector: finding.id }); + record(dir, { + kind: 'advice', + action: 'raised', + id: idOf(finding), + detector: finding.id, + }); } /** @@ -121,7 +134,11 @@ export function raise(dir, finding) { * `findings` comes from the detectors; `extra` lets the cache and routing * modules contribute without this file importing the world. */ -export function buildQueue(dir, findings = [], { events = readMetrics(dir) } = {}) { +export function buildQueue( + dir, + findings = [], + { events = readMetrics(dir) } = {} +) { const declined = declines(dir, { events }); const ledger = remedyLedger(dir); const applied = new Set(ledger.filter((r) => !r.revertedAt).map((r) => r.id)); @@ -144,7 +161,9 @@ export function buildQueue(dir, findings = [], { events = readMetrics(dir) } = { } return { - queue: queue.sort((a, b) => (b.costPerSession ?? 0) - (a.costPerSession ?? 0)), + queue: queue.sort( + (a, b) => (b.costPerSession ?? 0) - (a.costPerSession ?? 0) + ), suppressed, done: ledger.filter((r) => !r.revertedAt), }; @@ -159,7 +178,11 @@ export function buildQueue(dir, findings = [], { events = readMetrics(dir) } = { * many were withheld -- and what they are collectively worth -- keeps that from * being a silent cap. */ -export function renderAudit(dir, findings = [], { tier = 'opus', full = false, sessionsPerMonth = 60 } = {}) { +export function renderAudit( + dir, + findings = [], + { tier = 'opus', full = false, sessionsPerMonth = 60 } = {} +) { const { queue, suppressed, done } = buildQueue(dir, findings); const lines = []; @@ -173,22 +196,29 @@ export function renderAudit(dir, findings = [], { tier = 'opus', full = false, s // read as "this costs nothing" beside a finding whose cost we simply do not // know -- the same unknown-becomes-zero error the rest of this project // corrects, in the one unit that gets quoted to other people. - const priced = item.costPerSession == null ? null : monthly(cost, { tier, sessionsPerMonth }); + const priced = + item.costPerSession == null + ? null + : monthly(cost, { tier, sessionsPerMonth }); // The id appears on EVERY actionable line, not just the appliable ones. It is the only // handle `decline` accepts and it cannot be guessed from the title, so omitting it made the // advertised decline path unreachable for precisely the findings most likely to be // unwanted -- model-routing findings carry no remedy, so they could never be suppressed no // matter how many times a user declined them. - const action = item.remedy?.kind === 'ours' ? `apply: waste_audit action="apply" id="${item.id}"` - : item.remedy?.kind === 'yours' ? `proposed edit -- needs your yes, nothing changed; decline: ${item.id}` - : `advice only -- no automatic fix; decline: ${item.id}`; + const action = + item.remedy?.kind === 'ours' + ? `apply: waste_audit action="apply" id="${item.id}"` + : item.remedy?.kind === 'yours' + ? `proposed edit -- needs your yes, nothing changed; decline: ${item.id}` + : `advice only -- no automatic fix; decline: ${item.id}`; // MEASURED ZERO IS NOT UNMEASURED. Testing `cost` for truthiness sent a real 0 down the // "not yet measurable" branch while `priced` above, which tests for null, still rendered // $0.00 beside it -- producing `cost not yet measurable (~$0.00/month)`, the exact string // the test suite declares must never appear. waste.mjs defaults every finding to 0 and // hard-sets it on the co-occurrence detector, so this is reachable, not theoretical. - const text = ` ${item.title}\n ${item.costPerSession != null ? `${cost.toLocaleString()} tokens/session` : 'cost not yet measurable'}` + + const text = + ` ${item.title}\n ${item.costPerSession != null ? `${cost.toLocaleString()} tokens/session` : 'cost not yet measurable'}` + `${priced ? ` (~${money(priced.amount)}/month)` : ''}; ${action}`; const printCost = estimate(text); @@ -209,14 +239,19 @@ export function renderAudit(dir, findings = [], { tier = 'opus', full = false, s lines.push(text); } - const head = shown.length ? ['What to do next, most expensive first:', ...lines] : ['Nothing addressable found.']; + const head = shown.length + ? ['What to do next, most expensive first:', ...lines] + : ['Nothing addressable found.']; const body = [...head]; if (withheld.length) { const worth = withheld.reduce((sum, w) => sum + (w.costPerSession || 0), 0); - body.push('', ` ... ${withheld.length} more finding(s) worth ${worth.toLocaleString()} tokens/session in total, ` + - 'not shown -- printing them costs more than they are worth. Pass full=true to see all.'); + body.push( + '', + ` ... ${withheld.length} more finding(s) worth ${worth.toLocaleString()} tokens/session in total, ` + + 'not shown -- printing them costs more than they are worth. Pass full=true to see all.' + ); } // What we already told you, and what it bought. @@ -224,23 +259,35 @@ export function renderAudit(dir, findings = [], { tier = 'opus', full = false, s body.push('', 'Already applied, and what it actually saved:'); for (const rule of done.slice(0, 6)) { const saved = rule.savedPerSession; - const priced = saved == null ? null : monthly(saved, { tier, sessionsPerMonth }); - body.push(` + ${rule.id} -- ${saved == null - ? 'not yet measurable (fewer than two sessions since)' - : `measured ${saved.toLocaleString()} tokens/session${priced ? `, ~${money(priced.amount)}/month` : ''}`}`); + const priced = + saved == null ? null : monthly(saved, { tier, sessionsPerMonth }); + body.push( + ` + ${rule.id} -- ${ + saved == null + ? 'not yet measurable (fewer than two sessions since)' + : `measured ${saved.toLocaleString()} tokens/session${priced ? `, ~${money(priced.amount)}/month` : ''}` + }` + ); } // Never a silent cap: the withheld block above states its remainder and so must this one. // Truncating to six with no disclosure showed a user six savings and let them conclude that // was everything the tool had bought them, which understates its own measured value. if (done.length > 6) { - body.push(` ... and ${done.length - 6} more applied fix(es), not shown.`); + body.push( + ` ... and ${done.length - 6} more applied fix(es), not shown.` + ); } } if (suppressed.length) { - body.push('', `Not repeating ${suppressed.length} recommendation(s) you have declined ` + - `${DECLINE_LIMIT}+ times. Ask for full=true to see them.`); - if (full) for (const item of suppressed) body.push(` - ${item.title} (declined ${item.times}x)`); + body.push( + '', + `Not repeating ${suppressed.length} recommendation(s) you have declined ` + + `${DECLINE_LIMIT}+ times. Ask for full=true to see them.` + ); + if (full) + for (const item of suppressed) + body.push(` - ${item.title} (declined ${item.times}x)`); } // Whether the advice changed anything. @@ -254,20 +301,30 @@ export function renderAudit(dir, findings = [], { tier = 'opus', full = false, s for (const a of anchors) anchorsBy.get(f.id).add(a); } const trends = [...new Set(findings.map((f) => f.id))] - .map((detector) => habitTrend(dir, detector, { - anchors: anchorsBy.has(detector) ? [...anchorsBy.get(detector)] : null, - })) + .map((detector) => + habitTrend(dir, detector, { + anchors: anchorsBy.has(detector) ? [...anchorsBy.get(detector)] : null, + }) + ) .filter(Boolean); if (trends.length) { body.push('', 'Since the advice was given:'); for (const trend of trends) { - body.push(` ${trend.detector}: ${trend.before.toLocaleString()} -> ${trend.after.toLocaleString()} tokens/session ` + - `(${trend.improved ? 'improved' : 'worse'})`); + body.push( + ` ${trend.detector}: ${trend.before.toLocaleString()} -> ${trend.after.toLocaleString()} tokens/session ` + + `(${trend.improved ? 'improved' : 'worse'})` + ); } } - const addressable = queue.reduce((sum, item) => sum + (item.costPerSession || 0), 0); + const addressable = queue.reduce( + (sum, item) => sum + (item.costPerSession || 0), + 0 + ); + const addressableMonthly = addressable + ? monthly(addressable, { tier, sessionsPerMonth }) + : null; const note = priceNote(tier); if (note) body.push('', note); @@ -276,9 +333,10 @@ export function renderAudit(dir, findings = [], { tier = 'opus', full = false, s // pushing it left the report's longest line out of its own reported cost, understating it by // 10-20% on a short audit. This figure exists to prove the audit is not a net loss, so // understating the cost side biases exactly the comparison it was written to be honest about. - const closing = (n) => `This report cost about ${n.toLocaleString()} tokens and names ` + + const closing = (n) => + `This report cost about ${n.toLocaleString()} tokens and names ` + `${addressable.toLocaleString()} tokens/session of addressable waste` + - `${addressable ? ` (~${money(monthly(addressable, { tier, sessionsPerMonth })?.amount)}/month across ${sessionsPerMonth} sessions)` : ''}.`; + `${addressableMonthly ? ` (~${money(addressableMonthly.amount)}/month across ${sessionsPerMonth} sessions)` : ''}.`; const selfCost = estimate([...body, '', closing(0)].join('\n')); body.push('', closing(selfCost)); diff --git a/hooks-core/cache.mjs b/hooks-core/cache.mjs index 25ef1b38e..c8436dee6 100644 --- a/hooks-core/cache.mjs +++ b/hooks-core/cache.mjs @@ -1,12 +1,12 @@ /** * Prompt-cache economics. * - * Cache economics is real money in a way most compression is not: a cache read - * costs a tenth of a fresh token and a cache WRITE costs a quarter more than - * one, so a prefix that keeps invalidating can cost more than every saving this - * product makes elsewhere. It is also the one area where we do not have to - * model anything -- the client's own transcript records cache_read_input_tokens - * and cache_creation_input_tokens per turn, which is ground truth. + * Anthropic prompt-cache usage, read from Claude Code transcripts. A cache read + * and a cache write are both billable, at different published multipliers from + * uncached input. Raw cache_read_input_tokens and + * cache_creation_input_tokens are observations. Any multiplier-based value is + * an Anthropic input-cost equivalent, not a universally comparable token count + * and not a provider invoice. * * MEASUREMENT ALONE IS NOT ACTIONABLE. A hit rate tells you the cache missed; * it cannot tell you why, and an unactionable number is the same dead thing as @@ -28,7 +28,15 @@ * cache-safety-by-construction half of this file. */ -import { readFileSync, readdirSync, statSync, existsSync, openSync, readSync, closeSync } from 'node:fs'; +import { + readFileSync, + readdirSync, + statSync, + existsSync, + openSync, + readSync, + closeSync, +} from 'node:fs'; import { join } from 'node:path'; import { homedir } from 'node:os'; @@ -49,7 +57,8 @@ export const READ_MULTIPLIER = 0.1; const SYNTHETIC_MODEL = 'Saved so far
-Token accounting
++ Gross payload reductions, later expansions, observed returns, + quarantined reports, and graph estimates stay separate. +
+Loading measured token accounting…
++ Provider usage & price +
++ Native uncached input, cache reads, cache writes, and output from + local CLI transcripts, deduplicated by provider request. +
+Loading native provider usage…
+| CLI & model | +Requests | +Uncached input | +Cache read | +Cache write | +Output | +API-price equivalent | +
|---|
+ Measured by agent +
++ New optimizer measurements use MCP handshake identity. Historical rows + without identity remain unattributed instead of being guessed. +
+Loading agent attribution…
+@@ -124,12 +228,14 @@ ? Lifecycle activity is grouped by CLI when cross-client telemetry - is available; older clients may report context categories instead. + is available; older clients may report context categories + instead.
- Cross-client observations are used instead of a single CLI's stale session file. + Cross-client observations are used instead of a single CLI's stale + session file.
- Ranked by observed calls; no token amount is invented when a CLI omits it. + Ranked by observed calls; no token amount is invented when a CLI + omits it.
Recent agent activity
+Recent measured optimizer activity
- What the active CLI actually did, most recent first. + Verified reductions, observed returns, and excluded historical claims, + most recent first.