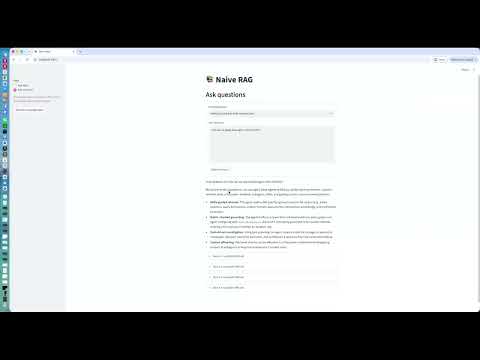
A learning project focused on backend RAG implementation and techniques, from document ingestion to retrieval and answer generation. The backend was primarily implemented by me, with some GitHub Copilot assistance. The Streamlit frontend was primarily generated with Codex assistance to demonstrate frontend-backend integration.
- Document ingestion: pasted text and PDF, DOCX, TXT, and Markdown uploads, with source metadata retained.
- LangChain: recursive character splitting with configurable chunk size and overlap, plus prompt and generation orchestration.
- Gemini and FAISS: Google Gemini embeddings, top-k vector similarity search within a selected knowledge base, and Gemini answer generation prompted to use the retrieved context. Responses include retrieved chunks and source metadata.
- FastAPI, Streamlit, and Docker Compose: a backend API, an integration demo UI, and containerized startup for both services.
Knowledge bases and vector indexes are stored in memory and cleared when the backend restarts.
Install Docker with Docker Compose, then run from the project root:
cp .env.example .envSet GOOGLE_API_KEY in .env to your Gemini API key. Keep the remaining required settings, and set GEMINI_MODEL and EMBEDDING_MODEL to models available to your account. Compose configures the frontend API URL automatically.
docker compose up --build- Frontend: http://localhost:8501
- Backend: http://localhost:8000
- FastAPI docs: http://localhost:8000/docs