English | 简体中文 | 日本語 | 한국어 | Español | Français | Português | हिन्दी
Community continuation of
codexstar69/pi-listen(upstream, MIT — dormant since v7.2.2 in May 2026). Not affiliated with the original author. Old name:pi-listen.
Voice in and voice out for Pi. Hold-to-talk STT — Deepgram streaming (cloud) or 21 offline models — plus TTS that speaks the agent's replies (Kitten, Kokoro, Piper, or Deepgram Aura).


v0.1.3 — current release — audio capture prefers
ffmpegwhenPULSE_SERVERis set (SSH audio tunnel / remote PulseAudio), so remote microphones record reliably. Voice in and voice out: 21 offline STT models, 20 local TTS voices plus Deepgram Aura, driven by one/voice-settingspanel with 6 tabs. The 0.1.x line is documented in the changelog.
Click to watch the demo video
# In a regular terminal (not inside Pi)
pi install npm:pi-voicekitpi-voicekit supports two transcription backends:
| Deepgram (cloud) | Local models (offline recognition) | |
|---|---|---|
| How it works | Live streaming — text appears as you speak | Batch mode — transcribes after you finish recording |
| Setup | API key required | No API key, models auto-download on first use |
| Internet | Required | Not required after model download for recognition; the polish step may use the network |
| Latency | Real-time interim results | 2–10 seconds after recording stops |
| Languages | 56+ with live streaming | Depends on model (1–57 languages) |
| Cost | $200 free credit (lasts 6–12 months for most developers) | Recognition is free; the polish step may cost money |
Run /voice-settings inside Pi to choose your backend and configure everything from one panel.
Sign up at dpgr.am/pi-voice — $200 free credit, no card needed.
export DEEPGRAM_API_KEY="your-key-here" # add to ~/.zshrc or ~/.bashrcNo setup needed — run /voice-settings, switch backend to Local, and select a model. It downloads automatically.
Note: Local models use batch mode — they transcribe after you finish recording, not while you speak. For live streaming as you speak, use Deepgram.
On first launch, pi-voicekit checks your setup and tells you what's ready:
- Backend configured (Deepgram key or local model)
- Audio capture tool detected (sox, ffmpeg, or arecord)
- If everything checks out, voice activates immediately
pi-voicekit auto-detects your audio tool. No manual install needed if you already have sox or ffmpeg.
| Priority | Tool | Platforms | Install |
|---|---|---|---|
| 1 | SoX (rec) |
macOS, Linux, Windows | brew install sox / apt install sox / choco install sox |
| 2 | ffmpeg | macOS, Linux, Windows | brew install ffmpeg / apt install ffmpeg |
| 3 | arecord | Linux only | Pre-installed (ALSA) |
When
PULSE_SERVERis set (SSH audio tunnel or remote PulseAudio) the order becomes ffmpeg → sox → arecord — network Pulse sources need ffmpeg.
All configuration lives in one place: /voice-settings. Six tabs cover everything you need.
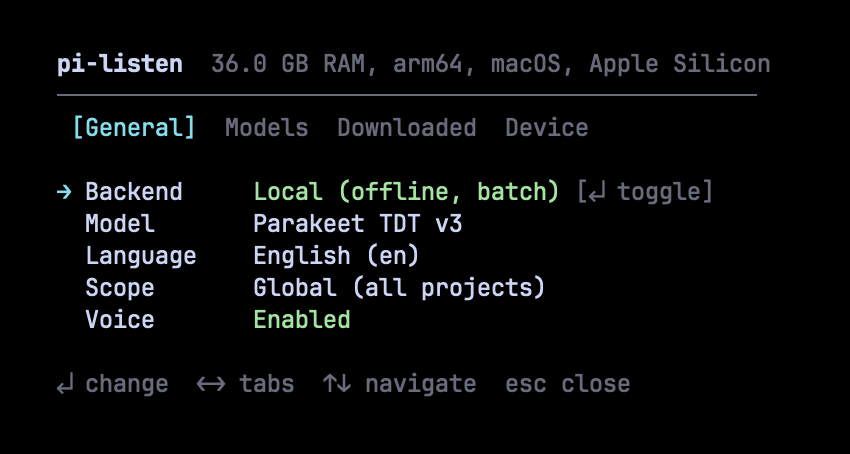
Toggle between Deepgram (cloud, live streaming) and Local (offline, batch mode). Change language, scope, and enable/disable voice — all with keyboard shortcuts.
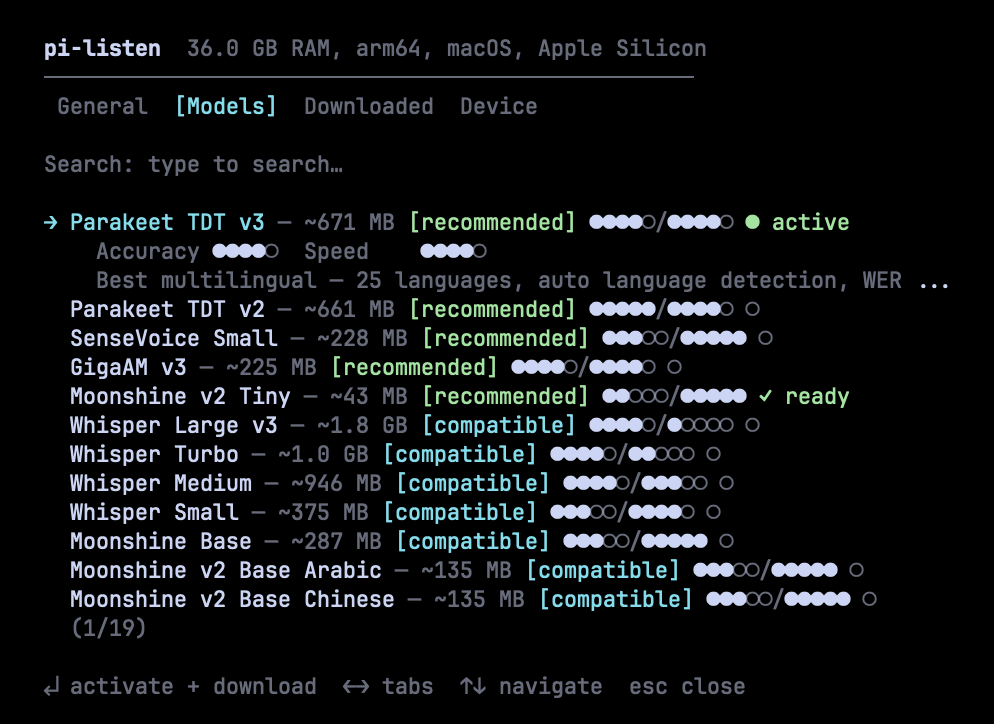
Browse 21 models from Parakeet, Whisper, Moonshine, SenseVoice, GigaAM, Paraformer, and Qwen3. Each model shows accuracy and speed ratings (●●●●○/●●●●○), fitness badges, and download status. Fuzzy search to find models fast. Press Enter to activate and download.
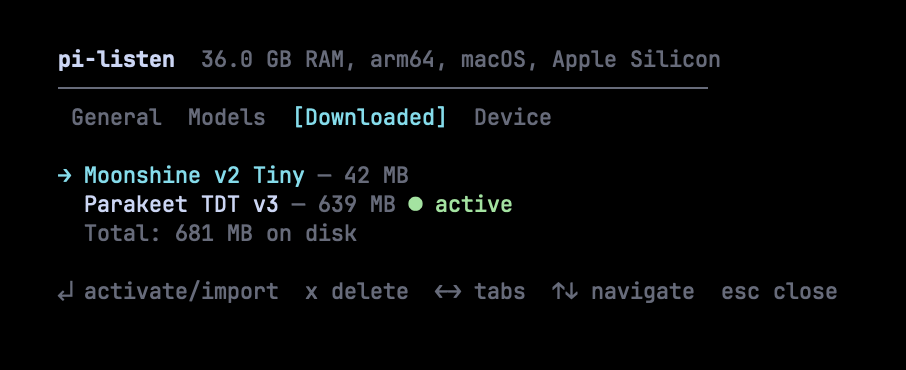
See what's installed, total disk usage, and which model is active. Press Enter to activate, x to delete. Models from Handy are auto-detected and can be imported without re-downloading.
Pick a TTS backend (local sherpa-onnx or Deepgram Aura), browse 20 local voices from ~13 MB, download on selection, and choose a voice per backend. Auto-speak of agent replies is toggled here.
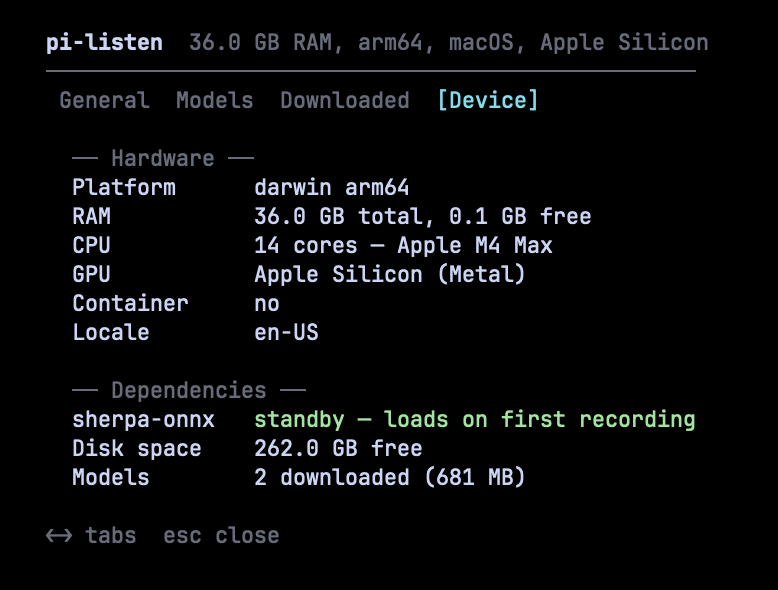
See your hardware profile (RAM, CPU, GPU), dependency status (sherpa-onnx runtime), available disk space, and total downloaded models. Model recommendations are based on this profile.
Optional post-ASR cleanup, on by default. Toggle it, pick the model, set how many
recent conversation turns accompany the transcript (0–10), and cap how long one
pass may take (1000–30000 ms). The last row shows the most recent polished
dictation as a RAW / POLISHED pair. /voice-polish last prints the newest
dictation a pass ran on — including one whose result was discarded — with its
STATUS, RAW, and WRITTEN text, or says that nothing was written.
/voice-polish takes on, off, model, turns <0-10>, last and restore;
run it with no argument for the current status.
| Action | Key | Notes |
|---|---|---|
| Record to editor | Hold SPACE (≥0.7s) |
Release to finalize. Pre-records during warmup so you don't miss words. |
| Toggle recording | Ctrl+Shift+V |
Works in all terminals — press to start, press again to stop. |
| Clear editor | Escape × 2 |
Double-tap within 500ms to clear all text. |
- Hold SPACE — warmup countdown appears, audio capture starts immediately (pre-recording)
- Keep holding — live transcription streams into the editor (Deepgram) or audio buffers (local)
- Release SPACE — recording continues for 1.5s (tail recording) to catch your last word, then finalizes
- Text appears in the editor, ready to send
| Command | Description |
|---|---|
/voice-settings |
Settings panel — backend, models, language, scope, device |
/voice-models |
Settings panel (Models tab) |
/voice-setup |
Run the first-run setup wizard |
/voice-language |
Open the settings panel to change language |
/voice-speak <text> |
Speak text out loud (TTS) |
/voice-speak-test |
Speak a sample sentence |
/voice-speak-toggle |
Enable / disable TTS |
/voice-stream |
Toggle Deepgram streaming TTS (cloud) |
/voice-speak-stop |
Stop in-flight TTS playback |
/voice-autosubmit |
Toggle: STT text auto-sent to the agent (on/off) |
/voice-polish [sub] |
Transcript polish: on, off, model, turns, last, restore |
/voice-hold-delay |
Set hold-to-talk delay (200-3000 ms, default 700) |
/voice-speak-models |
Browse / install TTS voice models |
/voice-speak-info |
Diagnose TTS state |
/voice-help |
Keyboard + command reference (or press F1) |
/voice test |
Full diagnostics — audio tool, mic, API key |
/voice on / off |
Enable or disable voice |
/voice dictate |
Continuous dictation (no key hold) |
/voice stop |
Stop active recording or dictation |
/voice history |
Recent transcriptions |
/voice |
Toggle on/off |
While in the settings panel:
| Key | Action |
|---|---|
← → |
switch tab |
↑ ↓ |
navigate row (skips group headings) |
↵ |
select / activate |
esc |
back to main / close panel |
type |
filter (search) |
bksp |
clear last search char |
While an install widget or playback indicator is mounted (no overlay in front):
| Key | Action |
|---|---|
esc |
cancel active install (most-recent first), then stop playback |
F1 |
open help overlay (always available) |
21 models across 7 families. Sorted by quality — best models first.
| Model | Accuracy | Speed | Size | Languages | Notes |
|---|---|---|---|---|---|
| Parakeet TDT v3 | ●●●●○ | ●●●●○ | 671 MB | 25 (auto-detect) | Best overall. WER 6.3%. |
| Parakeet TDT v2 | ●●●●● | ●●●●○ | 661 MB | English | Best English. WER 6.0%. |
| Whisper Turbo | ●●●●○ | ●●○○○ | 1.0 GB | 57 | Broadest language support. |
| Model | Accuracy | Speed | Size | Languages | Notes |
|---|---|---|---|---|---|
| Moonshine v2 Tiny | ●●○○○ | ●●●●● | 43 MB | English | 34ms latency. Raspberry Pi friendly. |
| Moonshine Base | ●●●○○ | ●●●●● | 287 MB | English | Handles accents well. |
| SenseVoice Small | ●●●○○ | ●●●●● | 228 MB | zh/en/ja/ko/yue | Best for CJK languages. |
| Model | Accuracy | Speed | Size | Languages | Notes |
|---|---|---|---|---|---|
| GigaAM v3 | ●●●●○ | ●●●●○ | 225 MB | Russian | 50% lower WER than Whisper on Russian. |
| Whisper Medium | ●●●●○ | ●●●○○ | 946 MB | 57 | Good accuracy, medium speed. |
| Whisper Large v3 | ●●●●○ | ●○○○○ | 1.8 GB | 57 | Highest Whisper accuracy. Slow on CPU. |
Plus 8 language-specialized Moonshine v2 variants for Japanese, Korean, Arabic, Chinese, Ukrainian, Vietnamese, and Spanish.
Hold SPACE → audio captured to memory buffer
                ↓
Release SPACE → buffer sent to sherpa-onnx (in-process)
                ↓
         ONNX inference on CPU (2–10 seconds)
                ↓
         Final transcript inserted into editor
Models download automatically on first use. Downloads are resumable, verified after completion, and deduplicated (no double-downloads). The settings panel shows real-time download progress with speed and ETA.
Models from Handy (~/Library/Application Support/com.pais.handy/models/) are auto-detected and can be imported via symlink (zero disk duplication).
Measured on the maintainer's machine, local CPU, no network, over 70 published utterances (28 Chinese, 28 English, 14 mixed Chinese–English). RTF is processing time divided by audio duration — lower is better, and below 1.0 is faster than real time.
| Recogniser | Chinese RTF | English RTF | Mixed RTF | Characters per second |
|---|---|---|---|---|
| paraformer-zh | 0.014 | 0.013 | 0.016 | 247–983 |
| sensevoice-small | 0.028 | 0.029 | 0.040 | 134–451 |
| whisper-turbo | 0.372 | 0.369 | 0.395 | 7–27 |
End to end — local recognition plus the remote polish call — four real dictations of
8.1–28.0 s came back in an estimated 0.56–2.98 s, an RTF of 0.07–0.15 (recognition time is
derived from the measured recognition RTF, not timed per dictation: see docs/BENCHMARKS.md).
The segmented polish pass is what
keeps that together: the 0.2.x line polished in one call over the whole transcript, so one
slow call returned the dictation unpolished, while against a degraded endpoint the segmented
pipeline polished 35 of 35 segments where the old path fell back on 100% of the run.
whisper-turbo is the slowest of the three by an order of magnitude and the least accurate
on this corpus — measured for comparison, not recommended for CPU-only use.
Protocol, all result tables, reproduction commands and the honest limits live in docs/BENCHMARKS.md — GitHub only, because npm ships the extension and this README.
| Feature | Description |
|---|---|
| Dual backend | Deepgram (cloud, live streaming) or local models (offline, batch) — switch in settings |
| 21 local models | Parakeet, Whisper, Moonshine, SenseVoice, GigaAM, Paraformer, Qwen3 — with accuracy/speed ratings |
| Unified settings panel | One overlay panel for all configuration — /voice-settings |
| Device-aware recommendations | Scores models against your hardware. Only best-in-class models get [recommended]. |
| Enterprise download pipeline | Pre-checks (disk, network, permissions), live progress with speed/ETA, post-verification |
| Handy integration | Auto-detects models from Handy app, imports via symlink |
| Audio fallback chain | Tries sox → ffmpeg → arecord in order — ffmpeg first when PULSE_SERVER is set |
| Pre-recording | Audio capture starts during warmup — you never miss the first word |
| Tail recording | Keeps recording 1.5s after release so your last word isn't clipped |
| Live streaming | Deepgram Nova 3 WebSocket (Nova 2 for Chinese locales) — live interim transcripts |
| Transcript polish | Optional post-ASR cleanup — the local backend polishes each recogniser segment as it is decoded (up to three calls in flight); the last N conversation turns (default 2) are sent with the first segment, and no conversation context at all when the turn count is zero. Disable with /voice-polish off |
| 56+ languages | Deepgram: 56+ with live streaming. Local: up to 57 depending on model. |
| Continuous dictation | /voice dictate for long-form input without holding keys |
| Typing cooldown | Space holds within 400ms of typing are ignored |
| Sound feedback | macOS system sounds for start, stop, and error events |
| Cross-platform | macOS, Windows, Linux — Kitty protocol + non-Kitty fallback |
# core
extensions/voice.ts                         Main extension — state machine, recording, UI, command surface
extensions/voice/config.ts                  Config loading, saving, migration
extensions/voice/onboarding.ts              First-run wizard, language picker
extensions/voice/audio-tool.ts              Capture tool detection (sox / ffmpeg / arecord)
extensions/voice/hold-to-talk.ts            Hold detection, Kitty and non-Kitty terminals
extensions/voice/release-controller.ts      Recording lifecycle, release handling

# speech-to-text
extensions/voice/deepgram.ts                Deepgram URL builder, API key resolver
extensions/voice/local.ts                   Model catalog (21 models), in-process transcription
extensions/voice/sherpa-engine.ts           sherpa-onnx bindings — recognizer lifecycle, inference
extensions/voice/sherpa-loader.ts           Lazy native module loading
extensions/voice/model-download.ts          Download manager — resume, progress, verification, Handy import
extensions/voice/device.ts                  Device profiling — RAM, GPU, CPU, container detection

# transcript post-processing
extensions/voice/post-process.ts            Polish pass — fail-open guardrails, model resolution, bounded call
extensions/voice/post-process-context.ts    Context assembly — recent turns and character caps
extensions/voice/post-process-prompt.ts     Fixed polish prompt and request shape

# text-to-speech
extensions/voice/speak.ts                   Speak entry point, auto-speak wiring
extensions/voice/tts-engine.ts              sherpa-onnx TTS synthesis
extensions/voice/tts-deepgram.ts            Deepgram Aura voices (cloud)
extensions/voice/tts-local-models.ts        Local TTS catalog — 20 voices (Kitten, Kokoro, Piper)
extensions/voice/tts-playback.ts            Playback, buffering, player detection
extensions/voice/tts-text-filter.ts         Code-block stripping, sentence prep
extensions/voice/tts-onboarding.ts          TTS onboarding flow
extensions/voice/tts-onboarding-overlay.ts  TTS onboarding overlay
extensions/voice/tts-install-progress.ts    Model install progress widget
extensions/voice/tts-playback-indicator.ts  Speaking indicator widget

# settings and UI
extensions/voice/settings-panel.ts          Settings panel — overlay, 6 tabs
extensions/voice/ui-picker.ts               Generic list picker
extensions/voice/ui-help-overlay.ts         Keyboard and command reference
extensions/voice/ui-aura.ts                 Visual primitives (Liquid Braille, Aurora)
extensions/voice/ui-widget-base.ts          Widget registry and base class
extensions/voice/ui-render-ticker.ts        Shared render ticker
extensions/voice/ui-icons.ts                Glyph and icon set
extensions/voice/ui-width.ts                CJK-aware visual width helpers
extensions/voice/ui-locale-labels.ts        Native language and voice labels

# types
extensions/voice/sherpa-onnx-node.d.ts      Type declarations for the optional native module
Settings stored in Pi's settings files under the voice key:
| Scope | Path |
|---|---|
| Global | ~/.pi/agent/settings.json |
| Project | <project>/.pi/settings.json |
{
	"voice": {
		"version": 3,
		"enabled": true,
		"language": "en",
		"backend": "local",
		"localModel": "parakeet-v3",
		"scope": "global",
		"onboarding": { "completed": true, "schemaVersion": 3 }
	}
}
DEEPGRAM_API_KEY from your shell is used at runtime and is not copied back
into ~/.pi/agent/settings.json. If you paste a key during onboarding, that is
an explicit save and it still goes to ~/.env.secrets or ~/.zshrc.
Hold-to-talk delay defaults to 700 ms (/voice-hold-delay accepts 200–3000 ms).
Transcript polish is on by default: every dictation runs an extra model pass. When the selected model is a cloud provider, the text that leaves your machine is:
- the transcript of the dictation;
- the last N conversation turns of user and assistant text, where N is
postProcessContextTurns(default2;0sends no conversation context); - nothing else. The compaction summary is deliberately not sent: it is a digest built from earlier messages, so it can carry residues of thinking and tool output, and it measured no gain over the turns alone.
One measured behaviour is worth knowing: a model that thinks before it answers may normalise a
spoken operator into its symbol — select star comes back as select *. The information is
unchanged, there is no setting for it, and /voice-polish off is the way to keep the words verbatim.
A reasoning model used to spend its whole token budget thinking about a long dictation, so the answer was truncated and the pass kept the raw transcript — which looked like polish quietly doing nothing past roughly half a minute of speech. Dictations longer than 200 characters now turn thinking off (the same 309-character input went from 10.2 s to 1.2 s with the same punctuation), while shorter ones keep it, because there it costs almost nothing and corrects terms and self-corrections better. The field only reaches OpenAI-compatible providers; one that ignores it behaves exactly as before.
On the local backend, polish no longer waits for the whole transcript: each recogniser segment — roughly 10 s of speech — is polished as it is decoded, with up to three segment calls in flight. A long dictation may come back partly polished, and that is deliberate: a segment that times out is retried once with thinking disabled for that retry, and if it still fails, that segment keeps its raw text while its neighbours keep their polished text — so one slow call no longer costs the rest of the dictation. The conversation context is attached to the first segment only; a later segment sees just the previous segment's raw text.
The gain is measurable: on 79.6 s of corpus audio (35 segments) against a degraded endpoint, the old single-call path fell back on 100% of the run, while the segmented path polished all 35 segments. Real dictations after the change: 4 of 4 applied, with polish taking 0.4–2.3 s for 8–28 s of audio — roughly 5–13% of the audio duration.
Assistant text can contain anything the conversation contained — file paths,
identifiers, values the agent echoed. The character limits bound how much is sent,
not how sensitive it is. With the local backend, nothing else leaves your machine,
and audio never does: recognition runs on this machine with no API key. Turn the
feature off with /voice-polish off or the Polish tab's Enabled row.
Every dictation also writes one voice-polish entry into the session file: the raw
transcript, what reached the editor and why the pass decided that. The model never sees
these entries — they are not part of the conversation context — so they are there for
analysis, and they do keep the raw text on disk for as long as the session file exists.
Each entry also records how the pass was configured: the transcript length on its own
(separate from any text already in the editor), whether thinking was turned off for it,
and the output-token cap it carried, plus the audio seconds it covered and which recogniser
produced it — which is what makes polish time readable as a speedup. A segmented pass adds a
segments summary to the entry: how many segments were polished, how many kept their raw
text, and how many were retried.
| Setting | Scope | Default | Notes |
|---|---|---|---|
postProcessEnabled |
global only | true |
Master switch. A project voice block cannot flip it. |
postProcessModel |
global only | "session" |
Reuses the session model, or provider/modelId. |
postProcessContextTurns |
global and project | 2 |
Conversation turns sent with the transcript, 0–10. |
postProcessTimeoutMs |
global and project | 12000 |
Per-pass timeout in milliseconds, 1000–30000. |
The global-only fields resolve from ~/.pi/agent/settings.json even when a
repository provides its own voice block, so a cloned repo can neither turn the
feature on nor redirect where dictated text goes. The model is chosen from a
picker (/voice-polish model), never typed: a hand-typed reference is refused,
and an unavailable or malformed model keeps the raw transcript instead of
switching provider. postProcessNoticeShown is machine-local bookkeeping for the
one-time notice, not a user setting.
Run /voice test inside Pi for full diagnostics.
| Problem | Solution |
|---|---|
| "DEEPGRAM_API_KEY not set" | Get a key → export DEEPGRAM_API_KEY="..." in ~/.zshrc |
| "No audio capture tool found" | brew install sox or brew install ffmpeg |
| Remote microphone records silence | Audio over PulseAudio/SSH — install ffmpeg on the Pi side (capture then prefers ffmpeg) |
| Space doesn't activate voice | Run /voice-settings — voice may be disabled |
| Local model not transcribing | Check /voice-settings → Device tab for sherpa-onnx status |
| Download failed | Partial downloads auto-resume on retry. Check disk space in Device tab. |
dyld: Library not loaded: libsimdjson on macOS |
Homebrew Node ABI mismatch — run brew reinstall node or switch to version-managed Node (mise, fnm, nvm) |
- Cloud STT — audio is sent to Deepgram for transcription (Deepgram backend only)
- Local STT — audio never leaves your machine (local backend)
- No telemetry — pi-voicekit does not collect or transmit usage data
- API key — stored in env var or Pi settings, never logged
See SECURITY.md for vulnerability reporting.
MIT — original by @baanditeagle, maintained by CyFeng16
Continuation of pi-listen by @baanditeagle, maintained by CyFeng16
Website · 𝕏 Twitter · GitHub · npm · Report a Bug · Pi CLI