
Does your LLM telemetry tell the truth? spantruth replays provider responses through LLM instrumentation libraries and checks the values they report against what the provider actually sent: tokens, cache tokens, models, finish reasons, errors, and whether the span ends at all.


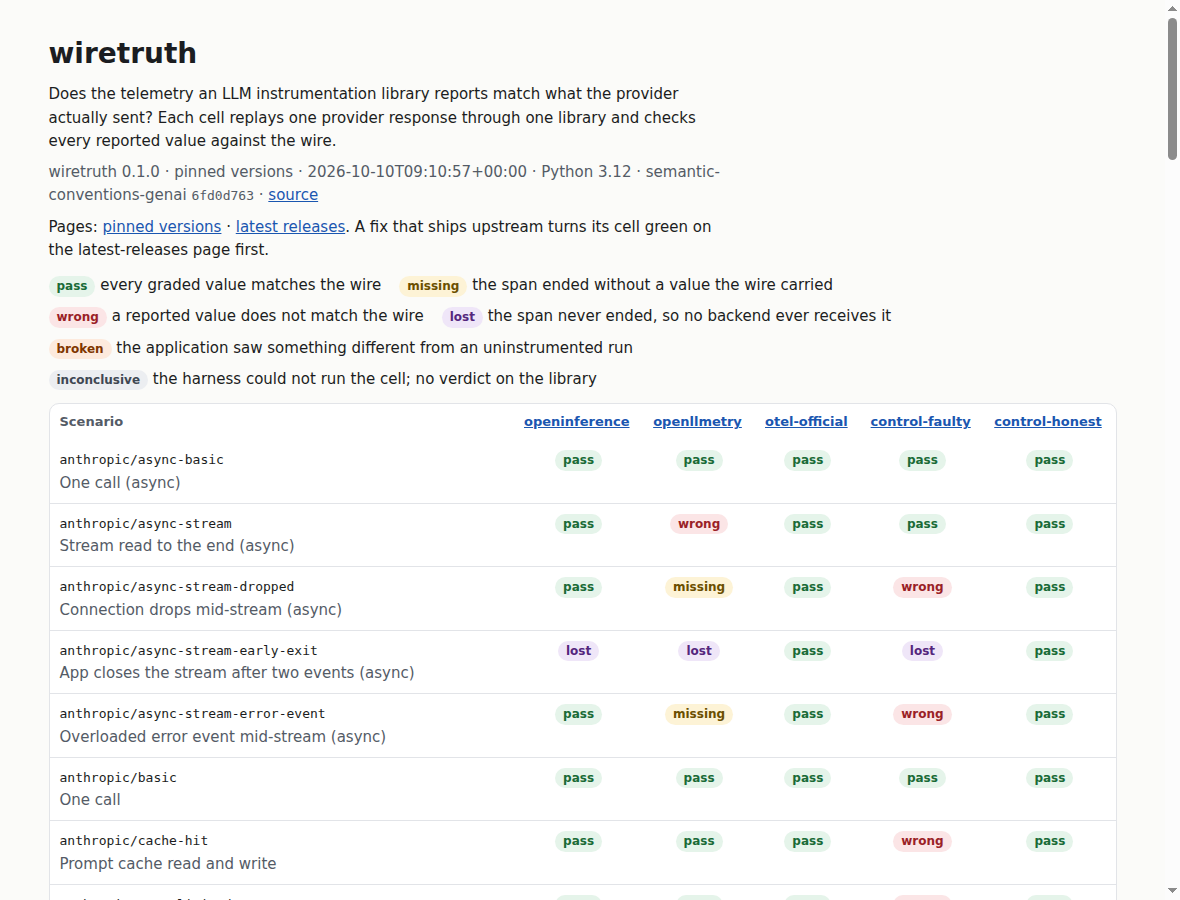
Read the report: every library, every scenario, every finding with the rule it applies. It is rebuilt every night, at pinned versions and at the latest releases.
Cost dashboards, token budgets, alerts and audits all read the numbers that instrumentation libraries put on spans. When a library adds a count twice or drops a cached token, nothing fails: the dashboard shows a wrong number with full confidence. When a span never ends, the call is missing from the trace altogether.
These bugs live on the paths that normal tests skip: a stream the app leaves early, a connection that drops, a 429, a prompt-cache hit. spantruth tests exactly those paths, for every library, in the same way.
Pinned versions, 2026-11-03: openai 3.42.1 and anthropic 2.4.0 under every library. Each finding is reported upstream, by the people credited below, and the nightly run against the latest releases shows when a fix lands.
| Library | Finding | Upstream |
|---|---|---|
| OpenLLMetry | Anthropic streams overcount output tokens. message_delta carries the cumulative count, and the wrapper adds it to the count in message_start (1 in the scenarios). |
#4377, by @arthi-arumugam-git |
| OpenLLMetry | A sync Anthropic stream that fails mid-way (a dropped connection, an overloaded_error event) never ends its span. The async stream ends it with status ERROR, but without error.type. |
#4643, by @chrikrah |
| OpenLLMetry | An OpenAI stream that fails mid-way ends its span with status OK, sync and async. |
#4535, by @feiiiiii5 |
| OpenLLMetry | An Anthropic stream the app closes early never ends its span. | #4536, by @armanunix |
| OpenInference | Every scenario passes. The early-exit spans that never ended are fixed in openinference-instrumentation-openai 0.1.66 and openinference-instrumentation-anthropic 3.1.0. |
#3790, by @feiiiiii5; #3930, by @armanunix |
| OpenTelemetry GenAI instrumentation | Every scenario passes. | |
| Anthropic SDK, built-in tracing | The SDK's own spans get the tokens, the cache counts and the errors right, but record the stop reason as anthropic.message.stop_reason, so gen_ai.response.finish_reasons is missing. |
not reported yet |
| Any library with anthropic 1.14.0 or later | The SDK creates its own span for every call when a tracer provider is registered, so a library on top reports each call on two spans, and a backend that sums token counts counts them twice. spantruth turns the SDK's spans off for the library subjects (ANTHROPIC_OPEN_TELEMETRY=false), and grades them as their own subject. |
not reported yet |
Each finding on the report shows the expected value, the reported value, the attribute it was read from, and the rule it applies, with a link wherever a spec states it. It also shows the spans the library exported and the command that reproduces it, and it has its own link, so an upstream issue can point at it.
spantruth run
  ├─ fake provider endpoint     serves the scenario: JSON, SSE stream, 429, dropped connection
  ├─ OTLP/HTTP receiver         collects every span the library exports
  └─ per library: own venv  →  the app calls the real OpenAI / Anthropic SDK
                                    └─ the library under test exports OTLP to the receiver
  checks: wire truth  ×  what the app saw  ×  what the telemetry says  →  verdict per cell
- Values, not presence. No two token counts in a fixture are equal. A swapped field, a dropped cache count, or a sum done twice shows up as a wrong number. For a wrong token count, the report names the arithmetic that most likely produced it, such as "cache reads and writes left out".
- Fixtures follow the wire. The test suite parses every response and every stream event with the provider SDK's own types.
- Convention-neutral. A value is read under the current OpenTelemetry GenAI names, older names, or OpenInference names. A library is never marked wrong for its choice of names.
- The app is checked too. Each scenario also runs without instrumentation. If the library
changes what the app receives (an exception, a chunk, a return value, a hang), the cell is
broken. - Spans that never end are found. An in-process probe records every span start and end. A span that never ends is never exported, so the receiver alone could not tell.
- Offline and deterministic. No API keys, and no network after install.
Two subjects run the suite's own small reference instrumentation. control-honest has to pass
every check. control-faulty carries four planted faults and has to fail exactly the checks
they target. CI runs both end to end on every change. If either moves, the suite is wrong, not a
library.
| Verdict | Meaning |
|---|---|
| pass | Every graded value matches the wire. |
| missing | The span ended without a value that the wire carried. |
| wrong | A reported value does not match the wire. |
| lost | The span never ended, so no backend ever receives it. |
| broken | The app saw something different from an uninstrumented run. |
| inconclusive | The cell could not be graded: the harness could not run it, or the library's setup raised (subject.instrument). |
You need uv. No clone, no API keys:
uvx spantruth list                                      # scenarios and subjects
uvx spantruth run --subject openllmetry                 # one library, every scenario
uvx spantruth run --out results.json                    # everything, about 3 minutes
uvx spantruth report results.json --html report.html
Each subject gets its own virtual environment under ~/.cache/spantruth/venvs
($XDG_CACHE_HOME/spantruth when that is set). A run writes nothing into the directory you run it
in: without --out, the results go to ~/.cache/spantruth/results/latest.json. --latest unpins
the library's own packages. The run behind the table above is committed as
results/2026-11-03-pinned.json.
To work on spantruth itself, use a clone: git clone https://github.com/Plexito-de/spantruth.git,
then uv sync and uv run spantruth list in it.
--with replaces one package of a subject with a local checkout, a pull request's head, a
branch, or a version. A checkout is named by its pyproject.toml, and the results record what
each value resolved to.
uvx spantruth run --subject openllmetry --with ./packages/opentelemetry-instrumentation-anthropic
uvx spantruth run --subject openllmetry --with \
  "opentelemetry-instrumentation-anthropic @ git+https://github.com/traceloop/openllmetry@refs/pull/4377/head#subdirectory=packages/opentelemetry-instrumentation-anthropic"
A subject can live in your own repository. Copy the two files of a subject in
subjects/, subject.toml and instrument.py, into a directory and run it by its
path. A value with a slash is a path, and a value without one is a built-in subject:
uvx spantruth run --subject ./spantruthRecord the checks that your library fails today, commit the file, and compare every later run with it:
uvx spantruth run --subject ./spantruth --write-expect spantruth-expected.toml
uvx spantruth run --subject ./spantruth --expect spantruth-expected.toml| Exit code | Meaning |
|---|---|
| 0 | Every cell ran, and the failing checks equal the expectation file. |
| 1 | The failing checks differ from the file: a new failure, a fix, or a changed verdict. The output names each one. |
| 2 | Usage error, for example an unknown scenario in the expectation file. |
| 3 | spantruth could not build an environment or run a cell. This is not a verdict on the library. |
A fix fails the comparison too, so the file always says what the library fails today: record the
fix with --write-expect. --summary "$GITHUB_STEP_SUMMARY" adds the report to a GitHub Actions
job summary.
jobs:
  spantruth:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v5
      - uses: Plexito-de/spantruth@v0.3.0
        with:
          subject: ./spantruth                       # or a built-in subject, such as openllmetry
          with: ./packages/my-instrumentation        # your checkout, one per line
          expect: spantruth-expected.toml            # optional: fail only on a change
The step installs spantruth from its own ref, so a new release cannot change your results until
you move the tag. It writes the matrix, the findings and the differences to the job summary,
uploads the results and the HTML report as an artifact, and fails with the exit code of the run.
The exit-code output tells a difference (1) from an incomplete run (3). It runs on Linux and
macOS runners.
The nightly run against the latest releases publishes a shields.io
endpoint per library, at https://plexito-de.github.io/spantruth/badges/<subject>.json:
[](https://plexito-de.github.io/spantruth/latest.html)- Providers: OpenAI Chat Completions and Anthropic Messages, sync and async. The OpenAI Responses API has its first scenario, a stream replayed from a recording.
- Scenarios (32): plain call, stream, stream without usage, prompt-cache hit (plain, streamed,
and with cumulative counts in
message_delta), parallel tool calls, reasoning tokens, HTTP 429, a stream the app leaves early (byclose()and by awithblock), a dropped connection, and Anthropic's mid-streamerrorevent. Streams and failures run sync and async. A Responses API stream cut after eight recorded events replays kartsan03/wiretruth'sstream.missing-finish-abortfixture, vendored unchanged with its provenance. - Subjects: the OpenTelemetry GenAI instrumentation, OpenLLMetry, OpenInference, OpenLIT, and the built-in tracing of the Anthropic SDK, plus the two controls.
Next, from the plan: Logfire, the bug classes that repeat (tool calls and
reasoning tokens in a stream, the SDK helpers such as messages.stream(), the rest of the OpenAI
Responses API), Google Gemini, frameworks such as LiteLLM and Pydantic AI, and the JavaScript
libraries. Help is welcome.
- open-telemetry/semantic-conventions-conformance is the official project. It checks which attributes each instrumentation emits, against the semantic conventions, with Weaver. spantruth is complementary: it checks the values, and the failure paths. A finding that belongs upstream goes upstream.
- spanproof, by 4ktLuffy, applies the same method to Sentry's SDK integrations. spantruth takes its idea of validating every fixture with the provider SDK's own types from it.
- wrong-numbers, by arthi-arumugam-git, is a field guide to the same defect class across LLM eval, tracing and cost libraries: a number comes out wrong and nothing raises.
- wiretruth, by kartsan03, checks what the provider SDK returns to the caller, from verbatim recorded responses. spantruth checks what the instrumentation writes on the span. This project was called wiretruth until 2026-10-12 and took its current name so the two stay easy to tell apart.
Contributions are welcome, and so are disputes. If you maintain one of these libraries and a cell is unfair, tell us: we decide every dispute on whether the cited rule says what the check claims. To add a library, a provider or a scenario, read CONTRIBUTING.md. First-time contributors sign the Plexito CLA with one comment on their pull request.
Apache-2.0. Maintained by Plexito.