
Volume Transformer: Revisiting Vanilla Transformers for 3D Scene Understanding
(ECCV 2026 Long Oral)
Paper · Project Page · BibTeX
This repository contains the official implementation of Volume Transformer (Volt).
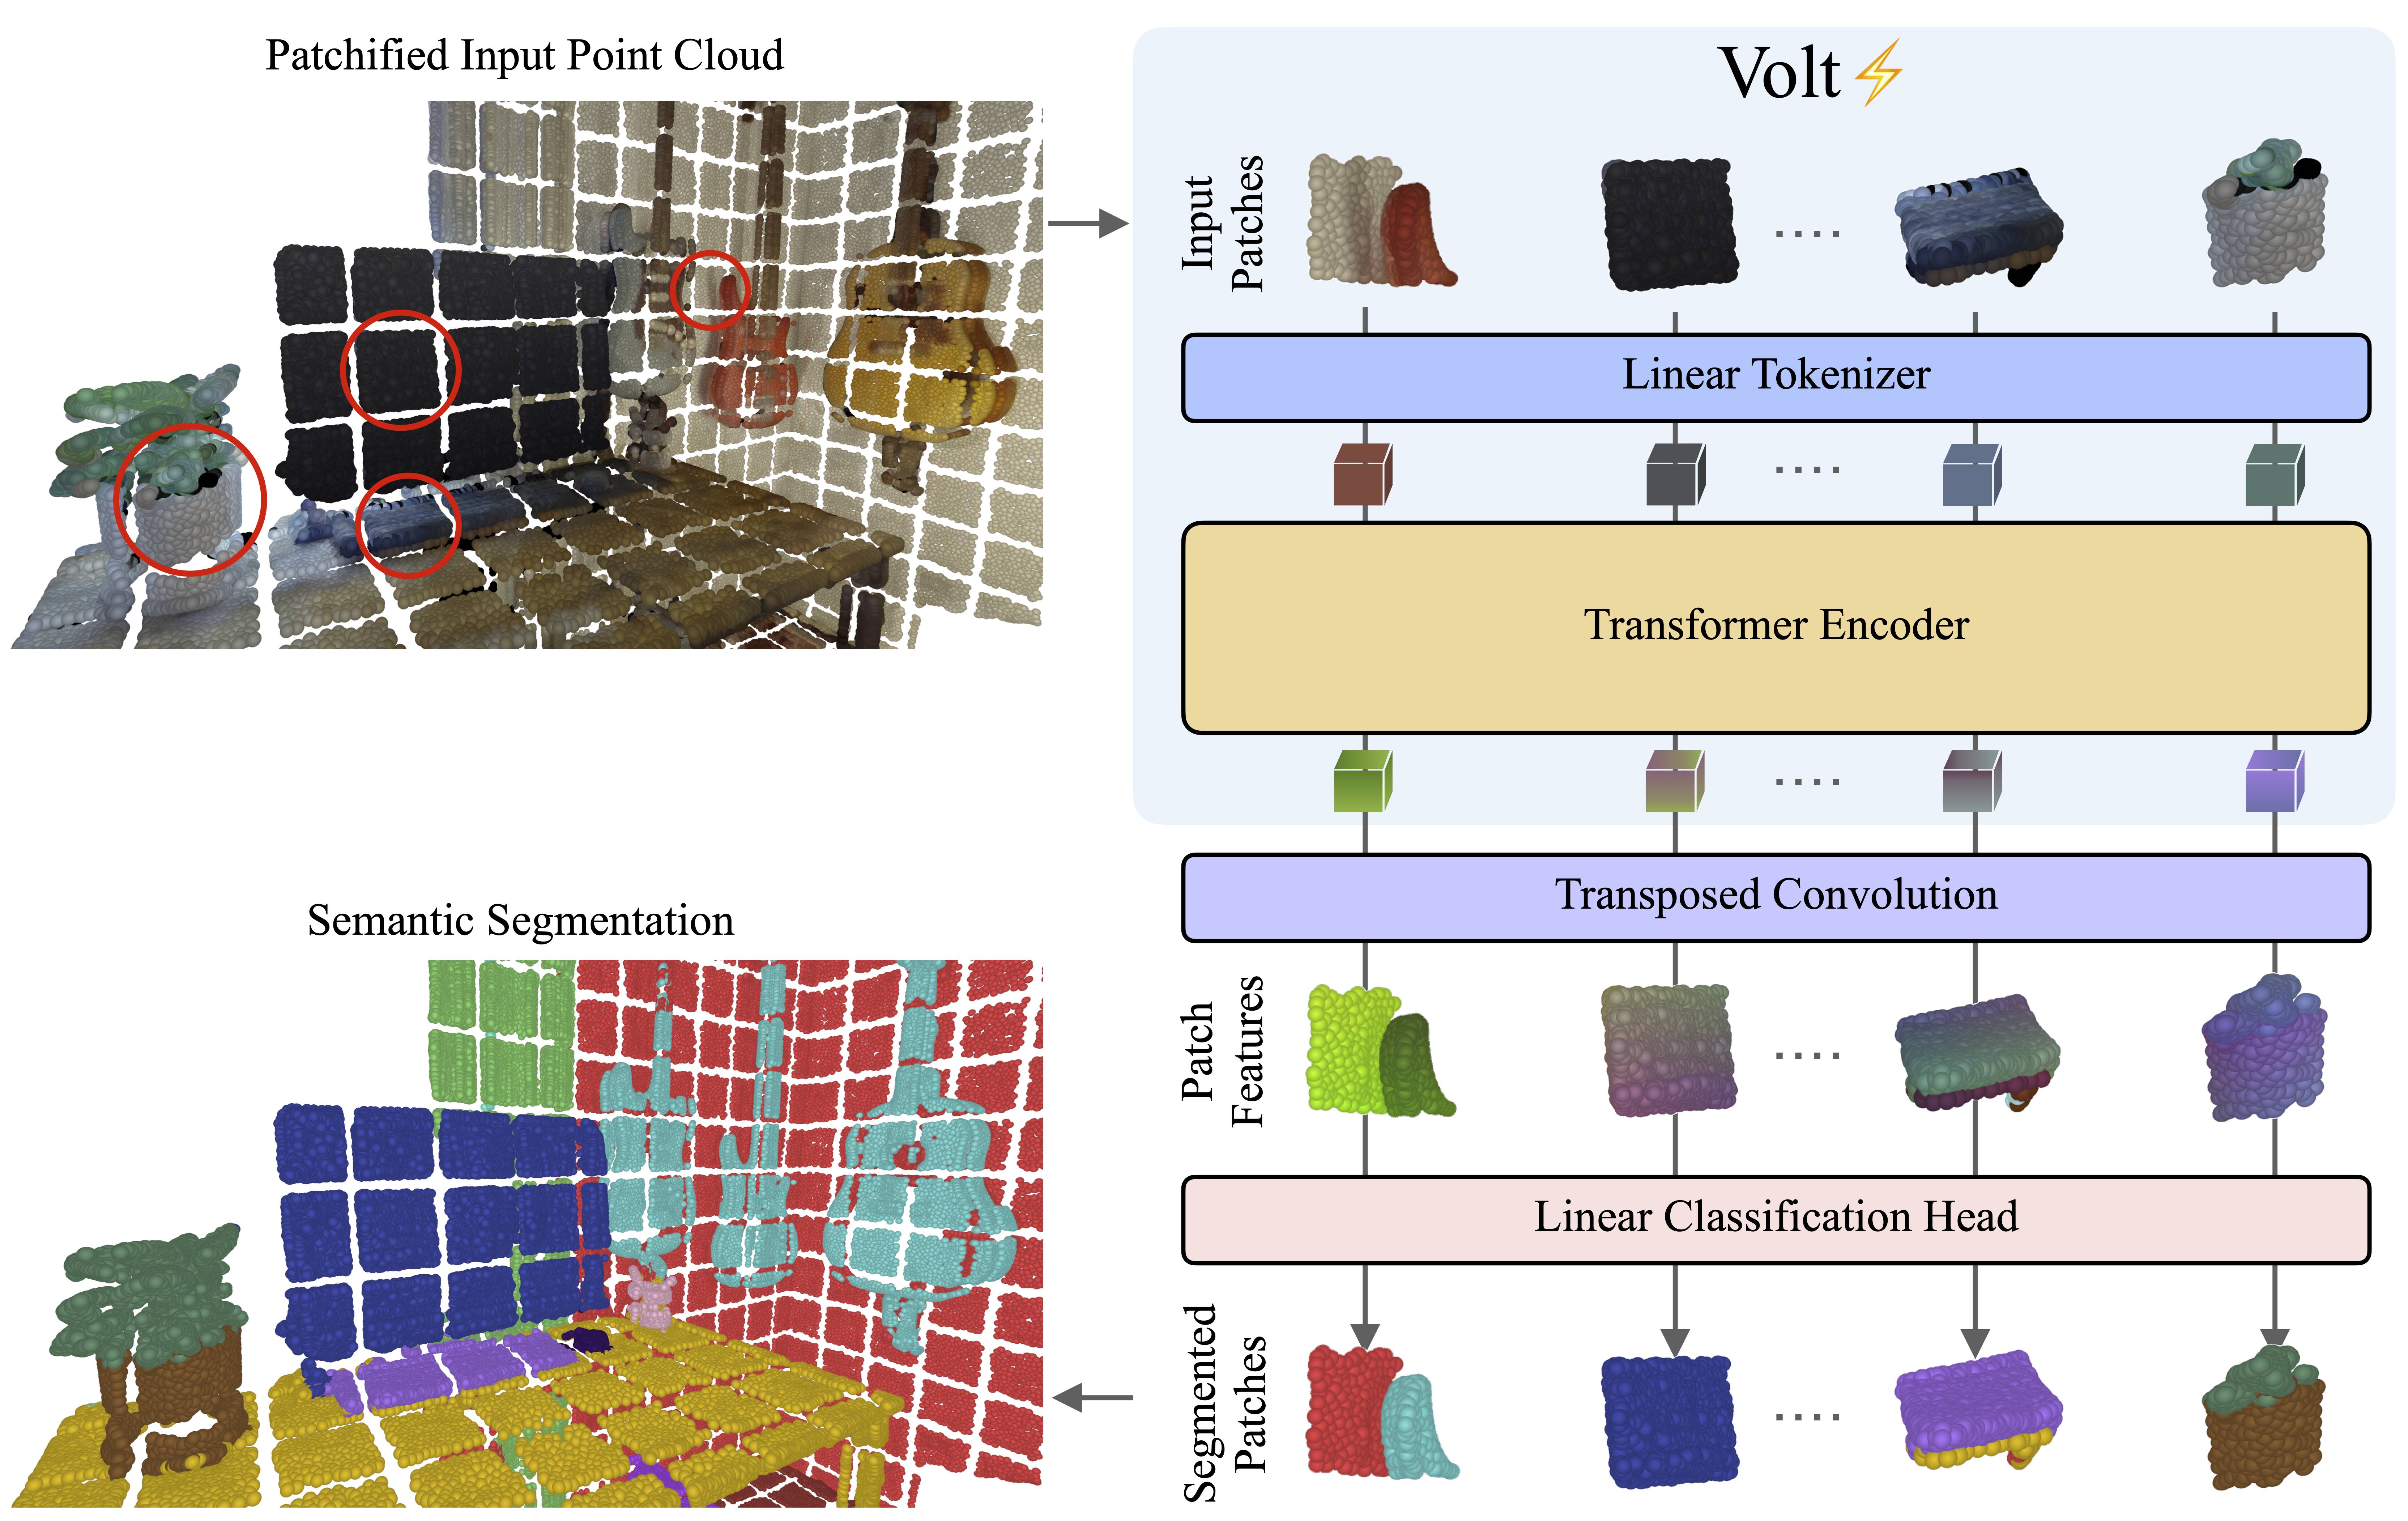
Volt partitions the input 3D scene into non-overlapping volumetric patches and embeds each patch into a token with a linear tokenizer. The resulting token sequence is processed by a Transformer encoder with global attention. The latent tokens are then upsampled back to the voxel resolution with a single transposed convolution and mapped to semantic predictions by a linear classification head.
The core Volt model implementation can be found in
pointcept/models/volt/volt_base.py.
- 2026-08-05: 🎉🎉 Volt is selected as one of the 28 Long Oral presentations at ECCV 2026!
- 2026-06-18: 🎉 Volt is accepted to ECCV 2026!
- 2026-06-13: Volt is now implemented in pure PyTorch and no longer depends on spconv.
- 2026-06-03: Volt won 3 challenges at CVPR 2026.
- 2026-04-22: Code release.
This repository is built on top of Pointcept and incorporates components from SGIFormer for instance segmentation. For integrating image features with 3D backbones, please refer to our DITR codebase.
We recommend using uv, a fast Python package and environment manager, to install the environment.
To install uv on macOS and Linux, run:
curl -LsSf https://astral.sh/uv/install.sh | shThen set up the environment with:
# Make sure to load CUDA 12.6 beforehand
# This will automatically create a virtual environment (.venv) and install dependencies from pyproject.toml
uv sync
source .venv/bin/activateFollow the dataset setup instructions in the Pointcept README.
Preprocessing for ScanNet and ScanNet200 is identical to Pointcept.
After the ECCV submission, we found that the original map_benchmark.csv is not exhaustive, as discussed here. As a result, some labels were mapped to ignore. We therefore regenerate map_benchmark.csv and provide the updated version at pointcept/datasets/preprocessing/scannetpp/new_map_benchmark.csv. Run the preprocessing script below which uses this new mapping.
python pointcept/datasets/preprocessing/scannetpp/preprocess_scannetpp.py --dataset_root ${SCANNETPP_DIR} --output_root ${PROCESSED_SCANNETPP_DIR}Run the preprocessing script below.
python pointcept/datasets/preprocessing/scenefun3d/preprocess_scenefun3d.py --dataset_root ${SCENEFUN3D_DIR} --output_root ${PROCESSED_SCENEFUN3D_DIR}For nuScenes, run the preprocessing script below. Unlike Pointcept preprocessing, we additionally write panoptic labels to the .pkl files.
uv run --no-project --python 3.12 --with nuscenes-devkit python pointcept/datasets/preprocessing/nuscenes/preprocess_nuscenes_info.py --dataset_root ${NUSCENES_DIR} --output_root ${PROCESSED_NUSCENES_DIR}For SemanticKITTI, run the following script to generate the instance database used for instance CutMix.
python pointcept/datasets/preprocessing/semantic_kitti/build_instance_db_h5.py --dataset_root ${KITTI_DIR} --output_root "data/semantic_kitti_instances"For Waymo, run the preprocessing script below. Waymo provides multiple LiDAR sensors. Unlike Pointcept preprocessing, we use only the points from the TOP LiDAR sensor, since only those points have semantic labels.
uv run --no-project --python 3.10 --with waymo-open-dataset-tf-2-11-0 python pointcept/datasets/preprocessing/waymo/preprocess_waymo.py --dataset_root ${WAYMO_DIR} --output_root ${PROCESSED_WAYMO_DIR} --splits training validation --num_workers ${NUM_WORKERS}Download UNet teacher weights from HuggingFace
hf download KadirYilmaz/Volt --include "teacher_weights/*.pth" --local-dir weights/Then, run the training script with the semseg-volt-distill config for each dataset.
### ScanNet
sh scripts/train.sh -g 4 -d scannet -c semseg-volt-distill -n semseg-volt-distill
### ScanNet200
sh scripts/train.sh -g 4 -d scannet200 -c semseg-volt-distill -n semseg-volt-distill
### ScanNet++
sh scripts/train.sh -g 4 -d scannetpp -c semseg-volt-distill -n semseg-volt-distill
### NuScenes
sh scripts/train.sh -g 4 -d nuscenes -c semseg-volt-distill -n semseg-volt-distill
### SemanticKITTI
sh scripts/train.sh -g 4 -d semantic_kitti -c semseg-volt-distill -n semseg-volt-distill
### Waymo
sh scripts/train.sh -g 4 -d waymo -c semseg-volt-distill -n semseg-volt-distill
For joint training, use the semseg-volt-joint-small config instead.
### ScanNet
sh scripts/train.sh -g 4 -d scannet -c semseg-volt-joint-small -n semseg-volt-joint-small
### ScanNet200
sh scripts/train.sh -g 4 -d scannet200 -c semseg-volt-joint-small -n semseg-volt-joint-small
### NuScenes
sh scripts/train.sh -g 4 -d nuscenes -c semseg-volt-joint-small -n semseg-volt-joint-small
### SemanticKITTI
sh scripts/train.sh -g 4 -d semantic_kitti -c semseg-volt-joint-small -n semseg-volt-joint-small
### Waymo
sh scripts/train.sh -g 4 -d waymo -c semseg-volt-joint-small -n semseg-volt-joint-smallFirst, run the preprocessing script to generate superpoints for ScanNet and ScanNet200.
python pointcept/datasets/preprocessing/scannet/preprocess_superpoints.py --dataset_root ${RAW_SCANNET_DIR} --output_root ${PROCESSED_SCANNET_DIR}Download the pretrained Volt backbone weights from HuggingFace
mkdir -p weights
curl -L -o weights/volt-small-scannet.pth https://huggingface.co/KadirYilmaz/Volt/resolve/main/Volt_experiments/joint_training_small/scannet/model/model_last.pth
curl -L -o weights/volt-base-scannet.pth https://huggingface.co/KadirYilmaz/Volt/resolve/main/Volt_experiments/joint_training_base/scannet/model/model_last.pth
curl -L -o weights/volt-small-scannet200.pth https://huggingface.co/KadirYilmaz/Volt/resolve/main/Volt_experiments/joint_training_small/scannet200/model/model_last.pth
curl -L -o weights/volt-base-scannet200.pth https://huggingface.co/KadirYilmaz/Volt/resolve/main/Volt_experiments/joint_training_base/scannet200/model/model_last.pth
curl -L -o weights/volt-base-scannetpp.pth https://huggingface.co/KadirYilmaz/Volt/resolve/main/Volt_experiments/joint_training_base/scannetpp/model/model_last.pth
Alternatively you can train them yourself using the corresponding configs above.
Then, run the training script with the insseg-spformer-volt-S-0-base config for scannet/scannet200
### ScanNet
sh scripts/train.sh -g 4 -d scannet -c insseg-spformer-volt-S-0-base -n insseg-volt
### ScanNet200
sh scripts/train.sh -g 4 -d scannet200 -c insseg-spformer-volt-S-0-base -n insseg-volt
### ScanNet++
sh scripts/train.sh -g 4 -d scannetpp -c insseg-spformer-volt-B-0-base -n insseg-volt
For SceneFun3D, we train the model for semantic segmentation only, and use a simple clustering-based post-processing algorithm for instance segmentation. This is done automatically in the SceneFun3DTester and the results are saved in the correct format. We note that we achieve much higher scores on the validation set compared to the test set but we don't have a reason why and we don't know if it is specific to our approach. It could be due to the fact that the test set containing more challenging scenes.
### SceneFun3D
sh scripts/train.sh -g 4 -d scenefun3d -c semseg-volt-base -n insseg-voltWe provide the experiment directories, including configs, logs, and checkpoints. The experiments can also be seen from Hugging Face.
| Model | Dataset | Val mIoU | Exp. Dir |
|---|---|---|---|
| Volt-S | ScanNet | 77.3 | link |
| Volt-S | ScanNet200 | 36.1 | link |
| Volt-S | ScanNet++ | 51.1 | link |
| Volt-S | nuScenes | 81.1 | link |
| Volt-S | SemanticKITTI | 70.3 | link |
| Volt-S | Waymo | 71.2 | link |
| Model | Dataset | Val mIoU | Exp. Dir |
|---|---|---|---|
| Volt-S | ScanNet | 80.2 | link |
| Volt-B | ScanNet | 80.5 | link |
| Volt-S | ScanNet200 | 38.5 | link |
| Volt-B | ScanNet200 | 40.0 | link |
| Volt-B | ScanNet++ | 51.7 | link |
| Volt-S | nuScenes | 81.8 | link |
| Volt-B | nuScenes | 82.2 | link |
| Volt-S | SemanticKITTI | 72.8 | link |
| Volt-S | Waymo | 72.5 | link |
| Volt-B | Waymo | 73.7 | link |
| Model | Dataset | Val mAP50 | Exp. Dir |
|---|---|---|---|
| Volt-S | ScanNet | 78.5 | link |
| Volt-S | ScanNet200 | 49.0 | link |
| Volt-B | ScanNet++ | 53.1 | link |
| Volt-B | SceneFun3D | 53.7 | link |
If you use our work in your research, please use the following BibTeX entry.
@inproceedings{yilmaz2026volt,
  title     = {{Volume Transformer: Revisiting Vanilla Transformers for 3D Scene Understanding}},
  author    = {Yilmaz, Kadir and Kruse, Adrian and H{\"o}fer, Tristan and de Geus, Daan and Leibe, Bastian},
  booktitle = {European Conference on Computer Vision (ECCV)},
  year      = {2026},
}