The repository for some of my reinforcement learning codes
Extract q*(a) for each 10 actions from a normal distribution, then each time select each action greedily and do it 1000 times.
Do experiment of Problem1 2000 times and select action in three manners: greedy, epsilon-greedy (epsilon=0.01), and epsilon-greedy (epsilon=0.1)
Use Upper-Confidence-Bound Action Selection method with c=2, number of steps: 1000, and number of itteration: 2000
Considering uniform action selection probability for all actions, evaluate the policy with the policy evaluation algorithm:

Implement policy itteration algorithm:

Using the optimal policy obtained in problem2, evaluate that with Monte-Carlo method
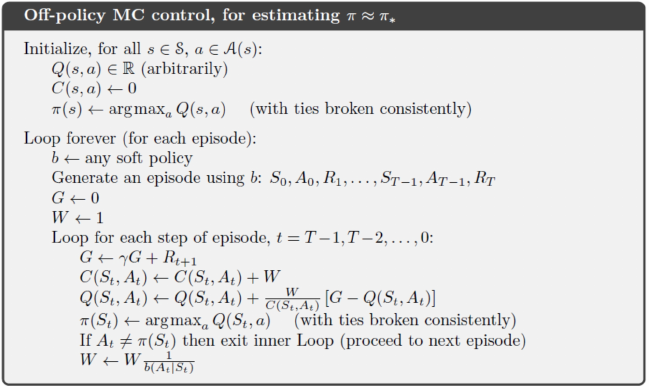
Determine the optimal action value using off-policy Monte-Carlo with importance sampling:
mountain car of openai gym using semi-gradient Sarsa with tiling