






Voice AI agents · RAG and LLM evaluation · multi-tenant SaaS · agentic coding · open-source developer tools
I build AI systems that have to work in production: voice agents that answer real phone calls, RAG and LLM agents judged by cost per correct answer, and multi-tenant SaaS platforms with row-level security and field-level encryption. I also publish the research behind them, including the numbers that went against me, and open-source tools that catch problems before they ship: Microsoft gov-cloud gaps, broken Make.com scenarios, Postgres images that crash on older CPUs and packages an AI coding agent made up. Based in Pakistan, working with US teams, open to contract work. Website: intikhab49.github.io.


- AI voice agents: Vapi and Twilio receptionists and outbound callers, wired into CRMs, payments and SMS
- RAG and LLM agents: knowledge-base chatbots with tool calling and memory, evaluated by cost per correct answer
- LLM evals and research: calibration, benchmarks and backtests that report the losing numbers too
- Multi-tenant SaaS architecture: Postgres row-level security, BFF auth, field-level encryption, event-driven jobs
- Agentic coding: Claude Code, Codex and DeepSeek working in parallel behind spec files, a claims board and test gates
- Automation and data pipelines: n8n, Cloudflare Workers, lead generation, scraping and enrichment
- Developer tools and CI checks: CLIs, GitHub Actions and MCP servers on PyPI and npm, for Microsoft gov clouds (GCC High, Azure Government), Make.com, Postgres images and AI-written code
| Tool | What it does | Get it |
|---|---|---|
| fairfax | Is it available in GCC High? Checks a Microsoft 365 GCC, GCC High or DoD and Azure Government plan against Microsoft's own feature availability tables (633 features, every row cited), and finds commercial endpoints in your code | pip install fairfax · website · GitHub Action |
| blueprint-runtime | Test Make.com scenarios offline. Runs exported Make (Integromat) blueprints locally and replays real Make runs, so a broken mapping fails in CI instead of in production. 71 of 79 real runs reproduced exactly | npm install -g blueprint-runtime · website |
| lifeboat | A Bitnami PostgreSQL alternative. Bitnami's PostgreSQL and PostgreSQL HA (repmgr) images rebuilt from upstream source: same paths, scripts and env vars, drop-in for the Bitnami Helm charts | ghcr.io/intikhab49/lifeboat |
| pgvector-cpu-check | Which CPU crashes your Postgres image? Runs it on 7 CPUs, from a 2008 Intel to Raspberry Pi and Graviton2, and names the faulting instruction (SIGILL) | GitHub Action · website |
| pdf-cpu-bench | Best PDF parser for RAG without a GPU. 9 PDF-to-Markdown parsers on a plain 4-core CPU: olmocr-bench accuracy, seconds per page, peak RAM, install size | Benchmark and results |
| whofetched | Which AI actually read your page? Secret canary links plus a Cloudflare Worker log, tested on ChatGPT, Claude, Gemini, Grok, Perplexity and Copilot | Cloudflare Worker |


All current repositories, with details
| Repository | What it is | Stack |
|---|---|---|
| fairfax | Is it available in GCC High? Checks a Microsoft 365 GCC / GCC High / DoD and Azure Government plan against Microsoft's own availability tables, scans code for wrong-cloud endpoints | Python · PyPI · GitHub Action · MCP |
| blueprint-runtime | Offline test runner for Make.com (Integromat) scenario blueprints: replays real Make runs and catches broken mappings in CI | TypeScript · npm · CLI |
| lifeboat | Drop-in Bitnami PostgreSQL and PostgreSQL HA (repmgr) images rebuilt from upstream source, amd64 + arm64 | Docker · Helm · GHCR |
| pgvector-cpu-check | Runs a Postgres image on 7 CPUs and names the instruction that crashes it (SIGILL) | Python · QEMU · GitHub Action |
| pdf-cpu-bench | 9 PDF-to-Markdown parsers for RAG on a 4-core CPU: accuracy, seconds per page, RAM, install size | Python · Docling · MinerU · Marker |
| whofetched | Proves which AI fetched your page with secret canary links and a Cloudflare Worker log | JavaScript · Cloudflare Workers |
| open-jev-typed-decision-engine | Open reproduction of TypeSafe Jev: a 150M typed decision engine (noul / choice / score) with calibrated confidence | Python · PyTorch · ModernBERT |
| pushback | Measures how often you correct your Claude Code agent, drafts CLAUDE.md rules, exports DPO pairs | Python · CLI · PyPI |
| minio-from-source | MinIO server + mc built from source at pinned releases, multi-arch images on GHCR | Docker · GitHub Actions |
| diff-gate | Fails on imports an AI coding agent invented, before attackers can register them | JavaScript · GitHub Action |
| rag-cost-curve | Cost per correct answer for agentic, iterative, reranked and naive RAG on MuSiQue | Python · Claude |
| edgeproof-crypto-trading-backtest | Backtesting and ML validation: triple-barrier labels, purged CV, deflated Sharpe, a planted-edge control | Python · LightGBM · PyTorch |
| local-business-lead-finder | Lead generation past the Google Places cap, OpenStreetMap fallback, e-mail enrichment | Python · FastAPI · Streamlit |
| vapi-voice-agent-crm | CRM and call-ops backend for Vapi voice agents: webhooks, predictive dialer, Stripe-verified conversions | Node.js · Express · Twilio · Stripe |
| secureface-liveness-detection | Face recognition access control with head-pose liveness, rPPG pulse detection and ChromaDB matching | InsightFace · OpenCV · Streamlit |
| ai-wealth-advisor | RAG + tool-calling financial assistant: VaR, Sharpe, drawdown, diversification scoring | LangChain · Gemini · Flask |
| cryptoaion-price-prediction | BiLSTM + attention crypto price prediction API with WebSocket streaming and JWT auth | PyTorch · FastAPI |
| npi-healthcare-lead-pipeline | NPI Registry to practice websites to e-mails, resumable and scheduled on GitHub Actions | Python · GitHub Actions |
| libncurses5-libaio1-ubuntu-deb | Legacy libaio1 / libncurses5 / libtinfo5 .deb packages for newer Ubuntu |
Ubuntu · dpkg |
| git-notes | Working notes on git internals and GitHub Actions | Markdown |
Early projects (2023-2025, archived)
Learning projects from before the work above. Kept public, read-only.
| Repository | What it is | Stack |
|---|---|---|
| crypto-price-prediction-api | v1 of CryptoAion with BiLSTM and XGBoost research notebooks | FastAPI · PyTorch |
| kubernetes-flask-microservices | Flask microservices on Kubernetes with NGINX, PostgreSQL, a logging service and Prometheus | Flask · Kubernetes · Docker |
| kubernetes-flask-crud | Flask + PostgreSQL behind NGINX on Minikube with NetworkPolicies | Flask · Kubernetes · NGINX |
| flask-postgres-crud-dashboard | User management CRUD app with a Chart.js analytics dashboard | Flask · PostgreSQL · Docker |
| react-express-drizzle-crud | Full-stack TypeScript CRUD with Passport session auth | React · Express · Drizzle · Neon |
| devops-agency-website | DevOps agency site with a pricing calculator and contact API | React · TypeScript · Tailwind |
| ubuntu-dev-tools-installer | Interactive Bash installer for Python, VS Code, Docker, Jenkins, kubectl | Bash |
| cpp-queue-data-structure | Array-based FIFO queue in C++ | C++ |

I design systems end to end, from the data model to the deploy pipeline. Patterns I use in production:
- Multi-tenant SaaS: shared schema with tenant keys, Postgres row-level security and cross-tenant tests in CI
- BFF authentication: httpOnly cookie sessions with token refresh owned in one place
- Field-level encryption for sensitive personal data, with key rotation and idempotent backfills
- Event-driven pipelines: webhooks, job queues, retries and idempotency keys
- Edge compute: Cloudflare Workers for payment links, SMS and API glue between voice agents and Stripe
- LLM routing: small models first, frontier models only when needed, prompt caching to cut token spend
- Delivery: Docker, Kubernetes + NGINX, Prometheus, and end-to-end tests that run against real data, not just mocks

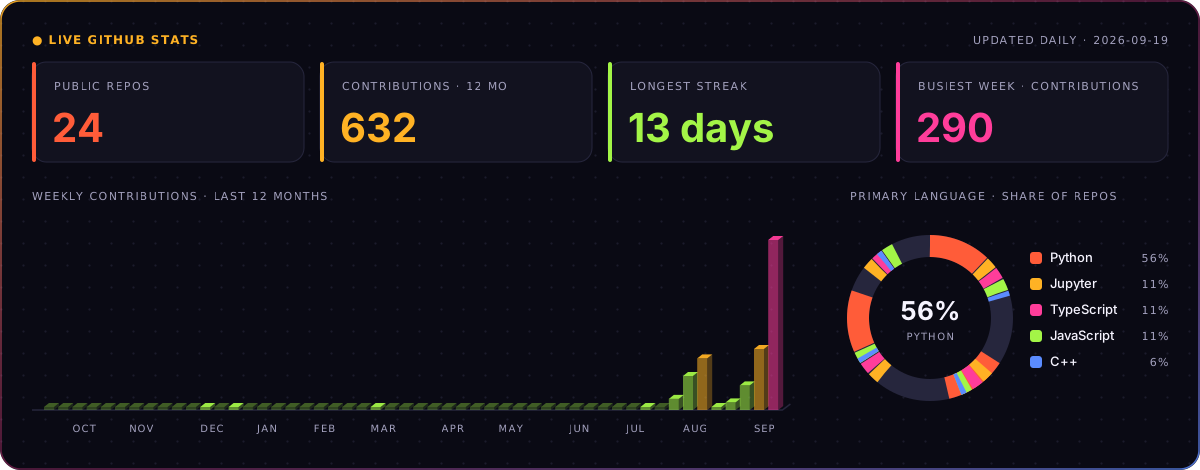
Redrawn every day by this repo's own GitHub Action. No third-party stats service.
I take on contract and freelance work:
- AI voice agents: receptionists, outbound callers, call-to-CRM and payment flows on Vapi and Twilio
- RAG chatbots and LLM agents: knowledge bases, tool calling, memory and evaluation
- LLM cost and quality: benchmarks, calibration, prompt caching and model routing
- System architecture: multi-tenant SaaS design, auth and data security, scaling and cost reviews
- Agentic coding setups: Claude Code skills, MCP servers and CI gates for AI-written code
- Automation: n8n workflows, lead generation, scraping, CRM and payment integrations
- Microsoft gov cloud: GCC, GCC High and Azure Government feature, endpoint and sign-in checks before you build
- Make.com and no-code QA: regression tests for Make scenarios that run offline and in CI

AI engineer · machine learning engineer · LLM engineer · AI researcher · systems architect · voice AI agent developer · Vapi · Twilio · RAG · agentic RAG · LLM evaluation · calibration · Claude Code · MCP · multi-tenant SaaS · Python · PyTorch · FastAPI · NestJS · open-source developer tools · GCC High · Azure Government · Microsoft 365 GCC · Make.com · Integromat · PostgreSQL · pgvector · Bitnami alternative · Docker · GitHub Actions · MCP server · PDF parsing for RAG · remote AI engineer in Pakistan