
Tokenfold Select brings query-aware relevance ranking to your LLM context. Fit complete context groups to a token budget, backed by Core's structural compression and inspectable receipts.
Python-first SDK. TypeScript alongside it. Rust at the core.
One fit() workflow for text, JSON, grouped context, and provider requests.
Select for relevance. Core for structural efficiency. One integrated workflow.


Python quickstart | Python fit workflow | Select | Benchmark highlights | Other integrations | How it works | Core | Full results | Extended tooling | Safety and auditability | Reproduce the results | Contributing | License
Built for: Python, TypeScript, and Rust developers and AI teams fitting JSON, tool definitions, and grouped context into LLM requests. Coding-agent, CLI, and proxy integrations use the same underlying Core engine.
Python >=3.12. Install the current SDK release; the base workflow needs no repository checkout, model, GPU, or ML framework:
python -m pip install "tokenfold==0.6.0"The SDK fits text, JSON, or grouped context to an explicit token ceiling. Fitting is offline and model-free unless you explicitly configure and consent to Select. No automatic sending, model downloads, or recoverable pruning occurs.
Default Data(records) renders standard compact JSON; opt into the folded
representation only for consumers you have validated:
from tokenfold import Data, fit

records = [
    {"id": i, "service": "checkout-api", "region": "us-east-1",
     "status": 200, "latency_ms": 42 + i}
    for i in range(1, 31)
]
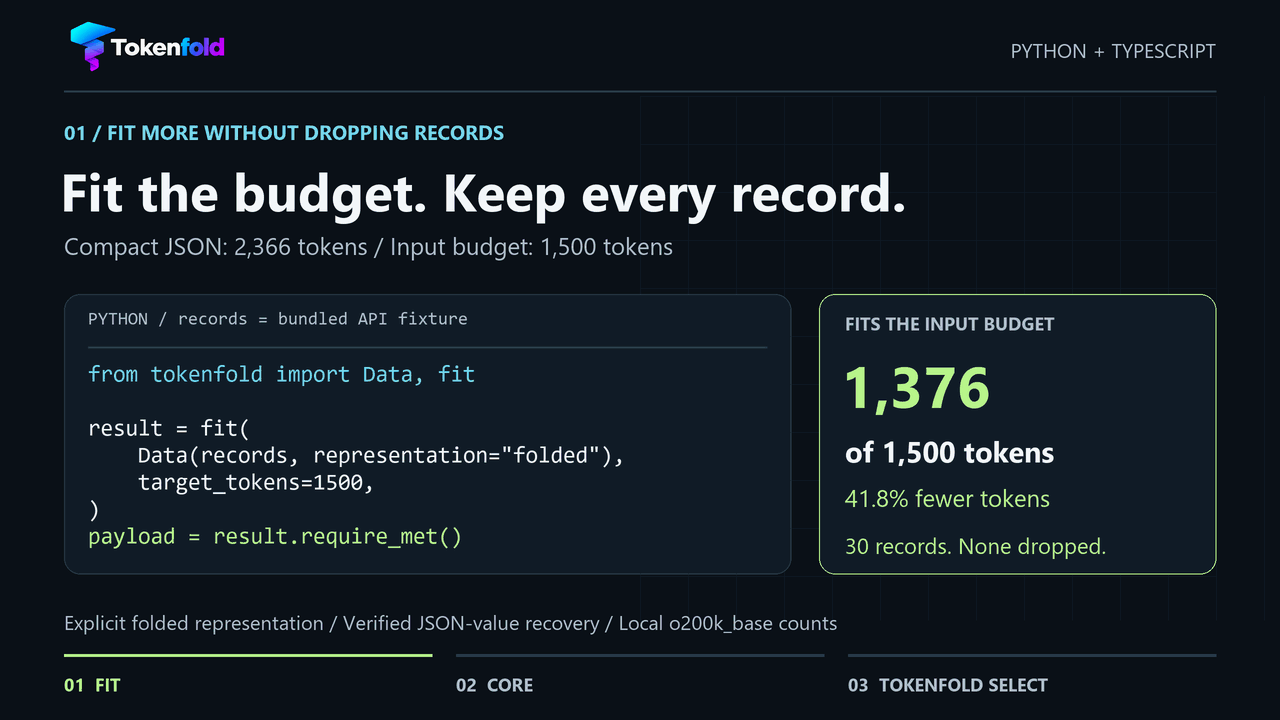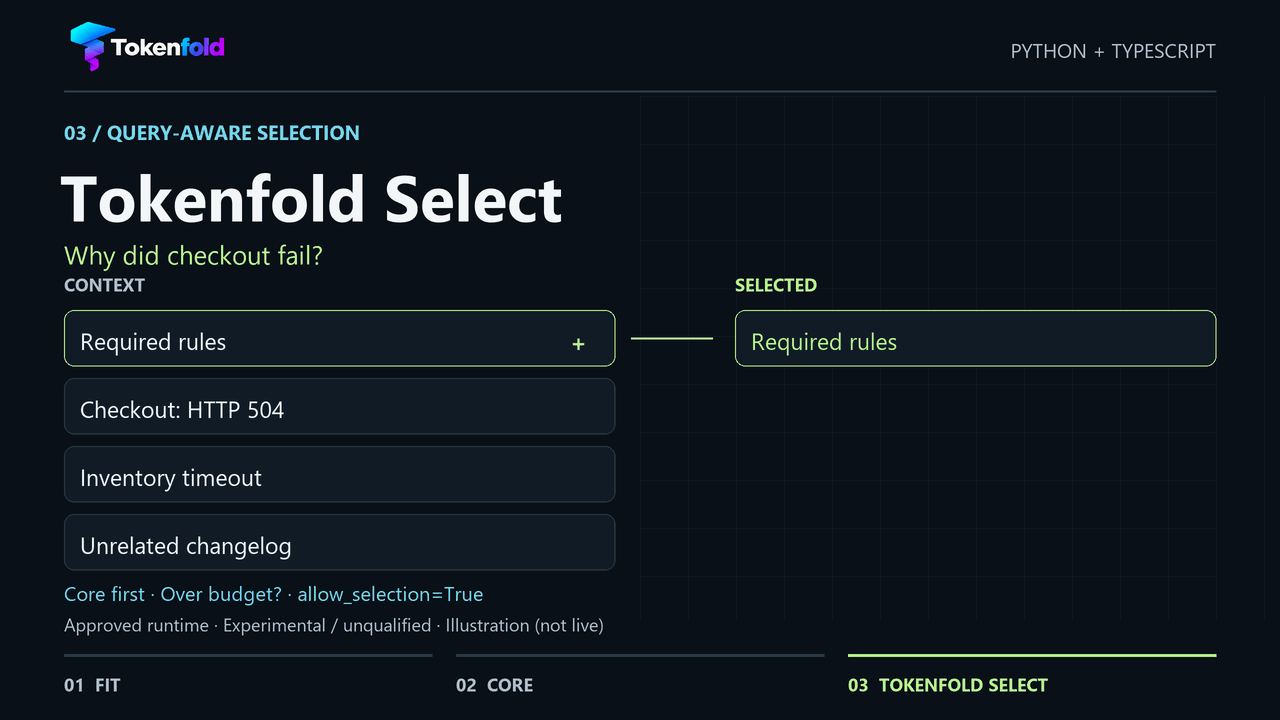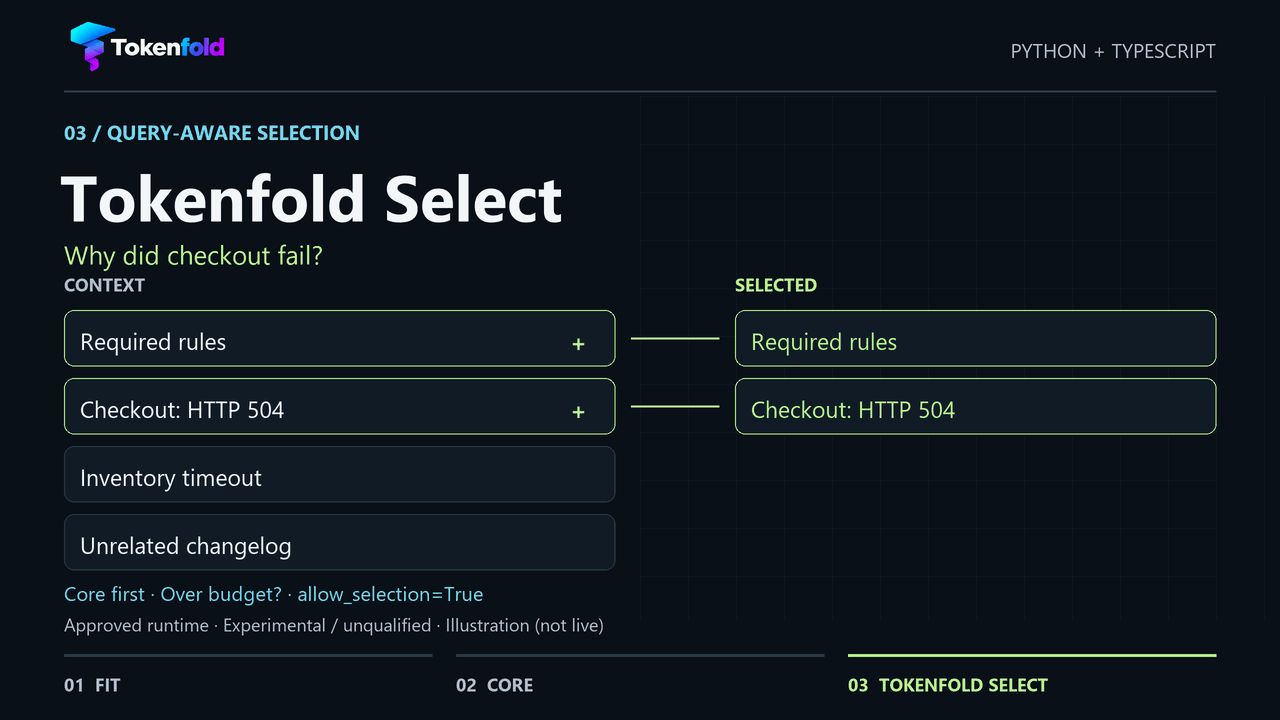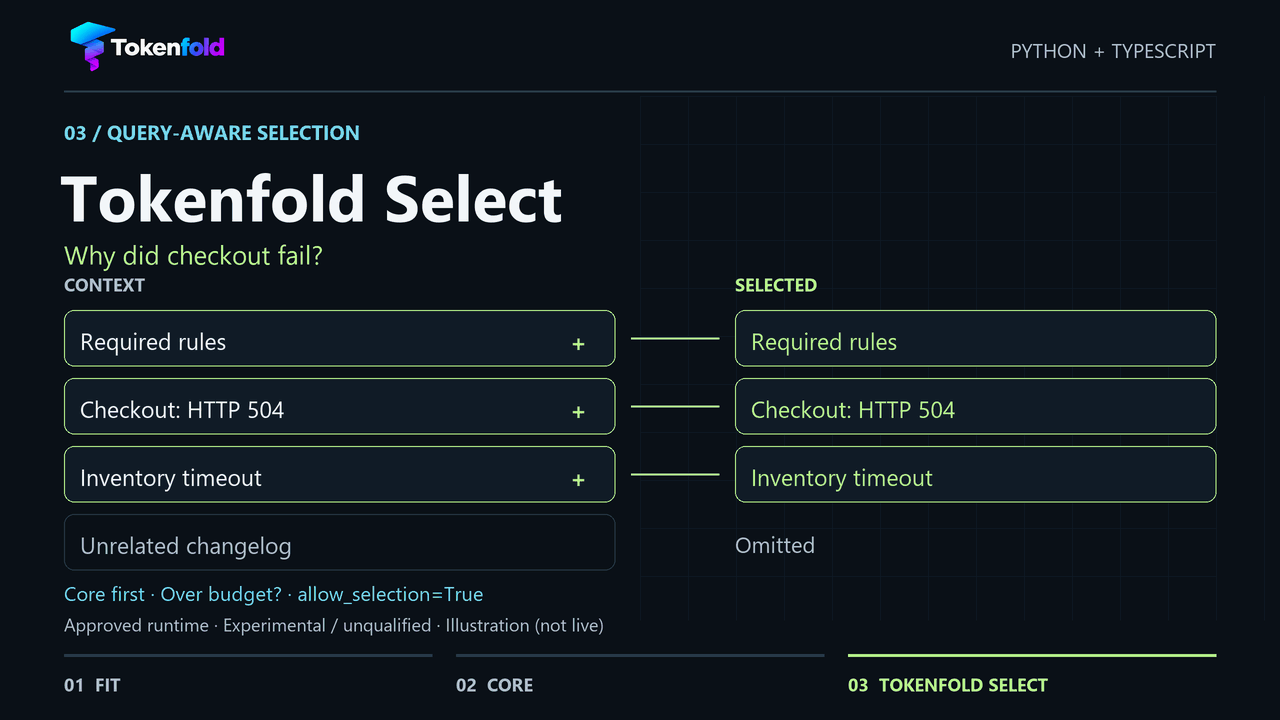
result = fit(Data(records, representation="folded"), target_tokens=500)
print(f"{result.original_tokens} -> {result.final_tokens} tokens")
payload_text = result.require_met()
print(result.receipt.to_json())
require_met() returns the payload only when the exact budget is met; otherwise
it raises BudgetUnmetError or BudgetIndeterminateError with the receipt.
Text/Data/Context return text; full provider requests return JSON objects.
An exact encoding count is not an exact provider-framing or billing count.
Explicit best-effort can accept an estimate without calling it exact.
See the Python example, migration guide,
and validation status. Advanced compression lives
under tokenfold.lowlevel.
For callers using the lower-level compression API, import it from
tokenfold.lowlevel:
import json
from tokenfold.lowlevel import InputFormat, compress, decode

records = [
    {"id": i, "service": "checkout-api", "region": "us-east-1",
     "status": 200, "latency_ms": 42 + i}
    for i in range(1, 31)
]
raw_bytes = json.dumps(records).encode("utf-8")
result = compress(raw_bytes, format=InputFormat.JSON)
print(f"{result.report.original_tokens} -> {result.report.compressed_tokens} tokens")
assert json.loads(decode(result.payload)) == recordsWhen structure ends, rank what matters.
Tokenfold Select v3 is an Apache-2.0, 149.6M-parameter
joint-group Ettin scorer, integrated into the SDK's fit() workflow.
Core remains model-free and neither loads nor invokes Select.
The SDK uses the lightweight maintained tokenfold-select-runtime,
not the superseded v2 package or an implicit direct-bundle loader. Model files are
acquired separately at an immutable revision; they do not ship in a clone or base SDK.
Use explicit CPU/FP32 or CUDA/BF16 setup and per-fit selection consent. Import and
already-fitting Core requests never load weights. Selection is experimental and
unqualified: grouping and required flags preserve caller-declared dependencies,
not independent proof of answer quality. No automatic recoverable pruning occurs.
See provisioning, accounting, and lifecycle.
After explicit runtime provisioning, supply the resulting config and allow selection on each fit. Keep dependent content in one group or mark it required:
from tokenfold import Context, Group, SelectRuntime, Tokenfold

context = Context(
    query="Which change caused the cache failure?",
    groups=[
        Group("constraints", "Use only the supplied release evidence.", required=True),
        Group("changes", "Commit a41f9c changed the Redis TTL to 0ms."),
        Group("logs", "After that release, cache evictions spiked on shard-02."),
        Group("notes", "Weekly planning notes cover unrelated roadmap items. " * 40),
    ],
)
with Tokenfold(select=SelectRuntime("select-runtime.json", experimental=True)) as client:
    result = client.fit(context, target_tokens=96, allow_selection=True)
    print(result.receipt.to_json())
    fitted_context = result.require_met()
    print("Selection applied:", result.selection_applied)
    print("Kept:", result.groups_kept, "Dropped:", result.groups_dropped)
The full context deliberately exceeds the ceiling. A successful fit requires selection; the example does not promise particular kept IDs or answer accuracy. If scoring fails or cannot meet the budget, checked access rejects the overflow rather than silently returning a successful fit. Already-fitting requests skip scoring even when consent is present.
Saved fixture results, not universal savings or downstream quality guarantees:
| Scope | Measured result | Limits and evidence |
|---|---|---|
| Core structural compression | 45.6-63.9% on two fixtures, lossless | Tool schemas and the 30-record API response; exact JSON-value recovery |
| Core vs. Headroom | 6/6 fixture wins, 13,071 -> 8,715 tokens (33.3% saved) | Default local generic-JSON paths; Tokenfold recovered 6/6 exactly, Headroom matched 4/6 |
| Tokenfold JSON vs. TOON 4.1.1 | 7/7 fixture wins, 12,776 vs. 14,841 tokens | 13.9% fewer tokens than TOON in this corpus; both paths round-trip |
| Opt-in, recoverable pruning | Up to 96.3% fewer tokens (showcase) | A 100-row heterogeneous feed; omitted rows stored behind local $tf_ref handles, not lossless inline compression |
These structural counts use exact o200k_base accounting. Inputs and provenance
live in the metric manifest; see
full comparisons and methods and the
pruning showcase. The historical 67.6% result
is a 50-record CHANGELOG measurement without a versioned source fixture; it was
not reproduced in the SDK rerun and is not used in the headline.
The saved downstream-answer diagnostic recorded 8/8 correct baseline answers vs. 6/8 with folded JSON; Select matched 16/16 baseline answers on eight synthetic tasks with two trials each. These are small development diagnostics, not representative quality or Select qualification.
Python is the primary SDK onboarding path. TypeScript is supported alongside it; CLI, MCP, proxy, and Rust are alternative entry points, not Python prerequisites.
| Interface | Install / setup | Primary use case |
|---|---|---|
| Python | python -m pip install "tokenfold==0.6.0" |
Native fitting SDK; start above |
| TypeScript / Node.js | npm install tokenfold@0.6.0 |
Native fitting; CLI utilities live under tokenfold/cli |
| MCP | tokenfold mcp serve |
Coding agents and editors; install the CLI first |
| CLI | cargo install tokenfold-cli |
Files, stdin, and shell workflows |
| Proxy | cargo install tokenfold-proxy |
Existing OpenAI-compatible clients |
| Rust | cargo add tokenfold-core |
Native embedding |
Node >=22. Install the published SDK package. Core fitting runs in-process; the base install needs neither Python nor a source build:
npm install tokenfold@0.6.0See the Node example and migration guide:
import { fit } from "tokenfold";
const result = await fit("Keep this text unchanged.", { targetTokens: 32 });
const payload = result.requireMet();
Coding agents can exhaust context limits on large shell outputs. Tokenfold runs as a
stdio MCP server exposing tokenfold_compress, tokenfold_inspect,
tokenfold_retrieve, and tokenfold_stats, with pre-configured filters for Git
status, diffs, build output, and test logs before they consume agent context.
tokenfold init currently supports Claude Code; Codex uses manual MCP
registration:
tokenfold init --agent claude-code
tokenfold doctor --agent claude-code

# Or connect manually in Codex:
codex mcp add tokenfold -- tokenfold mcp serve
tokenfold init --agent claude-code merges a project-scoped .mcp.json entry without replacing
other servers; tokenfold doctor --agent claude-code verifies it. tokenfold_inspect
is side-effect-free (never returns a modified payload); tokenfold_retrieve
retrieves by hash or marker (report references are reserved but not yet
resolvable). See
docs/configuration.md for tested MCP JSON/TOML and every environment
override. Trusted filters for Git, build, and test output
are available through tokenfold filters list.
Start the local proxy once, then point an existing client at it. The proxy forwards provider-shaped requests to your fixed upstream and applies Core's lossless transforms before forwarding.
cargo install tokenfold-proxy
tokenfold-proxy --upstream https://api.openai.com
from openai import OpenAI
# Your client's Authorization header is forwarded to upstream unchanged -
# no credential reconfiguration needed.
client = OpenAI(base_url="http://127.0.0.1:8787/v1")
# Existing calls work unchanged: client.chat.completions.create(...)The proxy listens on loopback (127.0.0.1:8787) by default.
Provider envelopes are minified, not columnar-folded.
Works out-of-the-box with any client or framework that accepts a custom base URL (LangChain, LlamaIndex, LiteLLM, Instructor, or direct HTTP clients).
Proxy routing, streaming, and stderr telemetry details
The proxy installs from source via Cargo and listens on 127.0.0.1:8787 by
default (--bind; use --allow-non-loopback-bind to change that). Only
chat-shaped JSON bodies (a non-empty messages array) are compressed on the
passthrough path; anything else forwards untouched. Non-GET /livez|/readyz|/health
requests forward upstream with the incoming path appended to --upstream, so
point OpenAI-shaped clients at <bind>/v1. Prebuilt, checksummed release
binaries are published for the CLI only; the proxy has no prebuilt binary.
SSE responses stream through unbuffered with a whole-exchange
--upstream-timeout-secs deadline.
Every forwarded request also emits exactly one measurement event on stderr, as
a single JSON line (tokenfold.measurement {...}, schema 1.0 from
tokenfold_core::measurement): the request id, a hashed
X-TokenFold-Session-Id when the client sends one, the requested model's
tokenizer resolution, the local before/after counts with their estimator, the
provider's own usage when it reports any (streamed SSE or buffered JSON,
merged snapshot by snapshot), a signed local-versus-provider delta, and how the
attempt ended. A provider that reports no usage, or a body whose usage cannot
be read cleanly, records usage_disposition: absent|malformed|oversized with a
null count rather than a zero -- and never changes what is forwarded.
%%{init: {"theme": "base", "themeVariables": {"fontFamily": "Arial", "fontSize": "15px", "actorBkg": "#f8fafc", "actorTextColor": "#0f172a", "actorBorder": "#94a3b8", "actorLineColor": "#94a3b8", "signalColor": "#64748b", "signalTextColor": "#334155", "activationBkgColor": "#eff6ff", "activationBorderColor": "#2563eb", "sequenceNumberColor": "#ffffff"}, "sequence": {"mirrorActors": false, "actorMargin": 56, "messageMargin": 36}}}%%
sequenceDiagram
    accTitle: Proxy request and response lifecycle
    accDescr: The client sends a provider-shaped request to Tokenfold Proxy, which applies lossless transforms and forwards the compact request with Authorization unchanged. The upstream response returns through the proxy.
    autonumber
    participant C as Client / Agent
    participant P as Tokenfold Proxy
    participant U as Upstream LLM
    C->>+P: Provider-shaped request
    P->>P: Apply lossless transforms
    P->>+U: Compact request + unchanged Authorization
    U-->>-P: Completion / action
    P-->>-C: Response
For files and stdin, install the CLI with cargo install tokenfold-cli or use a
checksummed GitHub Release:
tokenfold inspect payload.json --format json
tokenfold compress payload.json --format json --output payload.compact.json
For provider-shaped JSON, use the low-level Python API from tokenfold.lowlevel:
from tokenfold.lowlevel import InputFormat, compress

# Accepts raw JSON bytes or str (messages, tools, or schemas)
request_json_bytes = b'{"messages": [{"role": "user", "content": "hello"}]}'
result = compress(request_json_bytes, format=InputFormat.OPENAI_JSON)

# For standalone JSON records, use: format=InputFormat.JSON
compressed_payload = result.payload  # bytes
print(f"Saved {result.report.saved_tokens} tokens ({result.saved_pct():.1f}%)")After building and installing the SDK, run the examples under examples/:
python examples/quickstart.py      # Python: compress messages, request bodies, JSON data
node examples/quickstart.mjs       # TypeScript/Node: compress, inspect, read the receipt
cargo run -p tokenfold-core --example quickstart   # Rust: the embedded core API
python examples/lossy_pruning.py   # CLI: opt-in recoverable pruning, end to end
examples/quickstart.ipynb is the guided tour of the whole
Python surface: everything quickstart.py shows, plus previews, budgets and presets,
provider payloads, recoverable pruning with retrieval, and where Tokenfold Select fits.
// Input (conceptual illustration - 2 rows shown; small inputs like this
// pass through unchanged under the never-larger guard)
[{"id":1,"role":"admin"},{"id":2,"role":"member"}]

// Tokenfold output on larger uniform arrays -> still JSON
{"__tf_cols__":["id","role"],"__tf_rows__":[[1,"admin"],[2,"member"]]}
Column names label each value's position in every row. Use folded JSON only
with a consumer you have validated for that representation; decode when your
application needs the original object shape. The SDK's default Data
representation keeps standard compact JSON.
- Targets structured JSON, not prose. Folds repeated keys and columns mechanically rather than using semantic guesswork.
- Model-free and deterministic. Zero models running in Core and zero GPU overhead.
- Verified by exact decode. Every lossless transform is verified by an in-memory round trip before emitting; lossy pruning is strictly opt-in and recoverable.
%%{init: {"theme": "base", "themeVariables": {"primaryColor": "#f8fafc", "primaryTextColor": "#0f172a", "primaryBorderColor": "#94a3b8", "lineColor": "#64748b", "edgeLabelBackground": "#f8fafc", "fontFamily": "Arial", "fontSize": "15px"}, "flowchart": {"curve": "linear", "padding": 16, "nodeSpacing": 40, "rankSpacing": 32}}}%%
flowchart LR
    accTitle: Lossless first, pruning only when opted in
    accDescr: Build a verified lossless baseline. Consider pruning only when opted in, eligible, and still needed. Store omissions before removal and use pruning only if it beats the lossless baseline; otherwise keep that baseline.
    Lossless["Build lossless JSON baseline<br/>Verify folds; retain savings"] --> OptIn{"Pruning enabled,<br/>eligible and needed?"}
    OptIn -->|No| Keep("Lossless payload<br/>+ receipt")
    OptIn -->|Yes| Prune["Rank eligible rows<br/>Store before removal"]
    Prune -->|No further savings| Keep
    Prune -->|Fewer tokens than baseline| Emit("Pruned payload<br/>+ markers and receipt")

    classDef core fill:#eff6ff,stroke:#2563eb,stroke-width:2px,color:#1e3a8a
    classDef optional fill:#f8fafc,stroke:#64748b,stroke-dasharray:5 4,color:#334155
    class Lossless,Keep core
    class Prune optional
Text version (screen readers / no-image fallback)
- Build the lossless baseline using eligible transforms. Verify structural folds with an exact decode round trip and keep only token reductions.
- Consider pruning only when explicitly opted in, the payload is eligible, and the lossless baseline has not already met a requested token target.
- Rank eligible rows and store omissions locally before removing them. Rows refused by storage stay inline.
- Use the pruned payload only if it has fewer tokens than the lossless baseline; otherwise keep the lossless baseline.
- Emit the chosen payload and compression receipt. Pruned payloads include retrieval markers for stored omissions.
Core removes structural redundancy, not prose selected by a language model. See what the model sees for the columnar JSON format and the verified lossless-first pipeline. Unlike semantic prompt compressors such as LLMLingua, Core needs no model or GPU, does not inject prompt guidance, and does not fine-tune models.
Tokenfold Select complements Core when query-aware group selection is explicitly enabled.
| Preset | Behavior |
|---|---|
conservative |
Minification only; no restructuring of what the model sees. |
balanced (default) |
Minification plus reversible columnar folding (json_field_fold, json_value_dict, log_field_fold) on eligible formats. |
aggressive |
Same default transform set as balanced today. |
Provider message formats (openai_json, anthropic_json) use minification
only; columnar folding applies to generic JSON (--format json). The default
proxy path follows this rule. Explicit --observations enables lossless
compression of eligible JSON tool-result strings on /v1/chat/completions
without folding the provider envelope; see observation compression.
Note
schema_compaction is not enabled by any preset. Unlike the default
transforms, it truncates examples arrays and is not reversible.
On 2026-11-10, one free hosted model (nvidia/nemotron-3.5-super-vl:free,
Nvidia provider) answered 12 predeclared tasks twice per arm, with counterbalanced
order and exact typed-JSON grading. The 48 completed quality calls measured
answers, not just whether answer text survived compression:
| Path | Distinct tasks x trials | Baseline correct | Candidate correct | Provider prompt tokens |
|---|---|---|---|---|
| Explicit folded JSON vs. compact JSON | 4 x 2 | 8/8 | 6/8 | 24,496 -> 16,600 (32.2% fewer) |
| Select at a 50% rendered-text budget vs. full context | 8 x 2 | 16/16 | 16/16 | 5,706 -> 3,416 (40.1% fewer) |
Exact recovery did not guarantee correct model answers: both folded-JSON
failures misread the same nested API record's plan tier and seat count. Default
SDK Data uses compact JSON; folding requires explicit opt-in. Select matched
its baseline on these eight synthetic tasks, not a representative accuracy test.
Repeated trials are not additional independent tasks; Select remains unqualified.
The first model scope stopped on a rate-limited probe, with all 48 quality cells unexecuted; it is retained, not scored as 0% accuracy or silently retried. See the full method, failures and limits, frozen prompts and oracles, and all-attempt results.
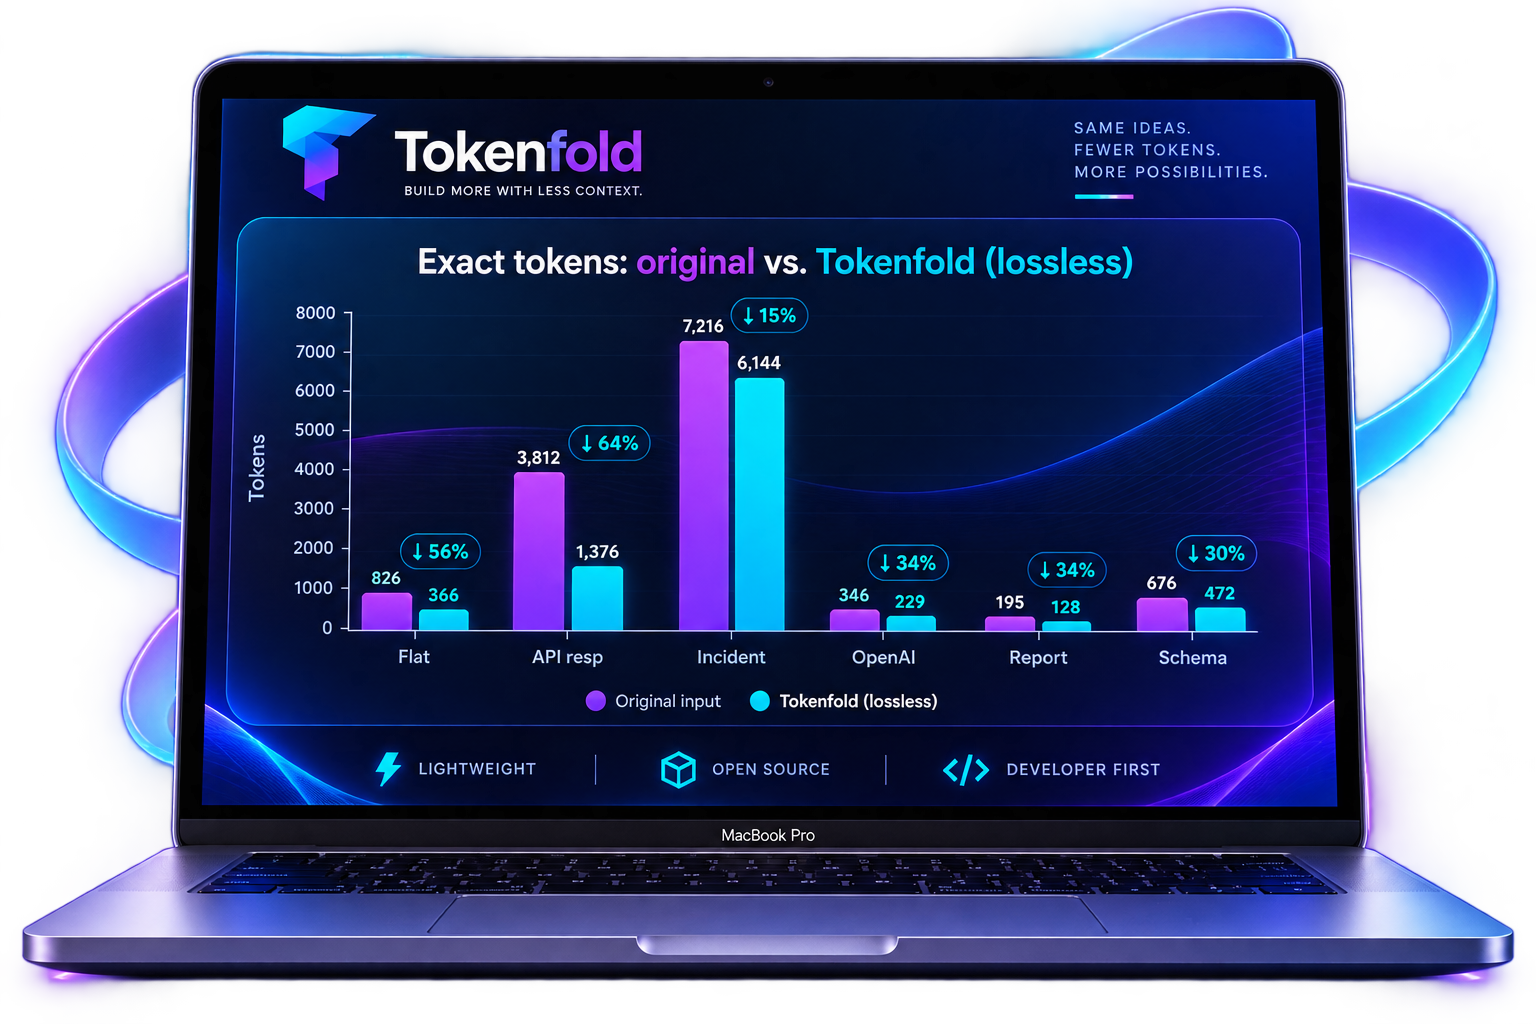
Exact o200k_base token counts, original input versus Tokenfold's lossless
output across the six-fixture Headroom corpus:
| Workload | Original | Tokenfold | Headroom | Token winner; recovery |
|---|---|---|---|---|
| Flat uniform records | 826 | 366 | 826 | Tokenfold (-55.7%); both exact |
| Nested API response | 3,812 | 1,376 | 3,812 | Tokenfold (-63.9%); both exact |
| Semi-uniform incident feed | 7,216 | 6,144 | 6,963 | Tokenfold (-14.9%); Headroom altered payload |
| Deeply nested OpenAI payload | 346 | 229 | 335 | Tokenfold (-33.8%); Headroom altered payload |
| Nested compression report | 195 | 128 | 195 | Tokenfold (-34.4%); both exact |
| Deeply nested report schema | 676 | 472 | 676 | Tokenfold (-30.2%); both exact |
| Six-fixture corpus | 13,071 | 8,715 (33.3% saved) | 12,807 (2.0%) | Tokenfold won 6/6; exact recovery 6/6 |
See the Headroom methodology for environment setup, pinned comparator revision, and reproduction.
| Workload | Compact JSON | Tokenfold JSON | TOON 4.1.1 | Token winner; round trip |
|---|---|---|---|---|
| Flat uniform records | 586 | 366 | 377 | Tokenfold (-37.5%); both round trip |
| Nested API response | 2,366 | 1,376 | 2,839 | Tokenfold (-41.8%); both round trip |
| Semi-uniform incident feed | 6,144 | 6,144 | 6,579 | Tokenfold retains compact JSON; both round trip |
| Deeply nested OpenAI payload | 229 | 229 | 237 | Tokenfold retains compact JSON; both round trip |
| Nested compression report | 128 | 128 | 131 | Tokenfold retains compact JSON; both round trip |
| Deeply nested report schema | 472 | 472 | 517 | Tokenfold retains compact JSON; both round trip |
| Wide metrics table | 6,310 | 4,061 | 4,161 | Tokenfold (-35.6%); both round trip |
| Seven-fixture corpus | 16,235 | 12,776 | 14,841 | Tokenfold fewer on 7/7 (3 transforms, 4 never-larger guards); 13.9% fewer than TOON |
In aggregate across the seven fixtures:
| Encoding across seven JSON fixtures | Exact tokens | vs. compact JSON |
|---|---|---|
| Tokenfold JSON | 12,776 | 21.3% fewer |
| Compact JSON | 16,235 | baseline |
| Official TOON CLI 4.1.1 | 14,841 | 8.6% fewer |
On irregular structures, TOON can use more tokens than compact JSON. Tokenfold's never-larger guard retains compact JSON when an eligible lossless transform would not reduce the exact token count.
All counts use exact o200k_base recounts. Tokenfold passed exact recovery on
all six Headroom fixtures and all seven TOON fixtures; Headroom's emitted JSON
matched the input value on 4/6 fixtures (the semi-uniform incident feed and the
deeply nested OpenAI payload differed), so its aggregate reduction is not a
lossless result. See the Headroom methodology
and TOON methodology for the versioned corpora, pinned
comparator revisions, and full fixture-level results.
Headroom benchmark methodology and reproduction
This comparison covers default local generic-JSON paths, not multi-turn message history or hosted proxy behavior. On these raw JSON arrays, schemas, and nested payloads, Tokenfold's default local path produced fewer tokens than Headroom on all six while decoding every value exactly.
Both outputs were recounted with exact o200k_base. Tokenfold passed exact
decode checks on 6/6 fixtures; Headroom's emitted JSON matched the input value
on 4/6, so its aggregate reduction is not a lossless result. This comparison
uses each project's default local generic-JSON API, not hosted proxy behavior,
with Headroom pinned to 4c9c29c.
See the checked-in report,
corpus, and
reproduction command.
TOON benchmark methodology and reproduction
Tokenfold now supports TOON as an explicit, round-trip-verified output codec. Its default structural JSON encoding is still the better choice when the goal is the fewest tokens.
The new examples/toon_metrics.json fixture is a 120-row, wide, uniform
metrics table - the shape where TOON is expected to be strongest. Tokenfold
produced fewer tokens than TOON on all seven fixtures and used 13.9% fewer
tokens in aggregate: a reducing structural transform on three fixtures, and
the never-larger guard retaining compact JSON (still smaller than the TOON
output) on four. Both paths passed lossless recovery checks.
The benchmark uses exact o200k_base counts and the same versioned corpus for
both tools. See the checked-in TOON report
and reproduction command.
Saved results from the published v3 benchmark snapshot,
pinned to model-card revision 317d3424d3de78c1a708c42a47a7812ab877f1a8.
These measurements include the scorer and whole-group allocator, not the
scoring model alone. Core's lossless benchmarks are separate above.
Select v3 removed 50.0-60.0% of the original context tokens in these five
saved development examples. Both models had the same exact o200k_base output
cap for each workload; retained V3 groups were copied without rewriting.
| Workload | Original tokens | Select v3 output | V3 reduction | Kompress v2 output |
|---|---|---|---|---|
| Code | 4,411 | 2,205 | 50.0% | 2,149 |
| JSON | 1,303 | 651 | 50.0% | Refused; 1,303 raw |
| Logs | 1,103 | 503 | 54.4% | Refused; 1,103 raw |
| Multi-turn | 587 | 235 | 60.0% | 284 |
| Retrieval | 4,498 | 2,217 | 50.7% | 2,219 |
One exposed source per workload; JSON and logs share a source population. Token reduction does not establish answer accuracy or semantic preservation. Six of ten historical Kompress cells refused the budget across the 25%/50% screen; refusals and raw fallbacks are inconclusive, not V3 wins. The full ten-cell history retains every result.
| Workload | Select v3 ms | Kompress v2 ms | V3 time difference |
|---|---|---|---|
| Code | 146.088 | 200.304 | -27.1% |
| Retrieval | 139.291 | 201.564 | -30.9% |
| Multi-turn | 66.572 | 77.751 | -14.4% |
Resident-warm RTX 5080 research pipelines, FP32 parameters/BF16 compute; startup excluded. Code and retrieval each use one historical request per model; multi-turn uses the median of five. Separate time blocks, not controlled-idle or paired trials. These are descriptive development observations, not representative quality, population p50/p95, or superiority qualification.
Benchmark methodology and preserved history
RTX 5080, FP32 parameters/BF16 compute, cache off, TF32 off, one Torch thread. V3 used the serialized SDPA research runner; Kompress v2 used native EAGER. Complete-request clocks include grouping, counting, IPC, scoring, allocation, final recount and applicable teardown, but exclude process/model startup and conditioning. They are not cold-CLI or quickstart-SDK latency measurements.
The models ran in separate time blocks. The five-request multi-turn repeat was not controlled-idle: the GPU-busy admission gate was explicitly waived, with pre-model busy observations of 25% and 38%. All five samples per model are retained. The earlier multi-turn result was 69.362 ms vs 64.411 ms (V3 time 7.7% higher), and remains in the history rather than being replaced by the repeat's sample medians.
The shared synthetic publisher-data pilot has incomplete comparator/answer evaluation; its literal-substring checks are not answer accuracy. The separate partial answer-lookup evaluation also remains incomplete, with no overall quality score or qualified 90% comparability claim.
Sources: exact counts, timings, all repeat samples and refusals, validation, and full methodology.
Historical Select v1 benchmarks (not v3 results)
The original Tokenfold Select v1 model card reports the following literal-answer-retention results against Kompress-v2 and BM25. These are source-reported external results, not Core CI or v3 results.
| Tokens kept | Tokenfold Select | Kompress-v2 (Headroom) native | Kompress-v2 (Headroom) relevance | BM25 | vs. best baseline |
|---|---|---|---|---|---|
| 50% | 86.3% | 66.5% | 80.5% | 79.4% | +5.8 pp |
| 25% | 70.3% | 47.2% | 61.5% | 60.7% | +8.8 pp |
| 10% | 39.9% | 30.4% | 37.7% | 37.7% | +2.2 pp |
In this v1 evaluation, Select beat every measured baseline at every budget. At a 25% budget, the fine-tuned ranker keeps the answer 70.3% of the time: an 8.8 percentage-point lead over the strongest baseline (Kompress-v2 relevance, 61.5%), and a 15.8% relative lift over BM25 (60.7% -> 70.3%). Critical-content survival is 100% at every measured budget through allocator force-keep. Results are three-seed repeated subsampling over roughly 73,000 training and 24,000 held-out fixtures per run; the v1 model card publishes the training recipe and full baseline set. Here, task success means the literal gold answer survived selection under the stated budget. These are source-reported external results, pinned by model revision in the metric manifest; Core CI does not reproduce them.
See the Select v1 model card for its setup, evaluation, training data, and limitations.
These additional capabilities extend Core with recoverable pruning and an explicit TOON output codec.
| Capability | What you get |
|---|---|
| Recoverable pruning | Drop low-signal JSON rows only after storing them locally; fetch any omission with tokenfold retrieve |
| JSON or TOON output | Keep Tokenfold's compact JSON default or explicitly emit verified TOON for compatible consumers |
While Tokenfold Core defaults to lossless structural folding, heterogeneous array feeds (such as long logs or search results) benefit from recoverable pruning when strict context budgets apply:
| Lossless - default | Recoverable lossy - opt-in | |
|---|---|---|
| What it does | Minifies, folds repeated keys into columns, and stores repeated values once | Adds deterministic ranking and retrieval markers for selected array rows |
| Best on | Uniform records, schemas, logs, diffs | Search results, mixed event feeds, agent traces, long arrays |
| Measured here | 45.6-63.9% fewer tokens on two versioned fixtures | 51.7-96.3% fewer tokens (40-event feed at 51.7-68.2%; 100-row showcase at 96.3%) |
| Recovery | All data remains in the payload | Every emitted marker resolves through the local retrieval store |
Lossless folding has a ceiling on heterogeneous arrays. --prune ranks rows,
keeps the strongest signals, and replaces selected rows with compact
{"$tf_ref": {...}} handles. A row leaves the payload only after the local
store accepts it.
tokenfold compress examples/incident_feed.json --format json \
  --prune --keep-ratio 0.35 --output feed.compact.json
On the bundled 40-event feed:
| Mode | Exact tokens | Reduction | Events kept | Incident kept |
|---|---|---|---|---|
| Lossless | 6,144 | 14.9% | 40 | Yes |
--keep-ratio 0.35 |
3,485 | 51.7% | 13 | Yes |
--keep-ratio 0.05 |
2,294 | 68.2% | 1 | Yes |
The planted 503 with success: false and retries: 7 survives every shown
setting because typed failure signals outrank position and length - at
--keep-ratio 0.05 it is the only row kept. Long rows
amortize marker overhead further: the 100-result showcase reaches 96.3% fewer tokens
(--keep-ratio 0.02, examples/max_showcase.json; see
tests/fixtures/readme_metrics.json).
Fetch a dropped row using the same --retrieval-store and
--retrieval-namespace as the compression run:
tokenfold compress examples/incident_feed.json --format json \
  --prune --keep-ratio 0.35 --output feed.compact.json \
  --retrieval-store ./store --retrieval-namespace incident-demo
tokenfold retrieve cb13cc59cca0c218c579cd1d4b3cbab58d6dea265eb995cc9c00faf0cd0a6856 \
  --retrieval-store ./store --retrieval-namespace incident-demo
# {"seq":1,"ts":"2026-08-15T00:01:11Z","subsystem":"index-writer",...}
What the flags mean:
--keep-ratiois an aggression hint over eligible array items. Lower keeps fewer rows; it is not a whole-document guarantee.--target-tokensis the whole-document goal. Tokenfold stops when it reaches the target losslessly and reportsbest_effortwhen the safe transform set cannot reach it (unreachablewhen protected content alone exceeds the target).--preserve <path>protects a named array; nested paths conservatively protect their nearest eligible ancestor.- Generic JSON only: lossy pruning does not run on OpenAI or Anthropic message
payloads. Pass the same
--retrieval-store/--retrieval-namespacetotokenfold retrievethat the compress run used. - Storage is fail-closed: refused rows stay inline, and detected secret-shaped
bytes are never persisted. Lossy pruning requires the
filesystemretrieval backend with TTL >= 24h (memory backends and near-immediate expiry are rejected);$tf_refis reserved.
Preview the projected savings with no store writes:
tokenfold inspect examples/incident_feed.json --format json \
  --prune --keep-ratio 0.35
The same flags and fail-closed contract are available through the low-level bindings. Use a throwaway store directory while experimenting and reuse it for retrieval:
import json
from pathlib import Path
from tokenfold.lowlevel import InputFormat, PruningPolicy, compress, retrieve

store = Path(".tokenfold-readme-store")
feed_bytes = Path("examples/incident_feed.json").read_bytes()
pruning = PruningPolicy(
    keep_ratio=0.35,
    retrieval_store=store,
    retrieval_namespace="readme-demo",
)
result = compress(feed_bytes, format=InputFormat.JSON, pruning=pruning)
payload = json.loads(result.payload)
marker = next(e["$tf_ref"] for e in payload["events"] if "$tf_ref" in e)
original = retrieve(
    marker, retrieval_store=store, namespace="readme-demo"
)  # any dropped row, verbatim
Current Phase 1 constraints
Treat $tf_ref as reserved and do not enable lossy pruning on documents that
already contain retrieval markers. Filesystem entries are published under a
cross-process lock, and a refused batch leaves every candidate inline.
Preview is a projection rather than a filesystem transaction, so a real run may keep more rows if storage becomes unavailable.
Compact Tokenfold JSON remains the default. For a TOON-aware consumer, request TOON explicitly and decode it through the same verified codec:
tokenfold compress examples/toon_metrics.json --format json \
  --preset conservative --encoding toon --output payload.toon
tokenfold decode payload.toon --from toon --output payload.json
TOON is available only for generic JSON and never activates implicitly. The receipt reports the exact encoding delta and warns when TOON is larger than the already-compressed JSON representation.
- Never larger: Core keeps a transform only when exact recounting shows a reduction; a lossy branch must also beat the lossless result.
- Reversible structure: JSON folds must pass an exact round trip.
- Protected content: provider system messages and latest-user content are held behind format-aware safety gates.
- Clear provenance: exact tokenizer counts, heuristics, and extrapolations are labeled separately.
- Actionable receipts: every result lists savings, transforms, warnings, retrieval state, and final status.
- Local control: detected secrets are redacted before reports or storage;
policy learning changes configuration only with
--apply.
Exact decode proves data recovery, not unchanged downstream task accuracy. Validate folded payloads with your representative workload.
The offline fidelity gate uses deterministic lexical-overlap, critical-token,
and containment proxies. Those checks catch regressions but do not establish
semantic equivalence or downstream task success. Runtime quality fields are
absent unless a versioned evaluator has supplied data; applications should run
their own representative task evaluation before enabling lossy pruning.
# 96.3% maximum-compression showcase, mixed-feed curve, retrieval, and preserve
python examples/lossy_pruning.py

# Lossless transform benchmarks
cargo bench -p tokenfold-core

# Head-to-head provider benchmark (setup and pinned dependency command)
# See eval/research/README.md

# Small exact-token CLI example
cargo run --release --locked -p tokenfold-cli -- \
  inspect examples/api_response.json --format json
The bundled 30-record API response reports 3,812 -> 1,376 tokens, a 63.9%
lossless reduction. Benchmark sources and thresholds live in CHANGELOG.md
and crates/tokenfold-core/benches/THRESHOLDS.toml.
Issues and pull requests are welcome. Run the relevant checks before opening a PR:
cargo fmt --all --check
cargo clippy --workspace --all-targets -- -D warnings
cargo test --workspace --locked
python eval/run_fidelity.py --gate --profile smoke-first-consumer
python eval/test_baseline_fixture_contract.py
python eval/audit_quality_sample.py --check
cd packages/tokenfold && npm ci && npm testStart with one representative payload, inspect the receipt, and see how many tokens your application can stop sending today.
If Tokenfold earns a place in your stack, a star on GitHub helps the next team find it.

