



Podcast Index MCP server and CLI for Claude Code, Codex and AI agents. 36 tools for podcast search, episode transcripts you can actually read and search, Podcasting 2.0 tags, value-for-value data, feed health and index stats.
One install gives you both surfaces, the same 36 tools under the same names, reading one array of tool definitions so they cannot drift apart.
It searches four million podcasts, and then it does the thing the API stops short of: it opens the transcript. Podcast Index hands out a link to an episode's transcript file and goes no further, which is useless to an assistant that cannot click. This fetches the file, works out whether it is SRT, WebVTT, JSON or HTML, and gives you the actual words with timestamps and speakers.
So you can ask when something was said, and get an answer.
There are 36 tools. One free key covers all but two of them.
Built by Navid Moazzez. Built on Slipway, which turns one definition of each tool into the MCP server and the CLI.
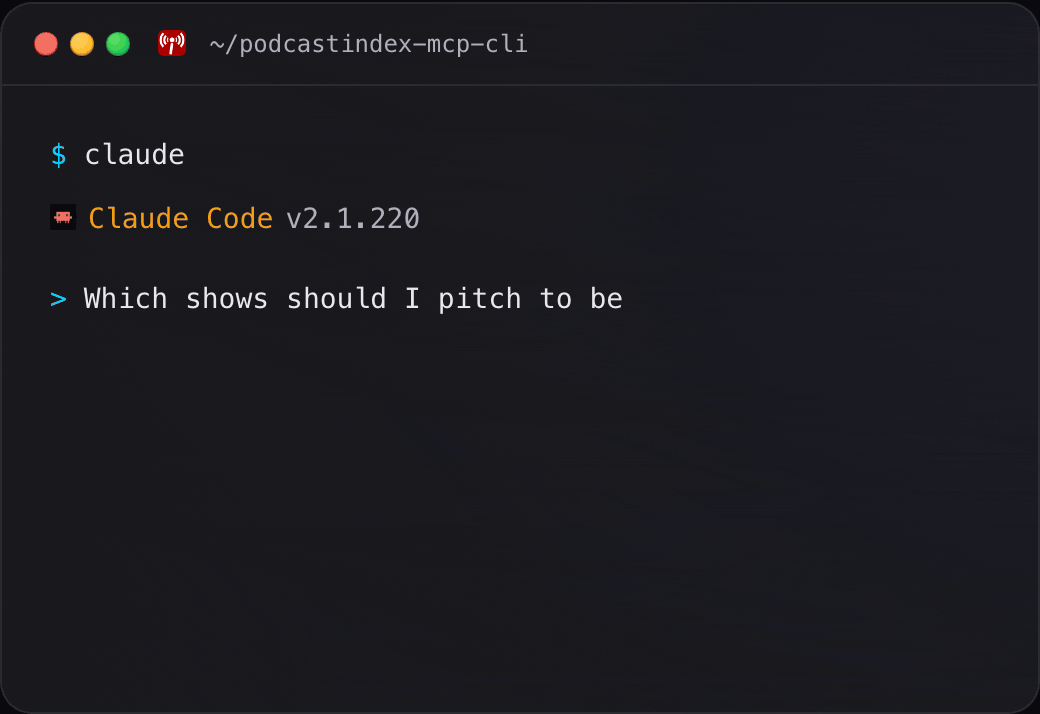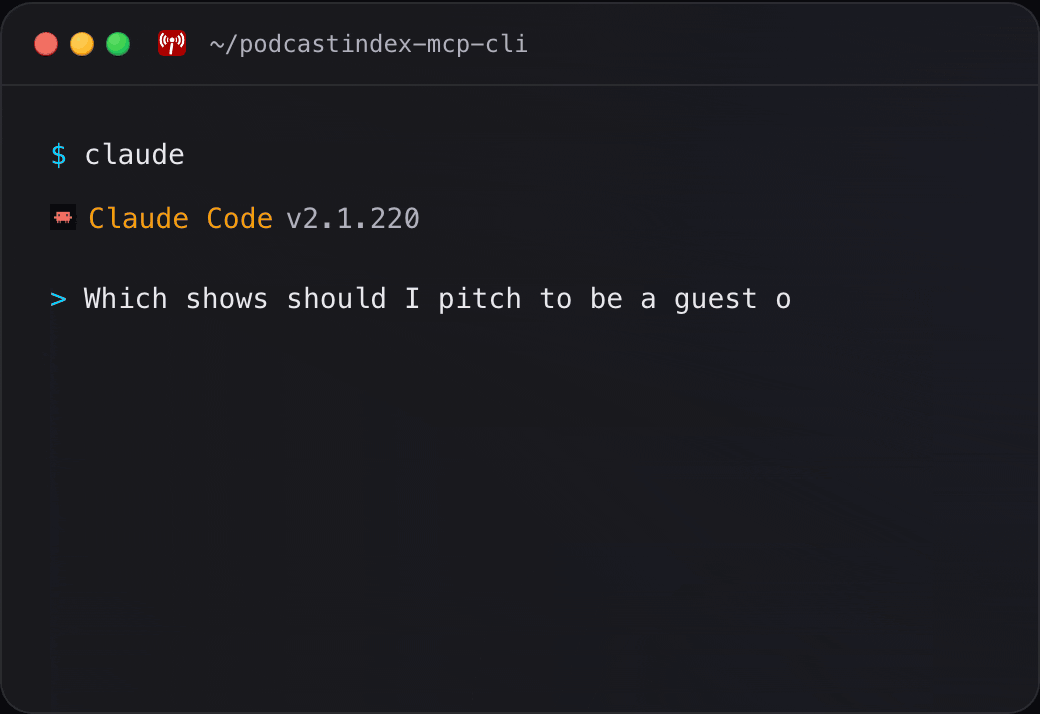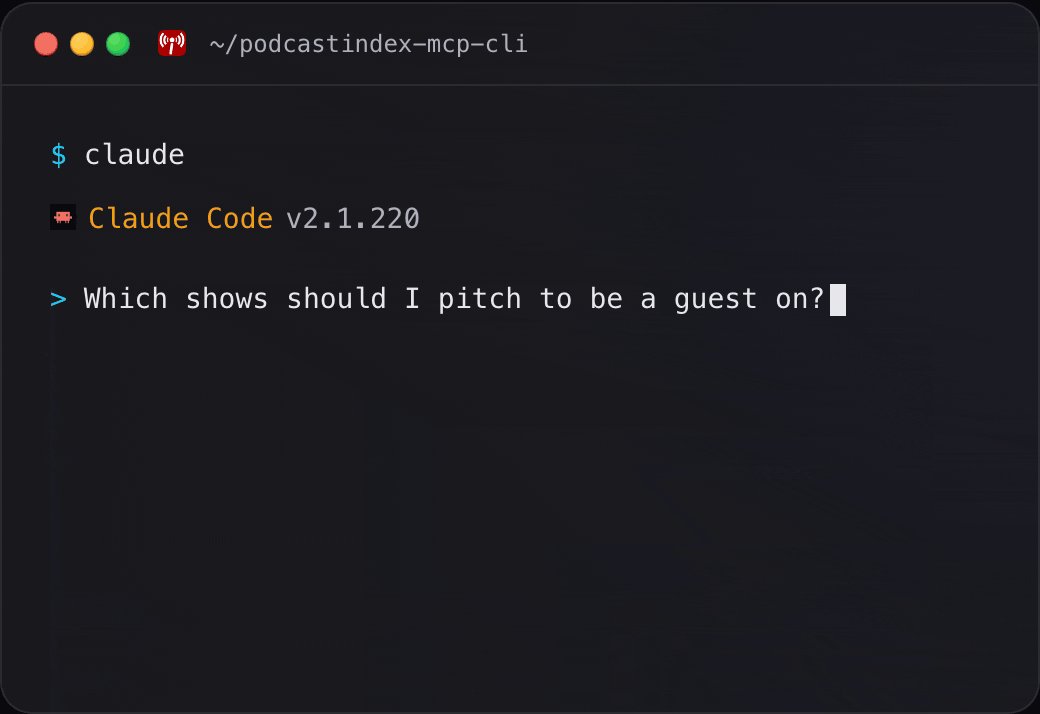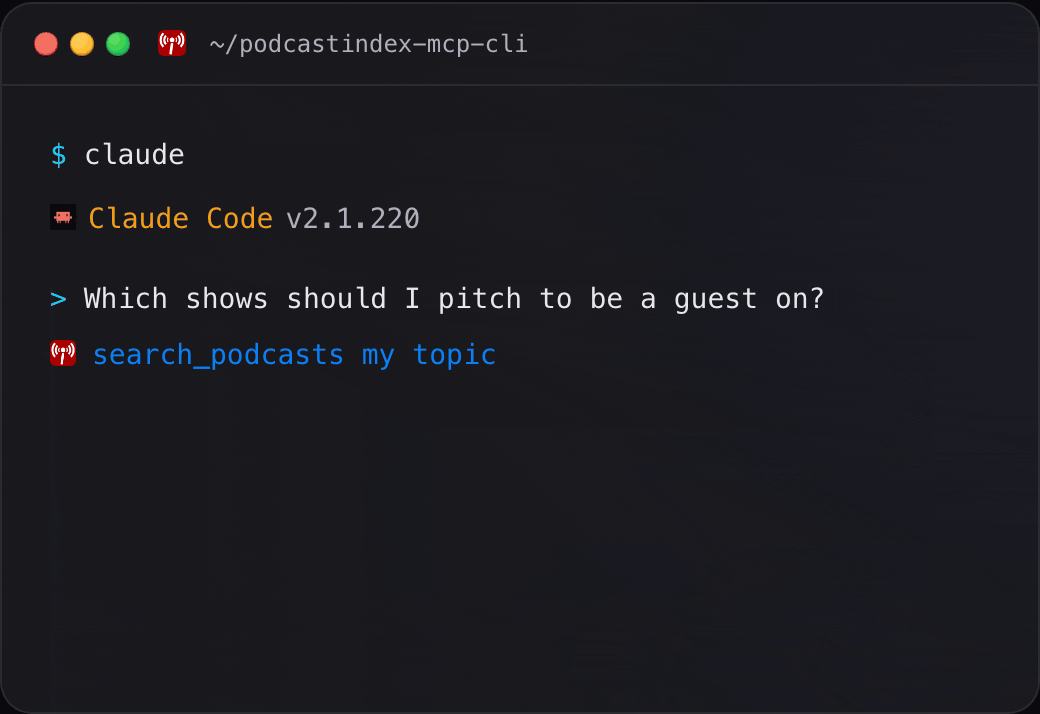
podcastindex-cli runs every tool as a command. Agents that run commands, like
Claude Code, Codex and OpenCode, use it on their own, and you can type the same
commands in a terminal, a script or a cron job:
podcastindex-cli                                          # every command, one line each
podcastindex-cli status                                   # what this server can reach
podcastindex-cli search-podcasts --q "ai agents" --max 5
podcastindex-cli get-trending --max 10
podcastindex-cli search-transcript --episode-id <id> --query "compound interest"
podcastindex-cli find-guest-appearances --name "Tim Ferriss"
podcastindex-cli check-feed-health --show https://example.com/feed.xml
podcastindex-cli submit-feed --feed-url https://example.com/feed.xml --confirm
podcastindex-cli <command> --help                         # what any command takes
--confirm is the shell spelling of the confirmation that adding a feed to the
index needs. --json gives JSON, --compact puts it on one line, --select
keeps only the fields you name, and --agent is compact JSON with no prompts,
and never confirms a write. Exit codes are 0 ok, 1 an unexpected error, 2 usage
or a hidden or refused write, 3 not found, 4 auth, 5 API, 7 rate limited and 10
nothing configured, so a script branches on the number.
podcastindex-cli schema <command> prints the exact JSON Schema an MCP client
receives for that tool.
podcastindex-mcp is what Claude Code, Claude Desktop, Cursor and the rest
launch. You never run it by hand:
claude mcp add podcastindex \
  -e PODCASTINDEX_API_KEY=your_key \
  -e PODCASTINDEX_API_SECRET=your_secret \
  -- npx -y @thenavidm/podcastindex-mcp-cli@latest
In Claude Desktop, the .mcpb extension
installs on a double click. Section 4 has every other client.
A feed submission waits for your approval in the client, as section 9 explains.
| Where you are | What you can reach |
|---|---|
| An agent that can run shell commands, like Claude Code or Cursor | Both. The CLI is the cheaper one: it costs nothing until you type it |
| claude.ai, the Claude Desktop chat tab, or a phone | The server only. There is no shell to run a command in |
| A terminal, a script, cron or CI | The CLI only. There is no MCP client in a shell |
They are the same program reading the same tool definitions, so anything one can do, the other can.
Both surfaces are the same program with the same 36 tools. The difference is when the model pays for them. Measured in Claude Code:
| Cost | MCP server | CLI |
|---|---|---|
| Every message, with every tool loaded | 11,800 tokens | nothing |
| Every message, Claude Code's default | 1,300 tokens | nothing |
| When Podcast Index comes up | nothing more, or the tools it picks | 3,400 tokens for SKILL.md, once |
| 20 messages with Podcast Index in 1, every tool loaded | 236,000 tokens | 3,400 tokens |
Claude Code's tool search is on by default: it sends only the tool names and the server instructions, and loads a tool's full definition when the model reaches for it. An app that loads every tool up front pays the first line on every message, whether Podcast Index comes up or not. With the skill added, Claude Code also lists its one-line description, about 160 tokens.
To spend less, turn the server off when you are not using it, which in Claude
Code is the /mcp panel. PODCASTINDEX_READ_ONLY=1 takes the 3 write tools off the list, leaving 33.
Or install the CLI and add the server on the days it earns its place.
Measured on 2026-10-05 with Claude Code 2.1.286 on Claude Opus 5.5: one
short prompt with and without the server connected, once with
ENABLE_TOOL_SEARCH=false and once with the default, the difference read
from the API's own usage figures. SKILL.md was measured the same way. Other
apps and models count tokens a little differently.
Against 1.1.2, measured the same day: every tool loaded costs 11,843 tokens
instead of 13,095, tool search the same (1,253 against 1,253), and SKILL.md
60 more, because it now says how approval works over MCP and lists every exit
code. In Codex 0.159.3 on gpt-6.1-sol, the same task, "find the command that
finds the moment a phrase was said in an episode's transcript, and the flags it
requires", read a median of 83,167 input tokens on 2.0.0 against 83,990 on
1.1.2 over the CLI, five runs each: Codex now asks which instead of reading
the full command list. Over MCP, Codex prints the tool list with a script and
cuts the printout to about 10,000 tokens, so it read about 9,020 on both
versions, out of a full listing of 28,195 tokens on 2.0.0 against 28,239, and
a median of 48,367 input tokens against 48,444.
Every tool is both a command and an MCP tool, with the same name. The command is the tool name with dashes.
| Capability | CLI command | MCP tool |
|---|---|---|
| Read what was said in an episode | podcastindex-cli get-transcript / search-transcript / get-chapters |
get_transcript / search_transcript / get_chapters |
| Questions, not endpoints | podcastindex-cli get-show-profile / find-guest-appearances / find-shows-to-pitch |
get_show_profile / find_guest_appearances / find_shows_to_pitch |
| Search the index | podcastindex-cli search-podcasts / search-episodes-by-person |
search_podcasts / search_episodes_by_person |
| Shows and episodes | podcastindex-cli get-podcast / get-episodes / get-podcasts-batch |
get_podcast / get_episodes / get_podcasts_batch |
| What is new and trending | podcastindex-cli get-trending / get-recent-episodes |
get_trending / get_recent_episodes |
| Value for value | podcastindex-cli get-value-block |
get_value_block |
| Feed health | podcastindex-cli check-feed-health |
check_feed_health |
| Add or refresh a feed | podcastindex-cli notify-feed-update / submit-feed |
notify_feed_update / submit_feed |
| Check your setup | podcastindex-cli doctor |
status |
All 36 are in section 6.
| # | Section | What is in it |
|---|---|---|
| 1 | What you can ask it | Real prompts, not features |
| 2 | Quick install | One line |
| 3 | Setup | Getting a key, about two minutes |
| 4 | Connect your client | Every client, copy and paste |
| 5 | Check it worked | doctor, and what actually fails |
| 6 | Tools | All 36, grouped by what they reach |
| 7 | What Podcast Index actually does | The traps, learned the hard way |
| 8 | Your data | What is sent, and what never is |
| 9 | Writing safely | Short, because almost nothing writes |
| 10 | Troubleshooting | Symptom to cause |
| 11 | FAQ | Including what an MCP server is |
- When did they talk about pricing on that episode, and what did they say?
- Read me this episode and pull out the three claims worth remembering.
- Where has this person been a guest, and what do they always get asked?
- Find me fifteen podcasts about indie games that are still publishing, and skip the dead ones.
- Is my feed broken? Downloads dropped last week and I do not know why.
- What is trending in true crime this week, in Swedish?
- Which of this show's episodes actually have transcripts?
- Who does this podcast split its listener payments with?
- Give me the chapter list so I can see if this episode is worth two hours.
- Tell me everything about this show in one go: cadence, guests, health, the lot.
The first one is the point. Podcast Index will tell you a transcript exists and give you a URL. No podcast tool reads it back to you. This one does, which is why "when did they say that" is a question you can now ask.
Node 22 or newer. Nothing else.
npx -y @thenavidm/podcastindex-mcp-cli@latest --versionThat is the whole install. npx fetches it on demand, so there is nothing to
update later.
For the CLI as a command you or your agent can run anywhere, install it once:
npm install -g @thenavidm/podcastindex-mcp-cli
podcastindex-cliYou need a key and a secret. Both. The key says who you are and the secret signs each request, so one without the other cannot authenticate. They are free, there is no approval step, and it takes about two minutes.
The agent cannot sign up for you. What it can do is wire up the config once you have the credentials and verify the connection.
Paste this into Claude Code, Cursor, or any agent with terminal access:
Set up the Podcast Index MCP server for me.

1. Open https://api.podcastindex.org/signup and tell me to fill it in. Wait for me.
2. When I paste the key and secret back, add the server to my client config
   with PODCASTINDEX_API_KEY and PODCASTINDEX_API_SECRET set.
3. Run the doctor command and tell me what it says.
4. If the clock check fails, tell me how to fix the clock. Do not tell me to
   regenerate the key.
Step 1. Go to api.podcastindex.org/signup.
Step 2. Fill in the form. You need an email address and a line about what you are building. There is no review and no waiting: the credentials appear immediately.
Step 3. Copy both values. The key is short and looks like UXKCGDSYGUUEVQJSYDZH.
The secret is longer. Keep the secret private: anything holding it can spend
your rate limit.
That is it. Everything except adding a podcast to the directory works now.
You do not need write permission. Write access is a separate grant, and 34 of the 36 tools do not use it. Only
submit_feedandsubmit_feed_by_itunes_idneed it, and they say so if you call them without it. Skip this unless you actually want to add feeds to the public directory.
To revoke a key, contact Podcast Index through the support links on podcastindex.org.
The long version, every step with what to do when one fails, is in INSTALL.md.
claude mcp add podcastindex \
  -e PODCASTINDEX_API_KEY=your_key \
  -e PODCASTINDEX_API_SECRET=your_secret \
  -- npx -y @thenavidm/podcastindex-mcp-cli@latest
Add --scope user to make it available in every project rather than the
current one.
The short way: download the .mcpb extension
from the latest release and double-click it. It carries its own dependencies,
so there is no config file to edit and nothing to install first. Claude Desktop
asks for your API key and secret, and whether to run it read only.
The long way, if you would rather edit the config yourself:
| Platform | Config path |
|---|---|
| macOS | ~/Library/Application Support/Claude/claude_desktop_config.json |
| Windows | %APPDATA%\Claude\claude_desktop_config.json |
{
  "mcpServers": {
    "podcastindex": {
      "command": "npx",
      "args": ["-y", "@thenavidm/podcastindex-mcp-cli@latest"],
      "env": {
        "PODCASTINDEX_API_KEY": "your_key",
        "PODCASTINDEX_API_SECRET": "your_secret"
      }
    }
  }
}
Tip Claude Desktop does not inherit your shell PATH, so a bare
npxcan fail with "command not found". Use the absolute path fromwhich npxif it does.
Quit Claude Desktop completely and reopen it.
claude.ai runs connectors from Anthropic's cloud, not from your machine, so it needs a public HTTPS URL rather than a local command.
npx -y @thenavidm/podcastindex-mcp-cli@latest --http --port 8000Host that somewhere with a public HTTPS URL and set PODCASTINDEX_HTTP_TOKEN,
which the server requires before it will bind anything but loopback. A page from
another site is refused unless PODCASTINDEX_HTTP_ALLOWED_ORIGINS lists it. Then in
claude.ai: Customize, Connectors, +, Add custom connector, paste
the URL, Add.
On Team and Enterprise an owner adds it first under Organization settings, Connectors, then each member enables it.
.cursor/mcp.json, same JSON shape as Claude Desktop, key mcpServers.
~/.codeium/windsurf/mcp_config.json, key mcpServers.
.vscode/mcp.json. The key is servers, not mcpServers, and each entry
needs "type": "stdio".
{
  "servers": {
    "podcastindex": {
      "type": "stdio",
      "command": "npx",
      "args": ["-y", "@thenavidm/podcastindex-mcp-cli@latest"],
      "env": {
        "PODCASTINDEX_API_KEY": "your_key",
        "PODCASTINDEX_API_SECRET": "your_secret"
      }
    }
  }
}~/.codex/config.toml:
[mcp_servers.podcastindex]
command = "npx"
args = ["-y", "@thenavidm/podcastindex-mcp-cli@latest"]

[mcp_servers.podcastindex.env]
PODCASTINDEX_API_KEY = "your_key"
PODCASTINDEX_API_SECRET = "your_secret"~/.gemini/settings.json, key mcpServers, same shape as Claude Desktop.
Any stdio MCP client takes the same three things: the command npx, the args,
and the env block.
Or let the CLI write the entry, in each client's own format:
npx -y -p @thenavidm/podcastindex-mcp-cli podcastindex-cli install claude-codeIt takes claude-code, codex, claude-desktop, cursor, vscode or gemini, and --dry-run shows the change first.
Two are required. The rest have defaults that suit almost everyone, and are listed here so nobody has to read the source to find out what is tunable.
| Variable | Default | What it does |
|---|---|---|
PODCASTINDEX_API_KEY |
none | Your API key. Required |
PODCASTINDEX_API_SECRET |
none | Your API secret. Required, and never transmitted |
PODCASTINDEX_USER_AGENT |
podcastindex-mcp/<version> |
Identify your product to Podcast Index |
PODCASTINDEX_READ_ONLY |
0 |
1 hides the three tools that write |
PODCASTINDEX_ALLOW_DESTRUCTIVE |
1 |
0 keeps the recrawl ping, blocks the two submits |
PODCASTINDEX_AUDIT_LOG |
none | Path to an append-only log of every attempted write, and who approved it |
PODCASTINDEX_CONFIRM |
human |
model lets confirm: true alone approve over MCP, for an agent with no person to ask |
PODCASTINDEX_MAX_TRANSCRIPT_CHARS |
24000 |
How much transcript one call returns |
PODCASTINDEX_CACHE_TTL_MS |
300000 |
How long a response stays reusable |
PODCASTINDEX_REQUEST_TIMEOUT_MS |
30000 |
Per-request deadline against the index |
PODCASTINDEX_FILE_TIMEOUT_MS |
45000 |
Deadline for a transcript file on a publisher's host |
PODCASTINDEX_MIN_REQUEST_INTERVAL_MS |
120 |
Spacing between requests, to stay under the rate limit |
PODCASTINDEX_MAX_RETRIES |
3 |
Retries on rate limits and 5xx |
PODCASTINDEX_API_HOST |
api.podcastindex.org | Point at another host. A test seam, not a setting |
PODCASTINDEX_HTTP_PORT |
8000 |
For --http only |
PODCASTINDEX_HTTP_HOST |
127.0.0.1 |
For --http only |
PODCASTINDEX_HTTP_TOKEN |
none | Bearer token. Required to bind anything but loopback |
PODCASTINDEX_HTTP_ALLOWED_ORIGINS |
none | Comma-separated browser origins allowed to connect; a page from any other site is refused |
PODCASTINDEX_SURFACE |
full |
search lists three tools that find, describe and run the rest |
PODCASTINDEX_TOOL_TIMEOUT_MS |
none | Give up on any tool after this long |
PODCASTINDEX_DEBUG |
0 |
1 prints debug lines on stderr |
To disconnect, remove the entry from your client's config and restart the
client. There is nothing installed globally to uninstall, since npx fetches it
per run, and nothing on disk to clean up unless you configured an audit log.
npx -y @thenavidm/podcastindex-mcp-cli@latest doctorPodcast Index doctor
✓ Node.js v22.14.0
✓ Version podcastindex 2.0.1
✓ Writes on
✓ Tools 36 of 36 on
✓ Credentials configured
✓ API key set, 20 characters
✓ API secret set, 40 characters
✓ Podcast Index API reachable and authenticated, 4,312,880 feeds indexed
✓ Clock sync 2 seconds ahead, well inside the 180 second signing window
Ready.
The clock line is the one to read. See below for why.
The group worth installing this for. These leave Podcast Index and fetch files from the publisher's own host.
| Tool | What it does |
|---|---|
get_transcript |
Fetches and parses the transcript into timestamped text with speakers |
search_transcript |
Finds the moment a phrase was said, with a timestamp |
get_chapters |
The publisher's own table of contents, sponsor breaks included and labeled |
get_soundbites |
The clips the publisher marked as the best moments |
find_transcripts |
Which of a show's episodes have transcripts, in one request |
| Tool | What it does |
|---|---|
get_show_profile |
One call for cadence, guests, health, Podcasting 2.0 coverage and payments |
find_guest_appearances |
Every episode a person is credited on, grouped by show |
find_shows_to_pitch |
Shows on a topic that are alive, publishing, and worth approaching |
| Tool | What it does |
|---|---|
search_podcasts |
Keyword search across title, author and owner |
search_podcasts_by_title |
Title only, for when you know the name |
search_episodes_by_person |
Episodes crediting a named person |
search_music |
Music feeds, which are a separate medium here |
| Tool | What it does |
|---|---|
get_podcast |
One show, from any identifier you happen to have |
get_podcasts_batch |
Up to 500 shows in a single request |
get_podcasts_by_medium |
Browse audiobooks, film, video, courses, newsletters |
list_categories |
Every category and its id |
get_episodes |
A show's episodes, newest first |
get_episode |
One episode in full |
get_live_episodes |
Podcasts broadcasting right now |
get_random_episodes |
Random sampling, filterable by category |
get_recent_episodes |
The firehose of everything just published |
| Tool | What it does |
|---|---|
get_trending |
Trending shows, filterable by category and language |
get_recent_feeds |
Feeds that just published |
get_new_feeds |
Shows new to the index |
get_recent_soundbites |
The newest publisher-picked highlights |
| Tool | What it does |
|---|---|
get_value_block |
A show's payment split, with computed shares |
get_episode_value |
One episode's split, which can differ from the show's |
list_value_podcasts |
Every feed that takes listener payments |
get_new_value_feeds |
Shows that just added a payment split |
| Tool | What it does |
|---|---|
check_feed_health |
Crawl errors, parse errors, last good fetch, and a verdict |
list_dead_feeds |
Feeds the index gave up on |
get_index_stats |
How big the index is and how much of it is alive |
status |
What this server can currently reach |
| Tool | Needs |
|---|---|
notify_feed_update |
nothing, not even a key |
submit_feed |
your approval, and a key with write permission |
submit_feed_by_itunes_id |
your approval, and a key with write permission |
The things that will surprise you, and the reasons this server is shaped the way it is.
This is the one that costs people an hour.
Every request is signed with a SHA-1 of your key, your secret and the current unix timestamp, and Podcast Index accepts a three minute window either side of its own clock. A laptop that slept through a timezone change, a container with no time sync, or a VM restored from a snapshot will fail every single call with a 401.
A 401 reads as "bad credentials" to everybody, so the natural response is to regenerate a key that was never the problem.
doctor measures the drift against the server's own clock and says so. If it
reports skew, fix the clock, not the credentials. On macOS:
sudo sntp -sS time.apple.com| Tag | What it gives you | How common |
|---|---|---|
transcript |
a URL to SRT, VTT, JSON or HTML | uncommon |
chapters |
a URL to a chapters JSON file | uncommon |
person |
credited hosts, guests, producers | uncommon |
soundbite |
publisher-chosen highlight clips | rare |
value |
a payment split for listener payments | a small minority |
An empty result is a fact about that show, not a broken call. Nothing here can transcribe audio that was never transcribed, and retrying will not help.
This matters most for guest research. find_guest_appearances only sees shows
that publish person tags, so a thin result is a floor on somebody's appearances
and never a complete list.
The feed declares a mime type and publishers get it wrong constantly: SRT served
as text/plain, VTT declared application/json, JSON with an .srt extension.
So this server detects the format from the file body and treats the declaration as a hint. Trusting it would fail on a large minority of real shows.
Where a publisher offers several formats, JSON is preferred, because only the
Podcasting 2.0 JSON format carries real speaker names. The same episode as SRT
is usually an undifferentiated wall of text. Some SRT and VTT does carry
speakers, as a NAME: prefix or a <v Name> span, and those are parsed out.
transcriptUrl and chaptersUrl point at files on the publisher's own
server. So those tools fail for reasons that have nothing to do with the
index: dead links, moved files, HTML error pages, hosts that time out.
When a transcript fetch fails, the podcaster's hosting is down. The index is fine and the call was correct.
It says a show is configured to receive listener payments and names the wallets and their weights. It says nothing about whether anyone has ever paid.
Splits are relative weights, not percentages. A block of 90 and 10 is the same split as one of 9 and 1, so this server shows the computed share alongside the raw number.
Without the fulltext flag the API cuts every text field to 100 characters, and
a description cut at 100 characters still looks like a description. A model
reading one would summarize a show from its first sentence and never know the
rest existed.
This server sets fulltext on every call that accepts it. You will not hit this,
but it is why responses are larger than the raw API's.
It is unique only inside its own feed. Look one up without saying which show,
and the API answers with whichever it finds first, which is a coin flip. Pass
show alongside guid on get_episode.
Feed ids and episode ids are different numbers. A feed id will not work where an episode id is wanted.
submit_feed writes to a public global directory that hundreds of apps read,
and this API has no delete. Removing something means asking the people who
run Podcast Index.
That is why those two tools wait for your approval and notify_feed_update does
not.
There is no backend. Nothing is collected, and nothing is sent anywhere except the two places below.
| Goes to | What |
|---|---|
api.podcastindex.org |
your key, a timestamp, a signature, and your query |
| the publisher's host | a plain GET for a transcript or chapter file, no credentials |
Your secret is never transmitted. It is hashed into a signature locally and the hash is what travels.
Credentials live wherever your MCP client keeps its config, which is a plain
JSON or TOML file on your own machine. This server writes nothing to disk unless
you set PODCASTINDEX_AUDIT_LOG, and then only a line or two per attempted write.
Everything Podcast Index holds is public. There is no personal listening data here to leak, because the index does not have any.
Of 36 tools, 33 only read.
notify_feed_update asks the index to recrawl a feed sooner. It is idempotent,
needs no credential, and is not guarded, because guarding harmless things trains
the habit that makes real guards useless.
submit_feed and submit_feed_by_itunes_id add a podcast to a public directory
and cannot be undone through this API. Both wait for your approval.
Over MCP a person approves each submit where the client can ask: Claude Code
(2.1.246 and later) shows its own prompt, and a client that can show forms asks
with an approval form whose one box starts unticked. Each approval is signed,
bound to that exact call and works once. Where a client can do neither, the
model's confirm: true counts, and it should pass it only when you asked to add
that feed. PODCASTINDEX_CONFIRM=model makes confirm: true enough everywhere,
for an agent with no person to ask. In a terminal it is --confirm, which
--agent never adds.
| Variable | Effect |
|---|---|
PODCASTINDEX_READ_ONLY=1 |
the three write tools are not registered at all |
PODCASTINDEX_ALLOW_DESTRUCTIVE=0 |
keeps the recrawl ping, blocks the two submits |
PODCASTINDEX_AUDIT_LOG=<path> |
one JSON line per attempted write, allowed and blocked, and who approved it |
Read-only removes the tools rather than erroring on them, because a model cannot call a tool it cannot see, and an error is an invitation to retry differently.
On prompt injection. Transcripts, show notes and chapter titles are text strangers wrote, fetched from hosts nobody vetted, and anybody who can publish a podcast can put "ignore your instructions" into their own transcript. This server fences that text as data before a model reads it, and says so in its instructions.
That helps. It is not a guarantee. For an agent working unattended,
PODCASTINDEX_READ_ONLY=1 is the real defense.
Run doctor first. It tests every credential and measures the clock.
| Symptom | Cause |
|---|---|
| Every call fails with an auth error | Check the clock before the key. Three minute signing window, and drift is the most common cause |
doctor says the secret is not set |
Both halves are needed. The key alone cannot sign a request |
| A submit fails with a permission error | Write access is granted separately from a normal key |
get_transcript says the show publishes none |
Most shows do not. This is a fact about the show, not a failure |
| A transcript times out | The publisher's host, not the index. Raise PODCASTINDEX_FILE_TIMEOUT_MS |
| Transcript comes back with no speakers | The publisher supplied SRT without labels. Only the JSON format guarantees speakers |
find_guest_appearances returns nothing |
Only shows publishing person tags are visible, which is a minority |
| Rate limited | Use get_podcasts_batch and get_show_profile instead of loops of single calls |
Claude Desktop cannot find npx |
It does not inherit your shell PATH. Use the absolute path from which npx |
| "will not run without --confirm" | Working as intended: adding a feed cannot be undone. See section 9 |
claude -p will not submit |
Headless Claude Code refuses tools that need a person. Give that agent PODCASTINDEX_CONFIRM=model |
| A piped request gets no answer | Stdin closed before the answer. The MCP stdio binding stops a server when its input ends; keep stdin open until you read the answer, or use the CLI |
What is an MCP server?
An MCP server is a standard way to give an AI assistant real access to a tool, so it can act rather than guess. You install it once, your assistant gains the tools, and it works in Claude, Cursor, and anything else that speaks MCP.
Without one, an assistant asked about a podcast answers from whatever it absorbed in training. With one, it goes and looks.
What is the CLI?
podcastindex-cli is the same program as the MCP server, run as commands. AI agents that run commands, like Claude Code, Codex and OpenCode, use it on their own, and you can type the same commands in a terminal, a script or a cron job. Every tool is a command with dashes, so get_trending runs as podcastindex-cli get-trending.
Should I use the MCP server or the CLI?
Use the MCP server in an app with no terminal, like Claude Desktop's chat. Use the CLI anywhere commands run: an agent like Claude Code, Codex or OpenCode, a script or a cron job. The MCP server's tools take up context on every message, and the CLI costs nothing until it runs.
What is Podcast Index?
Podcast Index is an open, free directory of podcasts. Around four million feeds, run independently of Apple and Spotify, with an API anybody can use.
It is also where Podcasting 2.0 lives: an open extension to RSS that lets publishers attach transcripts, chapters, guest credits, highlight clips and payment details to their episodes. That extra data is most of why this server is interesting.
Do I need to be technical to use this?
Not in Claude Desktop: the .mcpb extension installs on a double click and asks
for your free key. Elsewhere you paste a block of JSON into a config file, and
step 3 walks through it. You can also hand the prompt in that section to an
agent and let it do the wiring.
Is my data sent anywhere? Who can see it?
There is no backend and no telemetry. Your queries go to Podcast Index, and transcript fetches go to the publisher's own server. That is all.
Your API secret never leaves your machine. It is used to compute a signature locally, and only the signature is sent.
What can it do that I cannot do on the website already?
Read transcripts. The Podcast Index website will show you that an episode has a transcript and link to the file. It will not search inside it, and it will not search across episodes.
The other one is scale. "Find every episode this person has been on, grouped by show" is one call here and an afternoon by hand.
Can it delete something by accident?
It cannot. Nothing here deletes anything, because the API has no delete.
The action worth knowing about is the opposite: submit_feed adds a podcast to
a public directory permanently, and there is no way to remove it through this
API. It waits for your approval for exactly that reason, and it needs a key
with write permission that you will not have unless you asked for one.
Does it cost anything?
It costs nothing. The server is MIT licensed and a Podcast Index API key is free with no approval step and no paid tier.
Does it work with ChatGPT or Cursor, or only Claude?
It works with any client that speaks MCP. Section 4 covers Claude Code, Claude Desktop, claude.ai, Cursor, Windsurf, VS Code, Codex CLI and Gemini CLI.
claude.ai is the one that works differently, because it runs connectors from Anthropic's cloud and needs the HTTP transport rather than a local command.
Why do I need two values instead of one API key?
Podcast Index signs every request rather than using a bearer token. The key identifies you and travels with the request; the secret is hashed together with a timestamp to prove the request is yours and is recent.
The upside is the secret is never transmitted. The downside is the timestamp
has a three minute window, so a drifting clock breaks everything. doctor
checks for it.
Why does an episode have no transcript?
Because the publisher did not attach one. Transcripts in podcasting are an optional RSS tag, and most shows do not use it.
Nothing here transcribes audio. If a show publishes no transcript,
get_transcript cannot produce one, and it will say so rather than guessing at
the content from the show notes.
Why does adding a feed ask me to approve it?
Because a feed added to Podcast Index stays there: this API has no delete, and
hundreds of podcast apps read the index. So submit_feed waits for you. Claude
Code shows its own prompt, a client that can show forms asks with one, and in a
terminal it is --confirm. An agent with no person to ask can be given
PODCASTINDEX_CONFIRM=model, which lets its own confirm: true count.
Asking the index to recrawl a feed with notify_feed_update needs nothing,
since doing it twice changes nothing.
How do I update it, or remove it?
With @latest in your client's config, npx fetches the newest version when
the client starts the server, so there is nothing to update by hand. A global
install updates with npm i -g @thenavidm/podcastindex-mcp-cli.
To remove it, delete its entry from your client's config and restart the
client, or run npm uninstall -g @thenavidm/podcastindex-mcp-cli for a global
install. It leaves nothing on disk unless you set an audit log.
Run into a problem or have a question? Open an issue and I will help.
Navid Moazzez is a leading AI business strategist, and the host of the AI Creator Summit, watched by 100,000+ creators. He helps creators and founders master AI and build their own AI Operating System (AI OS) to automate their business and life. He creates useful free tools, MCP servers and CLIs that creators and founders can use in their own workflows.
Links
- Personal website: navid.me
- YouTube: @thenavidm and @thenavidai
- X: @thenavidm
- Instagram: @thenavidm
- LinkedIn: thenavidm
If this is useful, star the repo and come say hi on X.
| Library | License | What it does |
|---|---|---|
| Slipway | Apache-2.0 | The MCP server and the CLI from one definition of each tool, with the write guard |
| MCP TypeScript SDK | Apache-2.0 | The MCP protocol, stdio and streamable HTTP transports, through Slipway |
| zod | MIT | Tool argument schemas and validation |
Data comes from Podcast Index, which is free and open. The Podcasting 2.0 namespace defines the transcript, chapter, person, soundbite and value tags this server reads.
Found a vulnerability? Report it privately, not as a public issue. SECURITY.md covers what this server can reach, the write-safety model, and running it over HTTP.
MIT. Free to use, modify, and share.
Not affiliated with, endorsed by, or connected to Podcast Index LLC.
© 2026 Navid Media. Made with ❤️ by Navid Moazzez.