
Gauge which parts of a text read as machine-written, and say why — with every finding anchored to the exact characters that carry it.
from ductus import gauge

report = gauge(open("draft.md").read())
report.document.label  # 'mixed-signals'
report.segments[3].lean  # +0.62  (-1 human … +1 machine)
report.segments[3].signals[0].note
# "a colon introducing a three-part parallel enumeration -- a textbook assistant construction"
pip install ductus
ductus gauge draft.md # a readable diagnosis
ductus gauge draft.md --format html --out report.html # shaded, hover for the reason
ductus gauge draft.md --format json # for a programIn palaeography the ductus is the characteristic manner and sequence of strokes by which a scribe's hand is recognised. This package looks for the equivalent in prose.
Every detector on the market emits a number like "87% AI". That number reads as a calibrated probability, is not one, and is how people get falsely accused. What you get here instead is three things you can argue with: a lean in [-1, +1], an evidence strength, and a coarse label. Behind each of them is a list of signals, each with a direction, a weight, the detector that produced it, a plain-language reason, and the exact span it came from.
Four things are true and belong in any report you make from this:
- Heavily-edited human writing and model-assisted writing look the same. Re-reading a hard message ten times sands off exactly the irregularity that marks it as human.
- Detectors over-flag non-native English writers — 61.3% false positives across seven commercial detectors on non-native TOEFL essays, against near-zero on native-speaker controls [1].
- Register contamination is real: people who read model output all day start writing like it, unassisted.
- No detector survives a motivated adversary, and that is a proven result rather than a gap in current tooling [2].
So this package describes text. It does not make claims about people, and it should not be used to.
It would be cheap to quote other people's numbers and not measure our own. Across 350 human-written texts with known proficiency levels, the shipped defaults call a document leans-machine — always wrongly, every text in that corpus was written by a person — this often:
| beginner | intermediate | advanced | native control | |
|---|---|---|---|---|
| per document | 2.3% | 10.0% | 10.0% | 2.0% |
| per sentence | 0.4% | 1.6% | 2.0% | 0.4% |
That is down from 20.6% overall, and the way it came down is worth knowing. Three rules were found to be matching nothing in machine-written text while implicating 86 human documents between them — two of them were simply broken, catching ordinary negation ("I did not eat from the tree but from the bush") and the everyday correlative ("not only fast, but also simple"). And the document-level verdict was rebuilt so that it stops treating accumulation as corroboration: a long document used to be more likely to be accused for being long. reducing-false-accusations.md has the per-rule table and what it cost (nothing: not one correctly-flagged machine segment was lost).
Two things still to take from it. A single flagged sentence is much better evidence than a flagged document. And the bias does not run the way the literature predicts: it tracks formal, fluent, essayistic writing rather than simple writing, because the deterministic detectors look for rhetorical constructions that good writers also use. What remains is concentrated in intermediate and advanced non-native writers, at 10%.
Four detectors ship, all deterministic, all free, none needing a model or a key.
| Detector | Finds | Example |
|---|---|---|
tells |
Catalogue phrases models overuse, tiered by confidence | "delve", "it's important to note", "In conclusion," |
forensic |
Mechanical traces of how the text was produced | a hard line break mid-sentence, mixed straight-and-curly apostrophes, trailing whitespace, em-dash density |
rhetoric |
Sentence shapes a phrase list cannot see | "not X but Y", a colon introducing a three-part parallel enumeration, concession-then-pivot |
rhythm |
Burstiness — how much sentence length varies | metronomic paragraphs |
Note that several of these argue for a human. A detector that can only ever accuse is not a measuring instrument. In practice the mechanical signals are often the most decisive thing in a file, in either direction.
The deterministic pass finds phrases, artifacts and a few shapes. It cannot find prose that is machine-written and bland — for that a model has to read it, which is what the shipped agent skills are for.
Two model-based detectors also ship, behind the [local] extra and off by default:
| Detector | Finds | Cost |
|---|---|---|
fast-detect-gpt |
Passages a language model finds markedly more predictable — or more surprising — than the rest of the same document | one CPU pass with gpt2 |
binoculars |
The same comparison, via the cross-perplexity of a paired observer and performer, which generalises better to unseen generators | two CPU passes with distilgpt2/gpt2 |
pip install "ductus[local]"
ductus gauge draft.md --detectors fast-detect-gpt,binoculars
They stay opt-in because they need torch and a model download, which the default must not. But if you have installed the extra, turn them on — at their default models. Measured against a second fixture whose machine text was not written to blend into its surroundings, they find 12 of 75 machine-written sentences at 86% precision where the deterministic set finds 0 of 75 — and they falsely accuse human writers far less often than the deterministic default does (6.3% of 350 human texts for binoculars, against 20.6%).
Do not assume a bigger proxy model is an upgrade. A stronger Binoculars pair was measured, found more machine text on both fixtures, and nearly doubled its false accusations on human writing — so the defaults stayed where they were. If you change model=, observer= or performer=, re-run python misc/measure_false_positives.py --pair-check for your pair. The numbers, including the unflattering ones, are in phase-1-results.md and phase-2-results.md; why a continuous score becomes a banded signal rather than a weight is curvature-as-evidence.md.
Note what they do not do: they compare passages within a document and so cannot say whether a whole text is machine-written. Answering that honestly needs a calibration this package does not have yet.
flowchart TD
  TXT["<b>text</b>"] --> SEG["<b>segmenter=</b><br/>paragraph · sentence · document"]
  SEG -->|"Spans — offsets + quote/prefix/suffix"| DET["<b>detectors=</b><br/>tells · forensic · rhetoric · rhythm<br/><i>opt-in: fast-detect-gpt · binoculars</i>"]
  DET -->|"Signals — direction · weight · reason · span"| AGG["<b>aggregate=</b><br/>lean · strength · label"]
  JUD["an agent's reading<br/><code>--judgments</code>"] -.->|"more Signals"| AGG
  AGG --> REP["<b>Report</b>"]
  REP --> MD["<b>to_markdown()</b><br/>a diagnosis to read"]
  REP --> HTML["<b>to_html()</b><br/>a page to hover"]
  REP --> JSON["<b>to_json()</b><br/>a structure to build on"]

  classDef seam fill:#fdf0dc,stroke:#d89a3f,color:#1a1a18;
  classDef out fill:#e9f1fa,stroke:#6f9ecb,color:#1a1a18;
  classDef plain fill:#f5f5f1,stroke:#b8b8ac,color:#1a1a18;
  class SEG,DET,AGG seam;
  class MD,HTML,JSON out;
  class TXT,REP,JUD plain;
The three amber boxes are the seams — each is one keyword argument. Everything below Report is a renderer, and renderers are pure functions of it: nothing in the analysis knows or cares which one you call, and adding a fourth changes nothing upstream.
One analysis, three outputs. Pick by who is reading.
| Renderer | CLI | Output | Reach for it when |
|---|---|---|---|
to_markdown(report) |
ductus gauge draft.md |
A synopsis, a table of flagged segments, then a Why section quoting each signal and its reason | A terminal, a PR comment, a document, an agent that needs to reason about the result in prose |
to_html(report, text=…) |
--format html --out report.html |
One self-contained file — no build step, no CDN, no network | You want to see where the evidence is, and read why without losing your place |
to_json(report) |
--format json |
The full structure: every span, signal, weight and reason | A frontend, a pipeline, a calibration run, anything that is not a person |
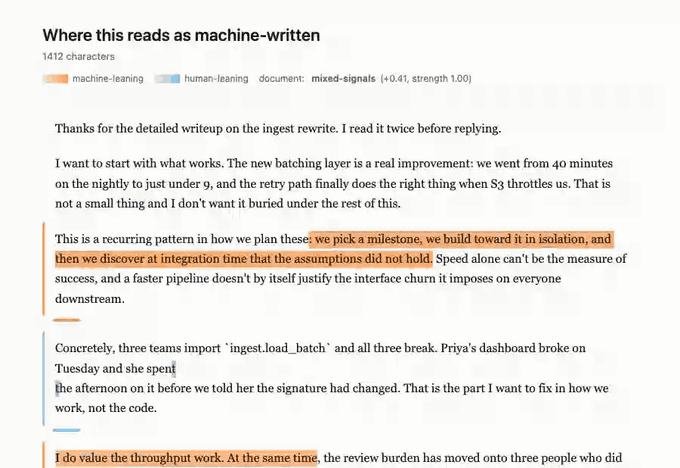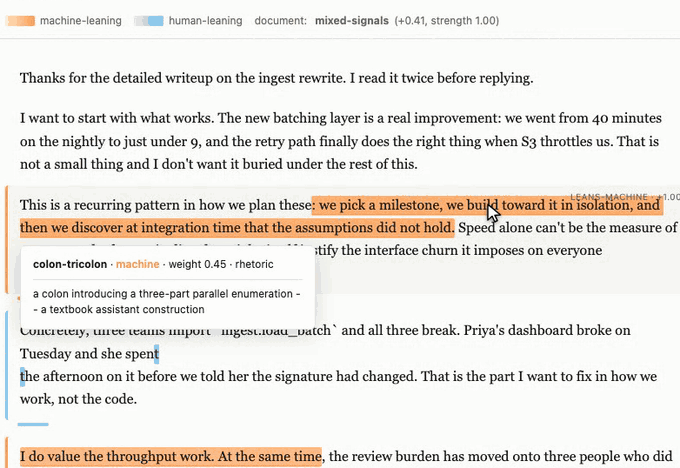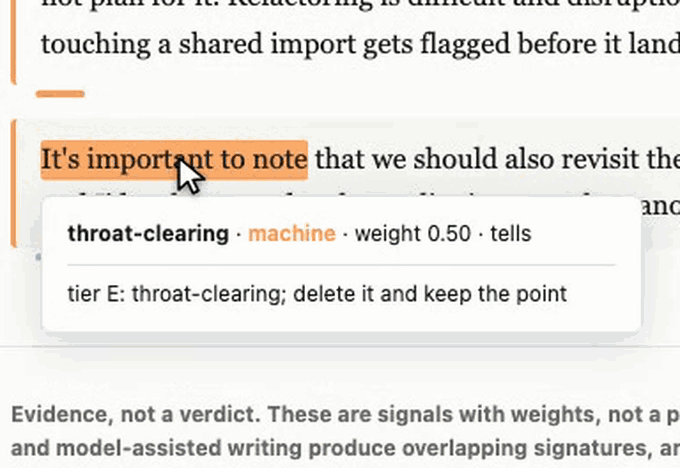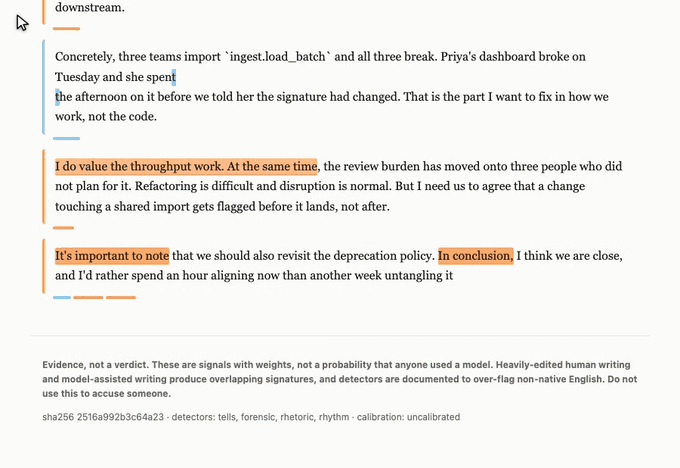
Hover (or keyboard-focus) any highlight and the reason appears beside it — which detector fired, which direction it argues, and what it weighs. Paragraphs carry a left border and a lean badge; the bar under each one is its evidence, one segment per signal.
Two deliberate choices, both from the annotation-systems research in misc/docs/research/:
- Hue encodes score, and only score. A perceptually-uniform ramp, warm for machine-leaning and cool for human-leaning, with lightness re-clamped per theme so it works in light and dark mode. Overlap is shown structurally, in the lane under the paragraph, never by blending colours — stacking translucent fills is what makes overlapping highlights unreadable.
- The reason is anchored to the highlight, not parked in a corner, so the eye does not have to leave the text to find out why. Below 640px it falls back to a bottom sheet.
The GIF above was recorded with walkthru driving a real browser — the script is misc/demo/make_gif.py, and it is the whole pipeline: measure where the highlights are, build a demo document whose camera zooms to them, play it against a recording page, render the capture to a GIF.
The primary surface. Two skills and a subagent ship inside the package and install with one command:
ductus install-skills --write # links them into ~/.claude/skillsductus— what may and may not be claimed from a text, and which task is which.ductus-gauge— the full reading: the deterministic scan, then a judgment pass with rubrics for the nine machine-leaning and six human-leaning shapes that regular expressions miss, then the write-up.ductus-reader(subagent) — does the whole reading in its own context and returns a finished diagnosis.
An agent's own reading folds back in beside the deterministic signals, anchored by quote:
ductus gauge draft.md --judgments judgments.json --format html --out report.htmlA quote that no longer occurs is dropped rather than mis-anchored, so re-running after an edit is safe.
The same verbs the CLI dispatches, as MCP tools:
pip install "ductus[mcp]"
ductus-mcp # stdio, for a local agent hostgauge, detectors, segmenters and tells. install_skills is deliberately absent: it symlinks into an agent host's skills directory, and a person typing that at a CLI chose to in a way a remote caller did not.
There is no second verb list. ductus.mcp.TOOL_REFS is derived from the one list the CLI already dispatches, so the two surfaces cannot drift — and a verb that changes the host declares that at its own definition rather than by appearing in some other list. middleware= and auth= pass straight through mk_mcp() for a deployed server.
The same verbs again, over HTTP:
pip install "ductus[http]"
ductus-http                   # http://127.0.0.1:8000, and /docs for the OpenAPI UI
curl -s localhost:8000/gauge -H 'content-type: application/json' \
-d '{"source": "Great question! Let us delve in.", "format": "json"}'Same rule as MCP, one layer further: ductus.http.ROUTED_FUNCS is derived from the CLI's list, so a third surface still means no second implementation and no parity test. The typed TypeScript client the frontend imports is generated from this app's own OpenAPI (ductus.http.export_client()), so a changed Python signature becomes a TypeScript type error rather than a runtime surprise.
This surface found something the other two could not. gauge(source=...) reads a file when the string names one, and gauge(out=...) writes one. That is exactly right when you typed the command yourself — and an arbitrary file read and an arbitrary file write when the caller is a stranger. Neither the CLI nor a local stdio MCP host can see it, because on those surfaces it is not a bug. The verbs now declare which of their parameters address the filesystem (@host_paths(source="read", out="write"), a sibling of the existing @host_mutating), and the HTTP adapter refuses them by reading that declaration rather than by knowing anything about gauge. mk_app(guard_host_paths=False) turns it off for a loopback service you run for yourself.
An example frontend lives in frontend/ — paste a text, read it, edit it, read it again, with every finding anchored to the characters that carry it.
pip install 'ductus[http]'
cd frontend && npm install && npm run build
ductus-http                     # serves the UI and the API from one origin
Three things decide its design, and the first two are correctness rather than taste:
- The editor does not tidy the text. A normal rich-text editor turns
'into’, trims trailing whitespace and collapses lone newlines. This package reads all three as evidence, andmixed-apostrophesandtrailing-whitespaceargue for a human. An editor that quietly normalised the text would be deleting the evidence that exonerates people. So the ProseMirror schema is one whitespace-preserving block, which also makes a plain offsetoexactly positiono + 1. - An edit invalidates, it never re-anchors. Positions are kept exact through every keystroke (ProseMirror's
Mapping); validity is not inherited. A finding whose text has changed goes hatched and reads "unverified" until you read again — re-attaching an old score to new text is a false claim, not a stale cache. A finding is invalidated when the edit touches its characters or anywhere in its segment, because segment scores are per unit of text; the document verdict is invalidated by any edit at all. - The TypeScript is generated from the Python.
frontend/src/generated/client.tsfrom the service's OpenAPI,report.tsfrom the dataclasses inbase.py.tests/test_generated_sources.pyfails if they drift, so a renamed field is a failingpytestrun rather than anundefinedin a browser.
The stack is Vite + TypeScript + ProseMirror and deliberately no framework, no state library and no persistence. Why, and what each of those costs, is in misc/docs/frontend-stack-decision.md.
The interface holds the same line the reports do. No percentage anywhere. The measured false-positive rate sits beside the verdict rather than in a footer, loudest in the one case where the verdict is a claim about a person — because an interface makes a verdict feel authoritative in a way a paragraph does not, and the person most likely to be wronged by this page is the careful essayist whose prose it just lit up.
Three, each one keyword argument, each defaulting to something that genuinely works:
gauge(text, segmenter="sentence")  # or "paragraph", "document", or a callable
gauge(
    text, detectors=["forensic", "rhetoric"]
)  # or your own (text, span) -> Iterator[Signal]
gauge(text, aggregate=my_scorer)  # (signals, *, n_chars) -> (lean, strength, label)
The aggregate= default is density_aggregate, which divides evidence by how much text produced it: two stray signals mean something different in 600 characters than in 3000. The length-blind aggregate it replaced is still exported, and the measurement that chose between them is in phase-2-results.md — it cut false accusations on human text from 34.3% to 20.6% at no measured cost in findings.
A detector is a plain function (text, span) -> Iterator[Signal]. Fast-DetectGPT and Binoculars are exactly that and nothing more — ductus/curvature.py adds no base class, no core change and no import cost. A vendor API would be one more function of the same shape; see the roadmap.
DETECTORS is the registry of everything nameable; DEFAULT_DETECTORS is what detectors=None means. They are deliberately different lists — a detector joins the default by beating what is already there on tests/fixtures/mixed_authorship.json, which python misc/measure_detectors.py measures.
For long documents, iter_segments is the streaming core and gauge is the batch facade over it.
Every Span carries character offsets and the W3C Web Annotation redundant selectors (quote, prefix, suffix), because plain offsets do not survive an edit to the text. That is what lets a viewer re-find a finding after the document changed, and what a future edit-and-re-score UI is built on.
ductus is the read side: where does this text read as machine-written, and why. acquaint's deslop is the write side: make my draft not read that way, in my voice, calibrated to this reader. They share this package's tells catalogue — acquaint imports it — and compose naturally: gauge, deslop the flagged spans, gauge again.
They are separate packages because they have different inputs. deslop needs a model of the reader; ductus must work on a stranger's text with nothing but the text.
pip install ductus              # the core: pyyaml and cw, nothing else
pip install "ductus[local]"     # + Fast-DetectGPT and Binoculars: offline, no API key, opt-in
pip install "ductus[api]"       # + vendor detector adapters
pip install "ductus[mcp]"       # + the MCP server (`ductus-mcp`)
pip install "ductus[http]" # + the HTTP service (`ductus-http`) and its typed client[3] Sanderson R, Ciccarese P, Young B. Web Annotation Data Model. W3C Recommendation, 2017.
[4] Tolstykh I, et al. LLMTrace: A Corpus for Classification and Fine-Grained Localization of AI-Written Text. arXiv:2509.21269. — the ground-truth fixture in tests/fixtures/ is a slice of this, Apache-2.0.