






Simulation Platforms · Dexterous Manipulation Simulation
Physics Solvers · World Models


I’m a Robotics Simulation Engineer at GENISOM AI in Beijing, building platforms that bring together physics simulation, rendering, sensor models, and robot control. Previously, I worked on production autonomous driving simulation for Baidu Apollo.
My background is in numerical modeling of physical systems. I hold a master’s degree in Petroleum Engineering from China University of Petroleum, where I developed physics-guided surrogate models for reservoir simulation, using neural networks and mass-balance principles to predict how fluid distributions evolve over time.
I’m currently exploring world models, with a particular interest in how agents learn from physical interaction in tasks such as dexterous manipulation.

Turns new arXiv and Hugging Face papers into a prioritized reading queue, with critical reviews and linked Markdown notes in English or Chinese.

A bilingual guide for finding and comparing community reproductions and extensions of SuperMimic, with direct links to code, reported results, and documented limitations.
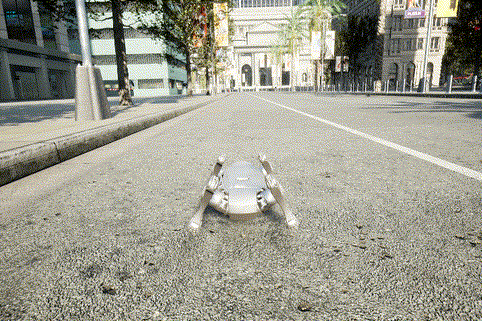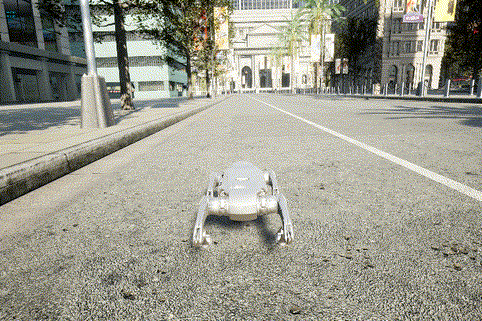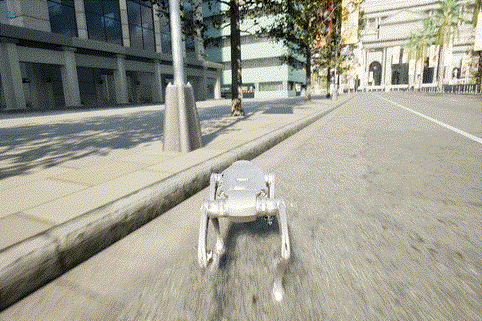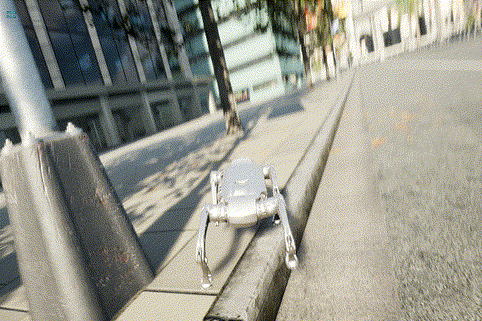

An integrated robotics simulation platform combining Unreal Engine 5 rendering and MuJoCo dynamics, configurable robot models, calibrated sensor simulation, motion control, and ROS 2-compatible communication for robot development and evaluation.
MATRiX · Town10 navigation

At DexLab, I build a physics-centric research platform for contact-rich manipulation around Simulation–Learning Co-evolution: let robot models expose simulator gaps, then use the improved simulator to train better models.
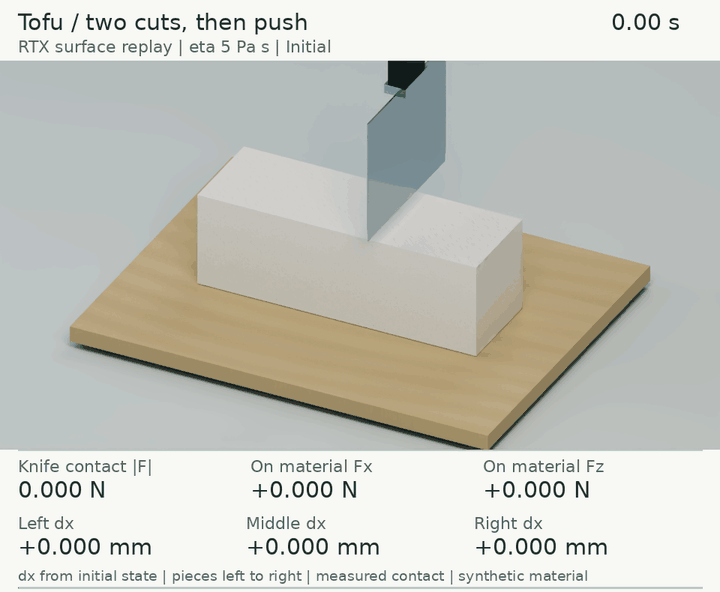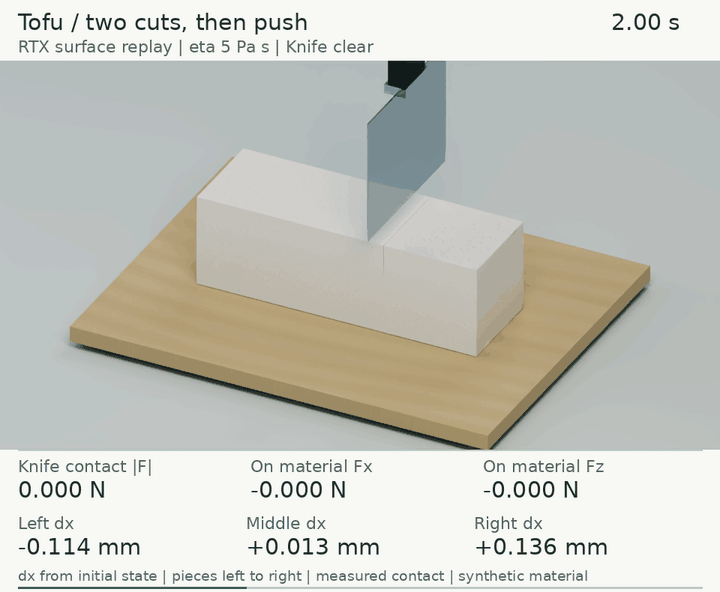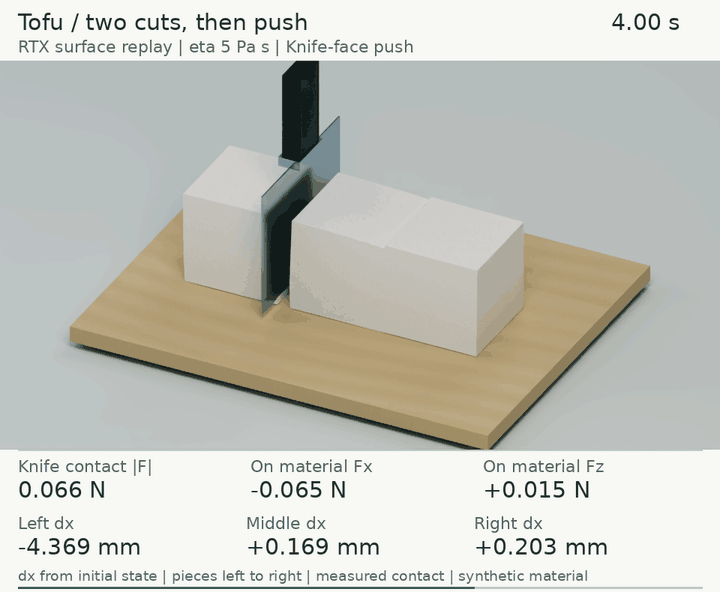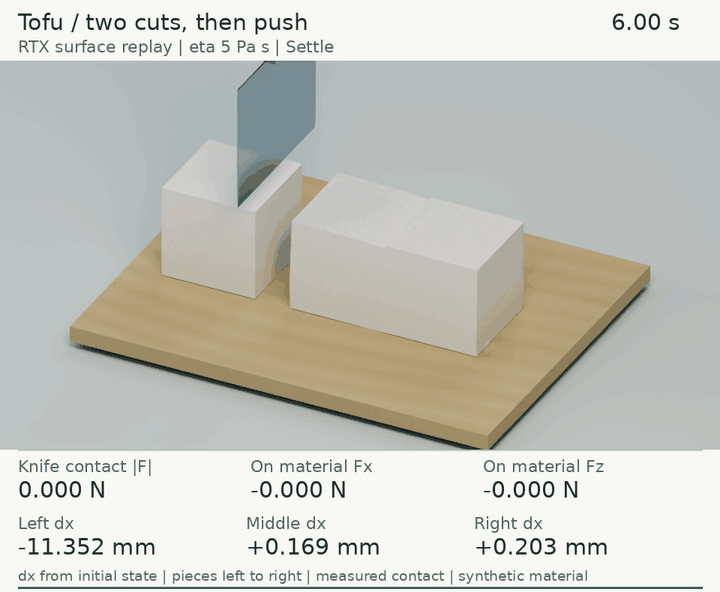
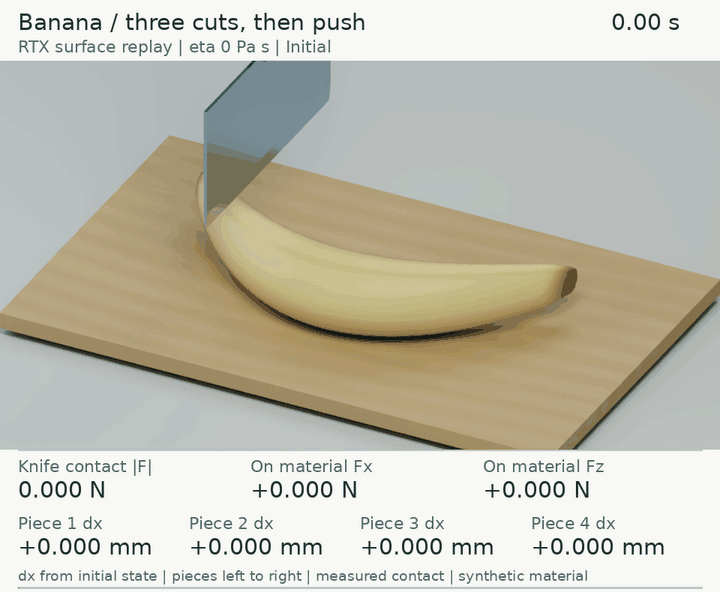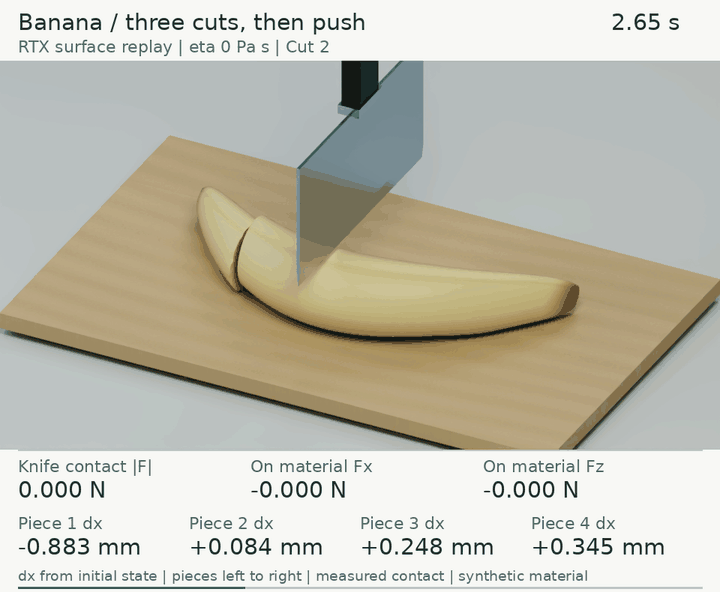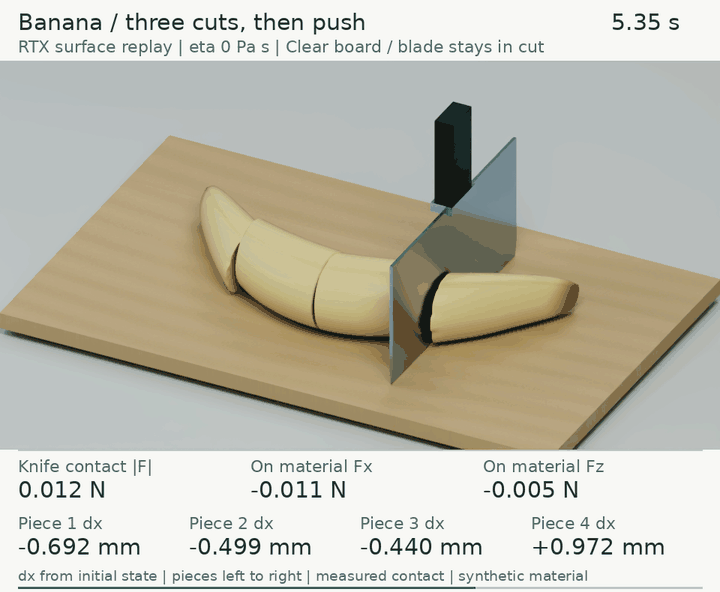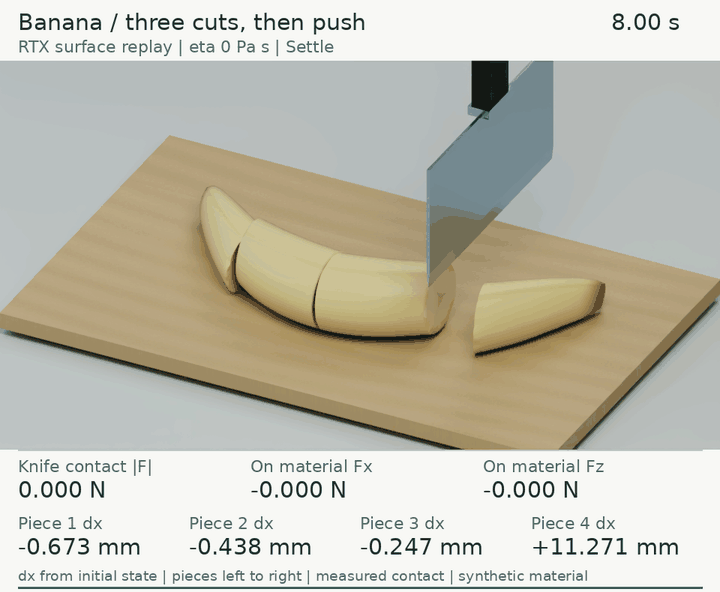
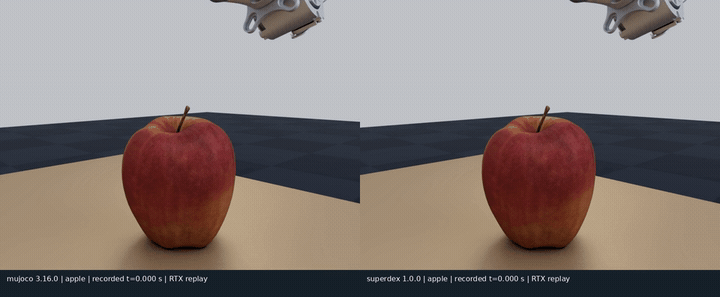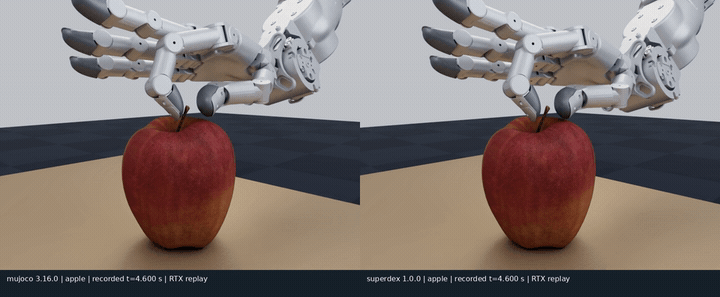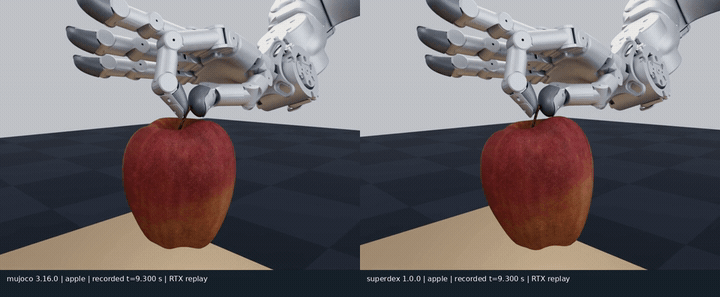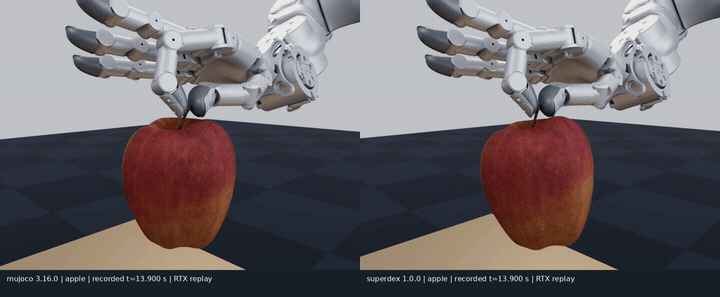
DexLab joins reproducible experiments in grasping, cutting, wiping, and deformable-material interaction with task protocols, RoboAPI/VLA/world-model systems under test, action execution, and independently recorded evidence. Native-physics experiments span MuJoCo, SuperDex, Genesis, Newton Physics, PhysX, and Drake; Uranus is documented as a generative-backend candidate rather than an operational runner.

DexLab execution and evaluation architecture · task thumbnails indicate categories; recorded task evidence follows below.
|
Wuji grasp and contact switching 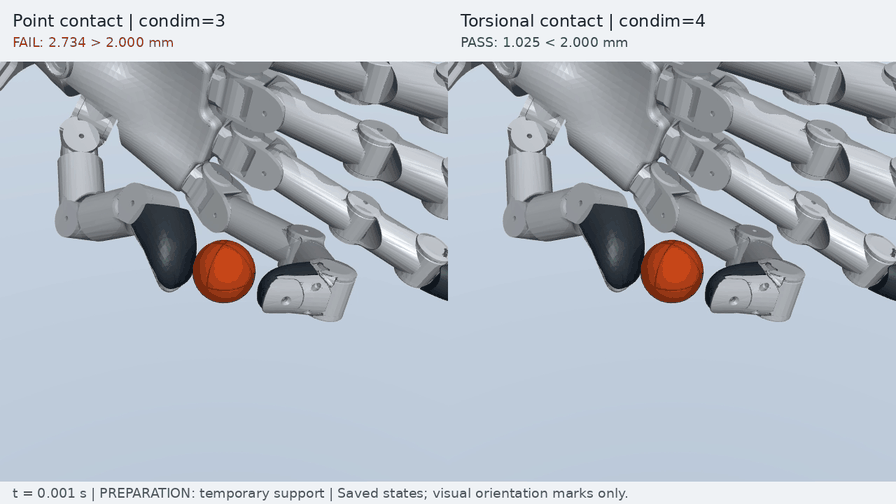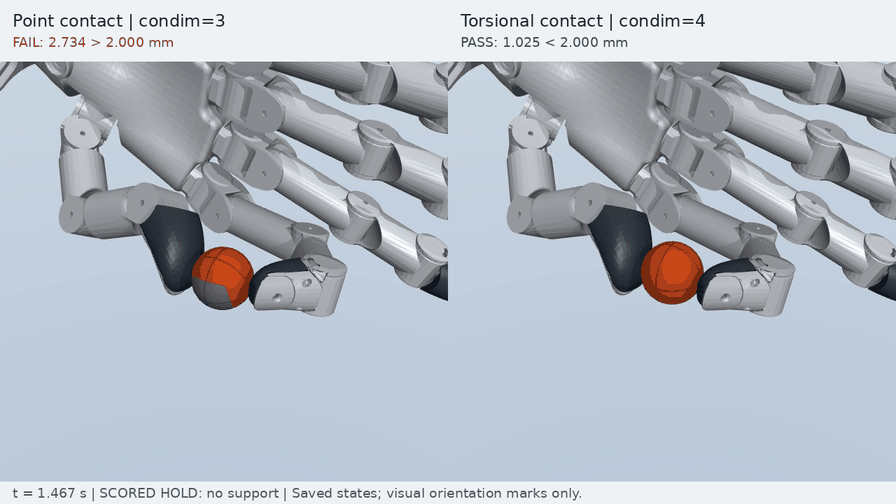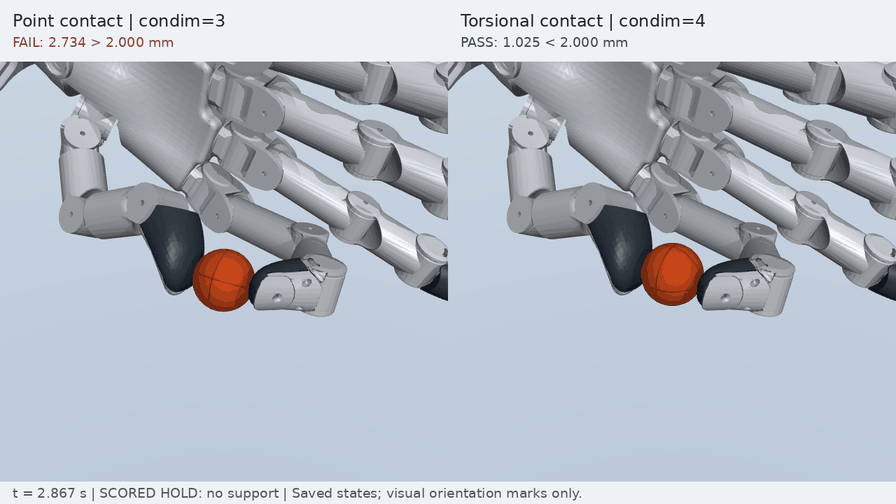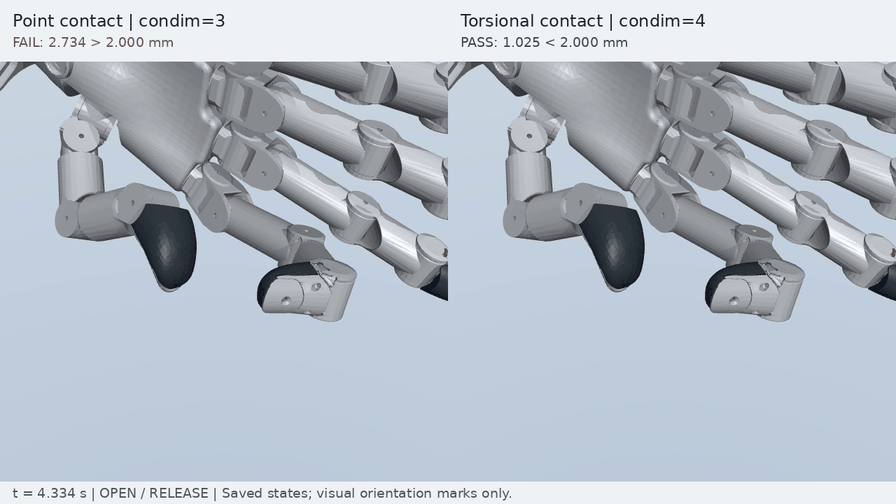
|
|
|
|

|
|
|
|
More experiments · Task and solver coverage
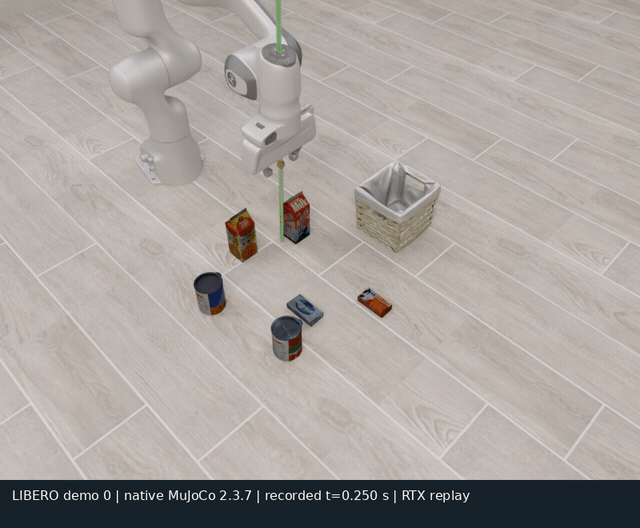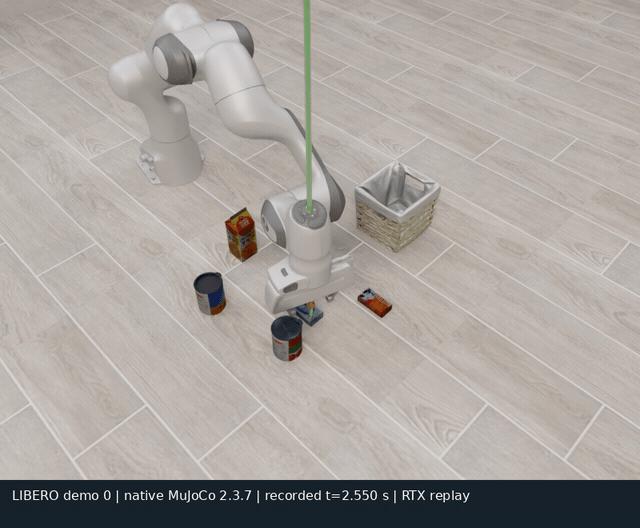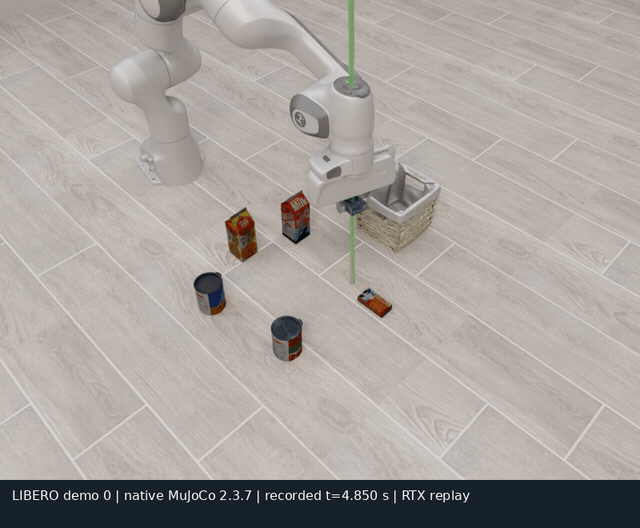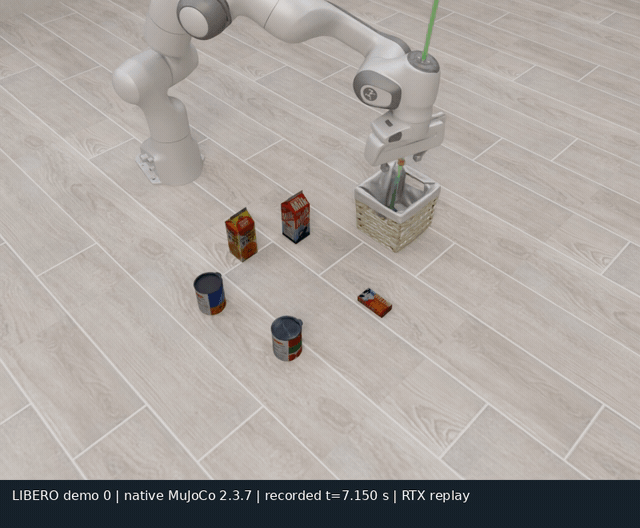
Recorded simulation replays · Sources and rendering details.

Our action-conditioned JEPA world model combines latent prediction with state alignment (SA) and inverse dynamics (IDM) losses. SA trains a head to predict measured physical states from consecutive latent representations, encouraging the encoder to retain physical configuration and motion. IDM provides complementary supervision by predicting executed actions from latent pairs. Physical states are used only for training supervision. At deployment, GAWM plans toward visual goals with CEM in latent space, without reconstructing future images.
Toward Physically Grounded JEPA World Models for Goal-Conditioned Robotic Planning
Accepted to the IROS 2026 Workshop on Physical World Models for Scaling Embodied AI.
Paper · Code · Model Checkpoints

GAWM model architecture · Figure 1 from the paper
I welcome discussions and collaboration on robotics simulation platforms, dexterous manipulation simulation, physics solvers, and world models.