Repository navigation
Features Admin
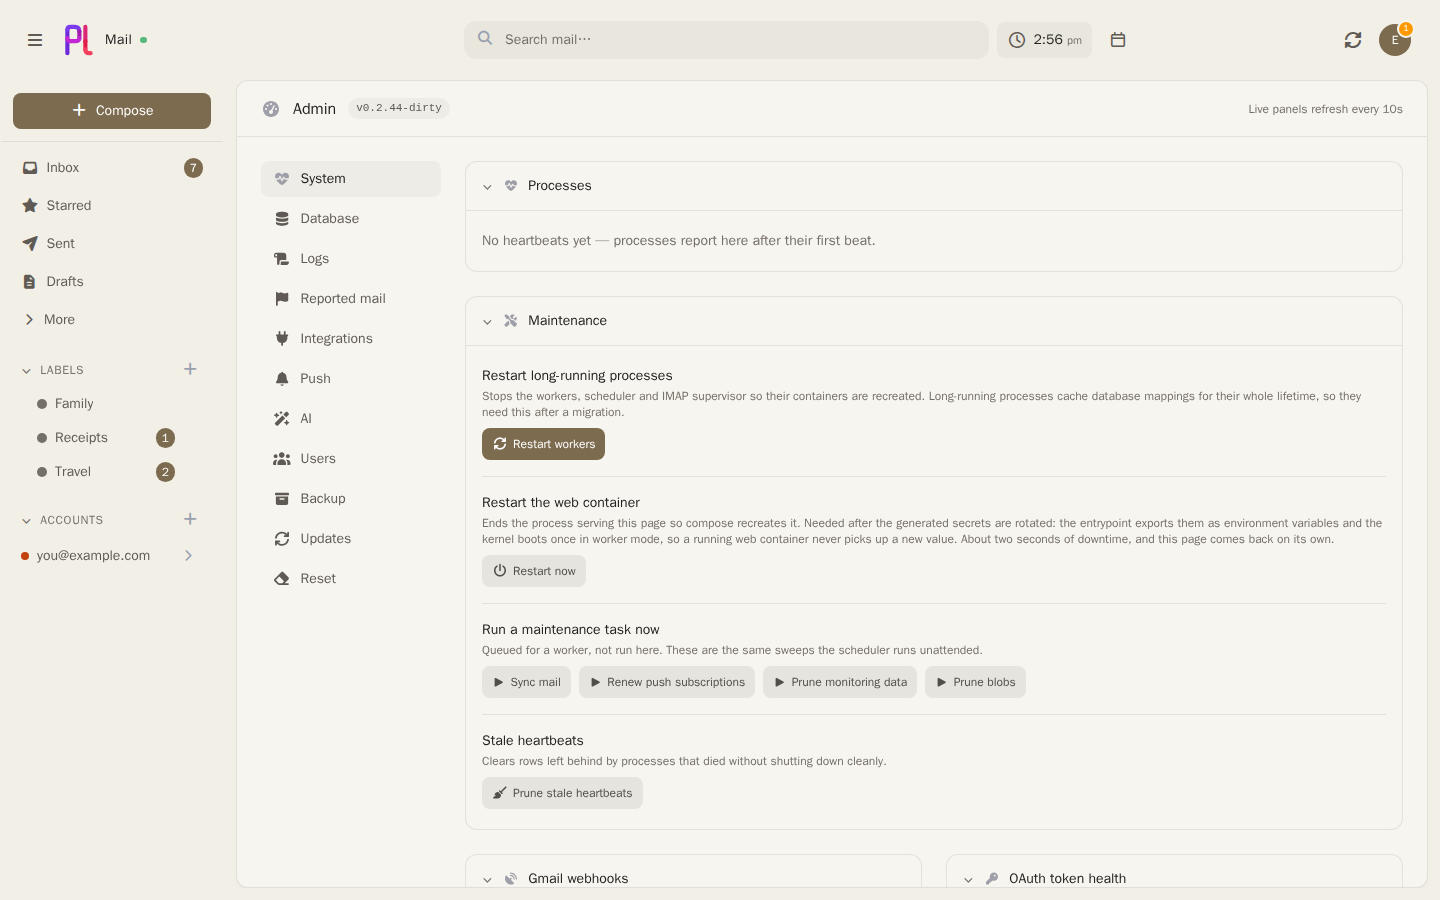
Signed in as an administrator, Admin in the user menu opens a panel that says what the instance is doing. It is six sections: System, Database, Logs, Integrations, Users and Reset.
Nothing here reads anyone's mail. Being an administrator grants the panel, the user list and the provider configuration, and nothing else — no route in this area touches an account or a message.
The panel header carries the build: the release it was built from, and the short commit beside it. It sits in the header rather than in a panel because the question it answers — is this the build I think it is? — is asked while looking at something else.
It is baked in at build time rather than read at runtime; a container has no .git to ask. A
checkout that was never built from a tag falls back to git describe, and where nothing knows the
answer the chip is absent entirely rather than reading "development" beside every page.
Two images can both call themselves main, which is why the commit is shown next to the label and
not instead of it.
Live panels, refreshed every ten seconds. Each can be collapsed, and a collapsed card shows a one-line summary in its header — 3 healthy, 2 running · 41 waiting — short enough to read at a glance and specific enough to be worth expanding for. Which cards you collapsed is remembered server-side, so the page never flashes every panel open before folding them.
| Card | What it shows |
|---|---|
| Processes | Every long-running process that has reported a heartbeat, with type, instance, PID and last beat |
| Maintenance | The verbs — restarts, one-off tasks, pruning |
| Gmail webhooks | Per Gmail account: watch state, expiry, history id, last push, and the delivery path |
| OAuth token health | Refreshes recorded, and tokens nearing expiry |
| Messenger queues | What a worker is holding right now, over the backlog |
| Failed messages | The failure transport, with retry and delete |
| Accounts | Per account: threads, messages, last activity |
| Table sizes | The biggest tables in the database |
The one to read when mail stops arriving. Running now names the messages a worker is holding at this instant — the handler, its payload, and how long it has been held — over a searchable list of everything still waiting. A queue that is stuck therefore looks different from a queue that is empty, which is the distinction that matters.
The backlog pages twenty-five at a time and fetches more as you scroll, and the filter runs over the whole queue rather than the page on screen. It has its own endpoint, so searching does not re-render every other panel per keystroke.
Restart workers asks every long-running process to exit; Compose's restart policy brings them back, and in-flight work finishes first. The reason it exists: a worker caches Doctrine metadata for its whole lifetime, so after a migration it can keep querying columns that no longer exist until something restarts it.
Restart now is the other half — the container serving the page you are on. The worker restart cannot reach it, because its mechanism is a timestamp a worker loop rechecks and the web process has no such loop. The usual reason to want it is a rotated secret, which an already-booted kernel has no opportunity to re-read. It costs about two seconds of downtime and the page comes back on its own.
Run a maintenance task now offers four buttons: Sync mail, Renew push subscriptions, Prune monitoring data and Prune blobs. Each is queued for a worker rather than run in the request. These four and no others, because they are the ones the scheduler already runs unattended, which is what proves them safe to expose as buttons.
Prune stale heartbeats clears rows left by processes that died without shutting down cleanly — the ones that would otherwise sit red in the Processes card forever.
The failed-message card adds Retry all and Purge all, both confirmed.
None of these answers with a message. Each redirects back and the panel's own refresh shows the result: the queue depth rises, failed rows disappear, heartbeats come back. The exception is the worker restart, which has no visible effect, so the panel renders a banner saying how long ago it was asked for — a restart clears heartbeat rows rather than reddening them, and rows vanishing is expected rather than an outage.
How long things take, as opposed to whether they are working — which is what System is for. Nothing here refreshes by itself: it is a record, read a row at a time. Period switches between the last hour, 24 hours and 7 days.
How late mail arrives. Per account, the time between the provider accepting a message and plMail storing it. Seconds means the provider is telling plMail about new mail as it lands — IMAP IDLE, Gmail push, a Graph subscription. A typical delay of five minutes or more is highlighted: that account is living on the quarter-hourly poll, which "works" and is why nothing else on any page would tell you. Mail brought in by an import is not counted, nor is mail sent from plMail itself.
The three delay figures are of mail that landed in the inbox, because that is the only mail a provider announces. Spam, and mail a filter filed somewhere else, waits for the schedule by design; Not in the inbox gives its count and typical delay separately so that it does not read as a push that is failing.
The delay is measured from the provider's own record of taking delivery, not from the date the message carries. That date is the sender's: a newsletter dated half an hour before it was sent used to be shown as plMail being half an hour late.
Under the accounts, The slowest in this period lists the slowest messages one to a row. It is closed until you click it, and closed again the next time the page loads:
| Column | What it is |
|---|---|
| Reached the provider | When the provider accepted the message |
| Filed in | Inbox, Spam or Elsewhere — where it was when it arrived, not where it is now |
| Brought in by | What made plMail fetch it: Push, IDLE, the Schedule, or somebody pressing the Sync button. A dash for mail stored before this was recorded |
| Already under way for | How much older the message's own date is than the moment the provider had it. A sender that queued it or dated it early; nothing plMail could have shortened |
| Then until plMail had it | The delay itself. Highlighted when inbox mail took five minutes or more, which is an announcement that never came |
Inbox mail brought in by the Schedule on an account that has push is the row to look for. Like the rest of this page, the rows say nothing about what was in the mail: no subject and no sender.
What each worker has waiting. The queue numbers from System, arranged by the process that
handles them: how many jobs are waiting, how long the oldest has waited, and how long the job in
hand has been running. A worker with two queues finishes the first before it looks at the second,
so enrich_backlog waiting an hour beside an empty enrich is the design and not a fault. This
panel is a reading of the moment, with its own Refresh — how long a job waited is not kept once
it has been handled.
Model host. What the language model's host is doing: whether it answers, which models are in memory and whether they fit on the GPU, and the recorded calls per feature — speed, errors and how often a model had to be loaded first. It moved here from AI, where the search index backfill stayed, because that one has Start and Pause on it. It refreshes itself and has its own period switch.
New mail waiting for the assistant. If somebody lets the assistant sort their mail, new mail is kept out of the inbox tabs until it has been sorted (see AI below). The line under that switch says how long the wait typically is. This panel says why a particular one was not typical. Each row is one held message:
| Column | What it is |
|---|---|
| Shown after | How long the message was kept back |
| Queued | From the mail being stored to the assistant being asked. Large means the worker was busy with something else |
| Model call | The round trip to the model host |
| of it loading | The part of that call the host spent loading the model into memory. Near zero on a model that was already loaded; highlighted when it was a second or more |
| Filed under | The tab it ended up in |
| What happened | Sorted and then shown; shown first and moved when the answer came; or shown without an answer |
A row with a large of it loading is the usual explanation for one slow message among fast ones: the model had been unloaded since the last mail. Raising Keep the writing model loaded for under AI is what addresses that. A large Queued points at the worker instead.
Rows name the account and nothing else. What was in the mail is not shown here, or anywhere in the admin panel. Mail sorted before 0.3.1 has no durations and shows a dash.
Connection counts, cache hit ratio, deadlocks and rollback ratio, plus the slowest statements by mean time (anything averaging 5 ms or more) and the heaviest by total time, and what is running right now.
The aggregation needs PostgreSQL's pg_stat_statements, which app:db:migrate enables at boot. If
the database role was not allowed to create the extension, the panel says so and offers Enable it
now. Statistics start from the moment the extension is created, so queries from before it will
never appear. Reset stats clears the collected numbers.
A filterable browser over what plMail has written to the database: a minimum level — info, notice, warning (the default), error or critical — and a channel, a hundred entries per page, with a copy button per entry.
How much reaches the database at all is Keep entries at, the second row of the panel. It is a
different question from the filter above it: the filter narrows what is shown out of what was
stored, this decides what gets stored. Lowering it to info is what makes successful Gmail push
deliveries visible, for instance, or the image proxy's reasons for refusing a remote image; both are
logged at info and otherwise not written down at all.
The change applies to the next request immediately and to background workers within about ten seconds — they each hold the answer briefly rather than asking the database on every line.
APP_DB_LOG_LEVEL is still the default, and an install that never touches this control keeps
following it, including a later change to it. Choosing from the environment in the dropdown is
how you hand it back after setting a level here — which is not the same as picking today's value out
of the list, because that would freeze it.
Clear deletes the entries matching the filter currently on screen — what disappears is what you were looking at.
Reference finds what one request logged. When a request fails in the browser, plMail leaves the
page as it was and shows a toast instead — "Something went wrong on our side", say — ending in a
short reference like Ref. 2a4109f7. Typing those eight characters into the field lists that
request's entries and nothing else, which is quicker than matching clocks. The same reference is in
the X-Request-Id header of every response; a proxy that sends its own request id keeps it. While a
reference is set, Clear is not offered: it deletes by level and channel, and would take more than
is on screen.
Anything at warning or worse that no administrator has read outlines the user menu on every page, amber for warnings and red for errors, with a count. Opening the log browser is what marks them seen, and the mark is set from the moment it was opened rather than from the newest entry on screen, so anything logged while you were reading is still genuinely unread.
The outline is shown to administrators only. For anyone else it would be an alarm about something they are not allowed to look at.
Expanding an entry shows its context as JSON, and Copy puts the whole thing — time, level, channel, source, message and context — on the clipboard in one piece, which is what makes an entry worth pasting into a bug report.
When the entry came from an exception, the context carries its class, message, code, file, line and stack trace, followed by the chain of previous exceptions underneath it. That chain is usually where the real cause is: a database wrapper reports "an exception occurred while executing a query" and the exception beneath it names the constraint. Entries produced by a web request also record the request's method, path and route name, so a fault can be tied to the page that caused it.
Two things are deliberately left out, and both are about not turning an admin page into a place secrets accumulate:
- Stack frames carry no argument values. A frame is recorded as its file, line and function, and nothing else. The arguments a frame received are the plaintext password on a sign-in path and the message body on a mail one.
-
Query-string values are not recorded — only the parameter names. That a request carried a
qis what tells you a search ran, which is the question worth answering; what somebody searched for is their business, and the administrator reading this is not always the person who typed it.
Unlike the System panels this section does not auto-refresh — reading a stack trace should not get yanked away mid-scroll.
Its own card below the log, because it holds a different kind of thing. A server error is one event in one request; a broken line in a script runs on every page load for every user, so a row here is a distinct fault — message, file and line — with a count and a first- and last-seen time, rather than one row per occurrence. Merged into the log above, a single bug would be four hundred rows and the log would be unreadable.
The count is how many page loads hit the fault, not how many times it fired: the browser reports each distinct fault once per page, which is what stops one broken line inside an animation frame from posting a thousand requests about itself. It is the more useful number anyway — it says how many people are running into it.
Most of what a browser reports is not plMail. Extensions inject analytics and form scrapers into
the page and those scripts throw; a panel that accepted all of it would fill with other people's bugs
and stop being read. So a report is kept only when it can be attributed to a script this server sent
— an injected script has no URL at all, which is what Chrome's VM947 means, and a cross-origin one
is reported as the bare string Script error. with no file, line or message. The filter runs in the
browser and again on the server, because the browser half is part of the code being reported on.
Three kinds appear here:
- Error — an uncaught exception, with its stack.
- Rejection — a promise nobody handled. It carries no filename, so it is kept only when its stack mentions this server.
- Blocked — a Content-Security-Policy violation, sent by the browser itself rather than by plMail. The policy is enforced in production, so these are things this installation actually refused to load in somebody's real browser, which nothing else can tell you. A blocked resource is usually either an extension or a genuine mistake in the policy, and the message names the directive and the URI so you can tell which.
Clear empties the card. Nothing is lost that is still happening — a live fault is reported again by the next page load, which is also how you check that a fix worked.
Everything anybody has told plMail it got wrong about a mail, in one list. There are two kinds and they sit together, because the question you bring to this page — what is still mine to do — does not have two answers:
- No insight — a mail somebody thought the radar should have understood. Kept as a snapshot rather than a link: sender, subject, when it arrived, the beginning of its text, and the reporter's own note about what plMail should have spotted. The snapshot is the point — the mail itself gets archived, deleted or vanishes from the server, and a report that resolves to nothing is a report saying only that something was missed once.
- Wrong tab — a mail somebody found in the wrong inbox category. This one records the decision rather than the message: what each of Gmail, the header rules and the model said, which of them was deciding, which bulk headers the mail carried, and whether there was any plain text for the model to read at all. No body is kept; most of what gets misfiled is HTML-only, so a body column would be empty for exactly the mail most often reported.
The nav entry carries a count of what is still waiting.
The chips above the list are the selector. One row of them filters by state — waiting or handled — and the next by the problem itself, one chip per disagreement this installation has actually produced (Primary → Promotions, No insight). They are built from the rows rather than from a fixed list, because for a wrong tab the problem is a pair of categories and only your mail knows which pairs occur.
Tick the rows you want, or filter to a problem and press Select everything shown. Filtering never unticks anything, so a selection built across two chips survives.
Export hands the selection back as one JSON file: a header saying when it was taken and off which build, then each report in full — every verdict, the headers it was decided on, the message text where there is any, and the same one-line summary the list shows. Select nothing and you get everything. That file is what a rule or a new extractor gets written from. It is a POST rather than a link, for the reason the Backup export is: what comes back is other people's mail, and a URL that produced it could be fetched with your own cookies from a page somewhere else.
Copy selected puts the same reports on the clipboard as plain lines instead — the form to paste into a prompt, an issue, or a message to whoever is changing the rule.
Downloading changes nothing. A report counts as handled when you press Mark handled, not when it has been exported — otherwise a second export would come back empty and the work would be recorded as done by somebody who had not started it. Delete handled reports then sweeps the done pile; it appears only when there is something in it, and names how many.
Two things live here: which file services this installation offers, and the OAuth applications users sign into their mail with.
Mail sign-in holds the Google and Microsoft client id and secret, the Microsoft tenant, and for
Gmail the Pub/Sub topic and push verification token. Leaving any of them empty falls back to the
matching environment variable — GOOGLE_OAUTH_*, MICROSOFT_OAUTH_*, GMAIL_PUBSUB_* — so an
installation already configured that way keeps working untouched.
Calendar access needs nothing extra here. It rides the same sign-in: enable the Google Calendar API
and add the calendar scope to the consent screen, or add the Calendars.ReadWrite delegated
permission to the Entra registration. Without it, mail keeps working and calendars simply do not
appear.
Services lists every file provider, whether or not plMail can talk to it yet. Each has:
- Offer this service to users — off means nobody can connect to it and it stays out of the compose and save-to menus.
- Client ID and client secret, for the OAuth ones, with the exact Redirect URI to paste into the provider's console.
- Server address, for the self-hosted ones. Leave it empty and each user enters their own; set it and every user is pinned to that server.
Reuse Gmail credentials and its Microsoft equivalent copy a client id and secret across server-side, without ever showing the secret. One Google Cloud project also covers Drive and Photos; one Entra registration also covers OneDrive. Copying the credential does not grant the extra permission those services need — that is still a change at the provider.
Secrets are write-only throughout: the form shows whether one is on file, never what it is, and submitting with the field blank keeps the stored one. That is what lets an administrator change a base URL without re-pasting a secret they no longer have. Clearing one is an explicit checkbox, which only appears when there is something to clear.
Providers plMail cannot talk to yet are listed anyway, greyed, with their setup notes readable. The credentials can be registered now and are used as soon as support ships.
Per-provider setup steps are on Google, Microsoft and, for the calendar side, CalDAV.
One screen, and it is only about Firebase. Web Push needs nothing here: its VAPID keys are
environment variables minted once by app:push:generate-vapid-keys, and they serve browsers, the
installed PWA and UnifiedPush distributors alike. A settings page showing them read-only beside an
editable Firebase key would suggest they can be changed from here.
Firebase Cloud Messaging is how a native Android app receives notifications in the background, because Android has no other push service and a plain Android app cannot speak Web Push. It is optional in the fullest sense — a user running a UnifiedPush distributor needs none of it, and the browser app never touches it.
Two files, and neither is any use alone:
- The service-account key, from Firebase console → Project settings → Service accounts → Generate new private key. This is how the server sends. It is stored encrypted with everything else this install holds, and never shown again.
-
google-services.json, from Project settings → Your apps → the Android app. This is how the app initialises Firebase. The plMail Android app is one build published to every installation while every installation has its own Firebase project, so it cannot be compiled in — the values are published in the JMAP session instead and the app builds itsFirebaseOptionsat runtime. They ship inside every Firebase APK and are public by nature, so they are stored in clear.
A pair from two different projects is refused, saying which is which. Nothing downstream can detect that mistake: the app registers happily against one project, the server sends happily to the other, every message is rejected into a log file and the user's symptom is that notifications do not work. This screen is the only place both halves are in one person's hands.
The same goes for the wrong file. The Firebase console offers four downloads that are all valid JSON, so a rejection names the keys the file is missing rather than saying it is invalid.
The toggle is separate from the credentials, so switching FCM off is not the same as losing the key. It cannot be turned on until both files are present — enabling early would advertise FCM to every client and then refuse every registration, which a client cannot tell apart from a bug at its own end. The chip beside the heading distinguishes Live, Configured, switched off, Half configured and Not configured for exactly that reason.
Nothing here needs a restart. That is the whole reason this is a database row rather than an environment variable.
Under the Firebase form, and it covers both transports: every attempt to wake a device, newest first, filterable by user, transport and outcome. It exists because push was the one thing this server did that left no trace — a notification that never arrived looked exactly like one the user did not notice, and the only evidence was a log line written when something went wrong.
Each row is one attempt: when, which user, which device (the id the client chose for itself), the transport, what was being carried, how long it took, and what the far end said.
| Outcome | Means |
|---|---|
| Accepted | The transport took it. Not proof it was displayed — proof it was handed over |
| Failed | Refused or unreachable, and the device was kept. The detail column has the status or the FCM error name |
| Device dropped | The address proved permanently dead (a 410, or UNREGISTERED) and the subscription was deleted. This row is the only explanation of why the device disappeared from the user's list |
| Skipped | Nothing was sent: the transport is not configured, or the row cannot address it. Not a failure — a deployment that has not been finished |
The Skipped distinction is the one to read carefully. An install with no VAPID keys, or with Firebase switched off, produces a skip per device per state change, and that is a configuration answer rather than a broken device.
What was pushed is deliberately not recorded. The log holds the payload's type — StateChange
or PushVerification — and nothing else of it. A StateChange names the accounts and state tokens
that moved, so keeping it would turn this table into a retained, admin-readable index of when each
person's mail arrives, which is a bigger thing than the question it would help answer.
Users see their own half of this, without the other users, in Settings → Notifications: each registered device with its transport, whether the verification handshake completed, and its last delivery.
Retention is 30 days, swept nightly by app:monitoring:prune; --push-days=N changes it.
Single sign-on: the OpenID Connect provider people sign in to plMail through — Authentik, Keycloak, Authelia and the like. One form: the issuer, the client ID and the client secret out of the provider's console, the name the login button carries, and two switches for how accounts are matched. The page shows the redirect URI to register at the provider, and a chip that says whether sign-in is On, On, from the environment or Off.
Saving takes effect at once. The client secret is write-only, like every credential in this area:
the field never shows a stored one, and leaving it empty keeps it. Setup step by step, what each
switch does and the OIDC_* variables that stand in when nothing is saved here are in
Single sign-on.
This is the one admin page that decides who can sign in. Whoever can save it can point plMail at a provider of their own and sign in as any account that has no second factor — see the page above before handing out administrator accounts.
Optional, off by default, and plMail is a complete mail client with it off. Nothing here is switched on until you switch it on. Mail is sent to the model host you enter and nowhere else: with a model on a machine you own, nothing leaves your network.
Provider is the API the model host speaks. There are two:
| Provider | What it is | What plMail can do with it |
|---|---|---|
| Ollama | An Ollama container, usually on your own network | Everything on this page |
| OpenAI-compatible | Anything that answers /chat/completions and /embeddings in OpenAI's format: llama.cpp, vLLM, LM Studio, LiteLLM, a hosted provider, or Ollama under /v1
|
Writing, summaries, sorting and search. Not the keep-alive fields or Warm up now |
The OpenAI format has no way to ask what a host holds in memory, to keep a model loaded, or to load one ahead of time. With that provider chosen, the two keep-alive fields and Warm up now are put away, and the model host card on Admin → Performance shows whether the host answers and what the calls cost, without the "in memory" half. Their values are kept, so switching back loses nothing.
If you choose a hosted provider, your mail goes to it. Sorting sends every arriving message that no rule recognised; search sends every message once to index it and every query; writing help and summaries send what you ask them about. Hosted providers usually charge per request. plMail never falls back to another host and never sends anything to an address you did not enter.
Model host is the address. For Ollama that is the container, including the port —
http://10.0.0.5:11434. For an OpenAI-compatible endpoint it is the API root including its version,
such as https://api.example.com/v1; plMail adds /chat/completions and the rest to exactly what you
type. Token is the API key of a hosted provider, or only needed if you have put the host behind
something that asks for one; Ollama itself has no authentication. It is sent as a bearer token
with every request to that address, and it is stored for that address: change the model host without
typing a token and the stored one is dropped, so it is never sent to a host it was not issued for.
Changing the provider counts as changing the address. Redirects are not followed once a token is
attached, and never for an OpenAI-compatible endpoint: the answer is reported as the status it is.
Extra headers are for whatever stands in front of the model and wants more than a token: a
reverse proxy with basic auth, a zero-trust gateway that takes a client id and a secret, a routing
or logging gateway with a key of its own, a provider that selects a project by header. Write one per
line as Name: value:
CF-Access-Client-Id: 1a2b3c.access
CF-Access-Client-Secret: …
They are sent with every request to the model host, for either provider, and stored encrypted. The
page lists the names of what is stored and never shows a value again. Leaving the box empty keeps
them; typing anything replaces all of them; Remove the stored headers drops them. Like the token,
they are dropped when the address or the provider changes. An Authorization header typed here is
sent in place of the token, which is how basic auth is written. The headers plMail writes itself,
Host, Content-Type, Content-Length and the like, are refused. The setup wizard leaves this
field out; it is on Admin → AI only.
Two models, because the jobs are different. The writing model should be instruction-tuned and is
used for drafting and sorting; the search model is an embedding model and is usually much
smaller. llama3.1:8b and qwen3-embedding:0.6b are reasonable starting points. Both have to be
pulled on the host first — plMail never downloads a model.
Search uses a different model host gives the search model its own provider, address, token and extra headers. It is off by default, and while it is off search asks the model host above like everything else does.
The two jobs often want different machines. Writing wants the largest model you can run or rent. Search wants a small one that is asked constantly: every query, and every message of a mailbox once to index it. Two arrangements come up most:
| Writing | Search | Why |
|---|---|---|
| A hosted, OpenAI-compatible endpoint | An Ollama at home | Good drafts without owning a large GPU, while the mailbox is indexed on a machine you own and nothing is billed per message |
| An Ollama at home | Another host | The GPU that writes is not interrupted by indexing |
Each host is sent only its own token and headers. A search host with no token is sent none; it never borrows the other host's. Test asks both hosts, each for the model that lives on it.
The index belongs to the model, not to the address. Moving search to another host that serves the same model, under the same name, keeps the existing index. A different model name is a new index, as it always has been: start a pass from the card below. If the name is the same but the model is not, plMail cannot tell; give it a different name, or the old and new vectors are searched together and the results are poor.
The search model's keep-alive is shown when the host search runs on is an Ollama, whichever host that is. The model host card on Admin → Performance reads the host that writes, and does not report on a search model that lives elsewhere. The setup wizard leaves this out; it is on Admin → AI only.
Underneath the search model are a query instruction and a minimum similarity, and the three fields are really one decision. Any two of them from different models produce a search that is confidently wrong rather than obviously broken, which is the worst way for this to fail: the results look ordered and complete and simply are not about what you asked for.
- The query instruction goes in front of your search text before it becomes a vector. Most embedding models are trained to be told which side of a search they are looking at, and a query that arrives unlabelled is treated as one more document — so it lands nearest whatever is most boilerplate, which in a mailbox means login links and newsletters. It only ever affects searches, so changing it never means indexing your mail again.
- The minimum similarity is how close a match has to be, from 0 to 1. Every model answers on its own scale and there is no number that is right twice. Too high finds nothing; too low returns the whole mailbox in a meaningless order.
The row of presets above them fills all three at once from models this release has actually been measured against, each with a line on what it is good and bad at. The model field stays free text — run whatever you like — but if you type a name that is not one of the presets, the instruction and the threshold are yours to set, and neither has a sensible guess plMail could make for you.
qwen3-embedding:0.6b is the default because it is multilingual, which matters more than any
benchmark score for a mailbox that is not all in one language.
Test asks that host what it is holding, without saving anything. Use it before you save: it will tell you the difference between "nothing answered at that address" and "that host answered but is not holding the model you named", which send you to two different places.
For an OpenAI-compatible endpoint, Test reads its model list at /models. It separates three more
answers: the host refused the token, the address answered with something that is not the API (a
login page, usually), and the address has no model list. The last one most often means the address
is missing its /v1. A few servers have no list and work regardless, so it is a warning and not a
verdict: save, and try a draft.
This section is about Ollama. An OpenAI-compatible endpoint decides for itself what it keeps loaded, and the fields below are not shown for it.
Ollama drops a model out of memory a few minutes after the last request, and reading it back off disk is the whole of the wait on the first "Help me write" after a quiet spell — a 20 GB model takes tens of seconds to load, during which the host produces nothing at all. The keep the writing model loaded for and keep the search model loaded for fields are how long plMail asks the host to hold each one.
Write a duration — 5m, 30m, 4h — or a plain number of seconds. -1 keeps the model loaded
indefinitely, 0 unloads it as soon as each request finishes. Longer means a faster first answer,
and the host keeps that memory reserved for the whole time whether anyone uses it or not.
Both ship at 5m, which is Ollama's own default — so out of the box plMail changes nothing about
how your host behaves, and the boxes simply say what is already happening.
-1 is worth considering for the search model, and it does not ship that way only because plMail
cannot see how much memory your host has. That model is small and asked for constantly — every
search by meaning, and every message being indexed — so pinning it usually costs a rounding error of
memory and saves a wait every single time. If the host has the memory to spare, set it.
Leave either box empty to send nothing at all, in which case whatever OLLAMA_KEEP_ALIVE says
on the host itself applies. plMail cannot read that variable, so an empty box is the only way to say
"leave this to the host".
Warm up now loads the writing model straight away and tells you how long it took. "Loaded in 41 s" means it came off disk; "loaded in 30 ms" means it was already resident and the click bought nothing. Useful after a restart, and useful for finding out what a cold load actually costs on your hardware before you decide how long to hold it.
They have very different costs, and very different consequences when the model is wrong.
| What it does | When it runs | |
|---|---|---|
| Search by meaning | Adds results matching what you meant, not only what you typed | On every search, and once over your mailbox |
| Sort mail into tabs | Fills in a category when no rule recognised the message | On every message that arrives |
| Help me write | Offers drafts and rewrites in the composer | Only when you ask |
| Thread summaries | Writes a short account of a long conversation | Only when somebody asks for one |
Sorting is the one to be careful with: it runs unattended. It can only ever act as a tie-breaker — if a header, a Gmail label or the fact that you have written to somebody already decided the category, the model is not consulted and its opinion is not used. Switching it off needs no cleanup.
Two things keep sorting from getting in the way of mail arriving:
- Only recent mail is sorted as it comes in. Mail from the last 30 days is asked about straight away. When you add an account, the rest of its mailbox is sorted afterwards, in the background, newest first, and only once the import has finished — so a first import is not hours of model calls with new mail waiting behind them.
- Wait for the assistant before showing new mail in a tab. For people who let the assistant sort their mail, new mail is kept out of the inbox tabs for the moment the assistant needs, so it shows up once, in the right tab, instead of appearing in one and moving to another. Wait at most is the ceiling, 60 seconds by default: past it, the mail is shown where the ordinary rules put it, and moved if the assistant answers later. It is a ceiling, not the wait — a model that is already loaded answers in a second or two. The line underneath reports how long mail was actually held over the last 7 days, and how often the wait ran out — if that is most of the time, your model host is too slow for the wait to be worth it, and you can switch it off. Mail brought in by a first import is never held.
Writing help never replaces what you wrote. It appends, so the original is always still there.
Summaries are the most expensive of the four. They use the same writing model, but a whole conversation is a much larger prompt than a draft: on a 30B model and one GPU, expect around a minute for the first summary after a quiet spell and around half that once the model is warm. The GPU is held for the whole of it, so on a shared machine a summary is felt by everybody. Nothing is ever summarised on its own — no arriving message, no nightly pass — and a summary that has been written is kept and shown again, so opening the same conversation twice costs nothing the second time.
Semantic search can only find mail it has indexed, and switching the feature on indexes nothing on its own. Everything already in the mailbox needs one pass:
docker compose exec php php bin/console app:ai:embed-mailbox --email=you@example.comIt runs on the maintenance worker a chunk at a time and takes hours on a large mailbox. It is safe to interrupt and safe to run again — it skips whatever is already embedded, so a second run costs almost nothing. Changing the search model invalidates every stored vector, which is how you ask for a re-embed: change it, then run the pass again.
Ordinary search is completely unchanged by any of this. If the model host is off, or the pass has never been run, search works exactly as it always has.
The first time somebody asks, plMail writes the summary and stores it against the conversation, so the next person to open it — or the same person tomorrow — reads it without waiting. plMail works out for itself whether it is still true: it compares what the conversation says now with what was summarised, so a reply arriving marks the summary as out of date while merely reading, starring or labelling the conversation does not.
An out-of-date summary is still shown, greyed, with the date it was written and a button to write a new one. It is usually still mostly right, and hiding it would throw away the wait somebody has already paid for.
Changing the writing model stops every stored summary being shown, the same way changing the search model invalidates every stored vector: a summary written by a model you no longer run is not a summary of yours. Nothing has to be cleaned up — the old text is simply not offered, and is replaced the next time anybody asks.
Mail is not indexed the moment it arrives. Indexing costs a request to the model host per message, and mail you have just read is the mail you are least likely to go searching for — so plMail waits for one of two moments instead:
- Just after you search. Searching by meaning loads the search model to turn your query into a vector, and indexing uses that same model — so once it is loaded and warm, plMail quietly indexes a small batch of your newest unindexed mail in the background. Your search does not wait for it, and it happens at most once every few minutes however much you search.
- Once a night, as a backstop, so mail still becomes findable if you have not searched for a while.
In practice that means mail that arrived in the last few minutes may not be findable by meaning yet. Ordinary search finds it immediately, as it always has, and one search is usually enough to pull the rest in.
A mailbox that is a long way behind — the feature was switched on last week, or you changed the
search model — is not what the nightly pass is for. It has a ceiling per mailbox on purpose. Run
app:ai:embed-mailbox above, and watch Admin → AI for how far it has got.
A searchable, paged list of everyone who can sign in, with when they last signed in and whether they have two-factor authentication on.
Add user takes an email address, a name, an initial password of at least twelve characters, and an Administrator checkbox. The length floor is higher than you might set for yourself on purpose: the person choosing this password is not the person who will use it, so length is the only control available.
Three things an administrator deliberately cannot do, all for one reason — an admin session must not become a second way into every mailbox on the install:
-
Change an existing user's password. The field exists on create and not on edit. Someone who
has not signed in yet has no mail, so setting their initial password discloses nothing; changing
it afterwards would. A forgotten password is reset with
app:user:passwordon the console. -
Remove anyone's second factor. That is
app:user:2fa-disableon the console, and only there. - Read anyone's mail. Nothing in this area touches an account or a message.
The search box filters on address and name, from the first character you type. It is a plain
substring match, so an finds both Anna and Yohanna.
The padlock on a row suspends the account. The person cannot sign in, every mail client already connected with an app password stops too, and any session they had open ends on their next page load — but nothing of theirs is touched. The address, the name, the password, the second factor, the accounts, the mail and the labels are all exactly where they were, and the open padlock switches the account back on.
This is the answer to a colleague on leave, a machine that looks compromised, or somebody whose access should stop while the reason is worked out. It is deliberately not the same decision as removal, which cannot be taken back.
Switching your own account off is refused, for the same reason removing it is: it is one click from having nobody who can undo it. Switching an account back on is never refused — the account most likely to need it is exactly the one a stricter rule would have trapped.
A suspended account shows a Switched off badge in the list and stays where it was, findable by the same search that found it before. Somebody suspended who tries to sign in is told the account was switched off by an administrator — but only once they have typed the right password, so the login form is not a way to discover which addresses on the install are suspended.
Remove user is a soft delete. The address and the display name are freed — the address is unique, so leaving it would stop the same person ever being re-added — and the row stops being able to authenticate, but the accounts, messages, labels and app passwords hanging off it stay where they are. A cascade from a misclick in an admin panel is not a recoverable mistake.
There is no Restore button, and there deliberately is not one. Removal frees the address by
overwriting it, so a removed row no longer knows who it was: the address is deleted-<id>@invalid,
the name is "Deleted User", and the password hash is gone. Restoring would have to invent all three,
and the address it used to hold may by then belong to somebody else. If what you want is "stop this
person signing in, and let them back later", that is switching the account off above — which is
why it exists. The mail of a removed user is still in the database and an operator with database
access can still reach it.
Two removals are refused outright: your own account, and the last remaining administrator. The second is the one that looks fine at the time — an admin removes a colleague, and nobody notices until the next time somebody needs the panel. Demoting yourself, or the last administrator, is refused for the same reason, and the panel now says so rather than saving the rest of the form and leaving the checkbox looking broken.
Changing your own password is not here at all — it is in Security, under each person's own settings.
Everything this installation is configured with, in one password-encrypted file — and the way to put it back. Not mail: no messages, no calendar events, no attachments. It does carry the people — every account on the install, with their password hashes, two-factor secrets, app passwords and every mailbox credential they have saved. See Configuration backup for the whole story, including the file format, which is documented so the file never depends on plMail being able to run.
Export asks for a password twice and downloads plmail-config-<date>.backup. The password is
never stored and there is no recovery for it. The file carries every secret the install has,
including the decrypted contents of the encrypted columns — that is deliberate, because the install
it will be opened on has a different APP_ENCRYPTION_KEY and ciphertext would be unreadable there.
Keep the file as carefully as you keep the key itself.
Import takes the file and the password and shows a review before anything is written. The review has three parts, in descending order of how much they should concern you:
-
What plMail writes itself, which is nearly everything: the Firebase project, the mail OAuth
registrations and the integration providers, re-encrypted with this install's key and live on
commit — plus the JWT keypair and every environment value, into
var/secrets/generated.envand the files beside it. Those are the files the container entrypoint reads when it starts, so they are in place at once and in force after one restart. The page says that once, for the whole list. - What is still yours to do, which on a stock stack should be empty: it fills only when your compose file pins a value to something non-empty, which then overrides the restored one at the next start. Each comes back with the exact line and the reason it is here, and a list that is not empty is worth reading rather than skimming.
- A disclosure headed "Also restoring the old database? You will need its old encryption key",
which explains why
APP_ENCRYPTION_KEYis deliberately not written: the credentials the import just wrote are encrypted with the key currently in force.
Each line also says whether it is new here, replaces something different, or already matches. That middle state is worth stopping at: restoring onto a running install replaces live credentials.
The same import runs during first-time setup, below the account form on /install, so a new
installation can be brought up configured before its administrator exists — upload and password are
the whole job there, and the instance comes up as the old one after a restart. That entry point
closes with a 404 the moment the first account is created.
app:reset, as buttons. Six stages, each deleting everything the one above it does and more:
| Stage | Deletes |
|---|---|
| Synced mail | Messages, threads, parts and anything queued. Accounts, folders and labels stay; sync cursors are cleared |
| Mail and mailbox structure | The above, plus folders and labels. The next sync rebuilds both |
| Mail, structure and contacts | The above, plus harvested contacts. Address autocomplete starts empty |
| Mail, structure, contacts and accounts | The above, plus the accounts and their aliases. Every mailbox password and OAuth connection has to be set up again. Your own sign-in is untouched |
| Full reset | Every user, you included, every stored password, and the files on disk |
| Full reset and new secrets | The above, and the generated secrets |
The top four are confirmed with a dialog: the worst case is a resync, which costs hours and no information. The bottom two require the instance name — the host plMail answers on — to be typed into the form, and that is checked on the server, not in JavaScript. A click on its own is not enough for an operation nothing brings back.
A full reset does not redirect anywhere. It cannot: the user who performed it no longer exists, so there is no page left behind the firewall, and the response itself is the only chance to say what happened and what still needs doing.
Monitoring data is kept by every stage. Clear the logs from Logs, and stale heartbeats from Maintenance.
- Files and integrations — what a user sees once you enable a service.
- Accounts and aliases — the sign-in you are configuring, from the other end.
- Troubleshooting — the failures that have actually happened.
-
Configuration reference —
APP_DB_LOG_LEVEL, the OAuth variables, the Pub/Sub ones. - Architecture — what the workers, scheduler and supervisor are.
Mail that arrived a minute ago is not searchable by meaning yet. Indexing happens after a search and once a night, not on arrival — so the first search of the day is the one that pulls the day's mail in, and it pulls it in for the search after it, not for itself. Ordinary search finds new mail straight away, which is why this is usually invisible.
The reported-mail export is other people's mail. It is a plain, unencrypted JSON file holding the text of messages your users decided to hand over — unlike the config backup, which is encrypted with a password you choose. Keep the file where you would keep the mailbox itself, and delete it when the work is done.
Rotating the secrets without restarting the whole stack breaks half of it. Every other service
keeps the old APP_ENCRYPTION_KEY in process memory until it restarts, so anything saved in the
meantime becomes unreadable to the services that did not. The panel says so; the restart is not
optional.
POSTGRES_PASSWORD is never rotated, deliberately. Postgres was initialised with it and keeps
its own copy, so regenerating it would leave plMail unable to log in to the database it just reset.
Changing that one means wiping the database volume, which the panel cannot do.
The maintenance buttons queue work, they do not do it. Nothing happens if no worker is consuming — the scheduler and worker containers have to be running. Without them, none of the scheduled sweeps fire either.
A worker holding stale Doctrine metadata survives a migration and fails oddly. Long-running processes cache mappings for their whole lifetime, so a column added by a migration is invisible to them until Restart workers. This is the thing to try first when a queue starts failing straight after an upgrade.
Clearing logs deletes what the filter matches, not just the page. The count in the confirmation is the real number.
Successful Gmail pushes are invisible at the default log level. They are logged at info and not
stored, so "no events" in the webhook panel does not mean "nothing was delivered" until
APP_DB_LOG_LEVEL=info is set.
Enabling pg_stat_statements from the panel starts collection from that moment. Queries from
before it will never appear, so an empty panel immediately afterwards is expected.
Copying credentials with "Reuse …" does not grant the extra permission. It copies a client id and secret and nothing else; the scope or delegated permission still has to be added at the provider, or connecting fails at consent time.
You cannot remove the last administrator, or yourself. Both are refused rather than warned about, which occasionally reads as a broken button. The same pair cannot be switched off either, and unticking Administrator on your own account now says why instead of quietly not saving it.
A removed user cannot be restored. Removal overwrites the address and the name in order to free the address for reuse, so there is nothing left to restore them to. Switch the account off instead whenever the answer might later be "let them back in".
Switching an account off does not sign the person out of a mail client immediately. The web session ends on their next page load, and an app password stops working on its next request — but a client that is idle will not notice until it next syncs.
Rotating APP_ENCRYPTION_KEY takes the Firebase key with it. The service-account JSON is stored
encrypted like every other credential, so a changed key makes it unreadable — push over FCM goes
quietly off, the session starts saying fcm: false, and the fix is to paste the key again. The
google-services values survive, because they were never encrypted.
Replacing only one of the two Firebase files is refused if the projects differ. That is
deliberate and it is the message to read rather than work around: a service-account key from one
project with a google-services.json from another produces an installation where everything looks
configured and nothing is ever delivered.
An empty delivery log means nothing was attempted, not that everything worked. Push only fires when a state actually changes and only to devices that finished the verification handshake, so a fresh install with one browser registered can sit empty for hours and be perfectly healthy. The panel distinguishes "nothing matches this filter" from "nothing has ever been pushed" for exactly this reason — the second line is the one that means check the configuration above.
"Accepted" is not "delivered to a human". It means the push service took the message. A phone in a doze state, a browser that revoked permission at the OS level, and a notification the user swiped away all look identical from here, and the next thing to check is the device rather than this page.
The delivery log is pruned at 30 days, so a device retired six weeks ago has no row explaining it. If somebody reports notifications stopping "a while ago", look before assuming nothing was ever tried.
This page is generated from docs/features/admin.md. Edit it there — changes made here are overwritten on the next push to main.